September 22, 2026 · 69 runs · Code quality protocol v3.11
Devin SWE-2 across every effort level
69 runs through the Devin CLI on a Devin subscription, 23 tasks at each of the three effort levels SWE-2 offers. Scored with Code quality at 33% of the combined score and judged for a human reader under the same frozen protocol as the other Frontier v4 reports, with one difference that shapes the whole page: Code quality here comes from a single judge, Muse Spark 1.3, because both candidates for the second seat failed their calibration exams. Every other entry on the Frontier v4 leaderboard is scored by a two-judge panel.
Across every effort level
Devin SWE-2 ran every task once at each of its three effort levels, 23 tasks per cell, through the Devin CLI (devin 3000.10.31) on a Devin subscription on September 18 to 21, 2026. SWE-2's catalog lists exactly three levels, medium, high and max; there is no lower level and no level above max. Combined score weights are 50% functional correctness, 8.5% lint and complexity, 8.5% security and 33% Code quality, judged for a named human reader by Muse Spark 1.3 with a ground-truth intent-recovery probe. Judging ran on September 21.
Medium and high are indistinguishable. They score 82.43 and 81.42, their standard errors overlap, and both pass 15 of 23 tasks. Only Max moves: 86.14, and 21 of 23 tasks passed. Devin is also slow and token-heavy next to the Codex models measured on this suite: 35 to 57 minutes and 7.53M to 16.80M raw tokens per task, against about 10 to 12 minutes and 1.8M to 2.8M for GPT-5.6 Sol. Its cost cannot be reported: Cognition publishes no rate for SWE-2.
Combined score
82.43 at medium, 81.42 at high, 86.14 at Max
The ladder is flat then a step. High scores 1.01 points below medium with standard errors of 2.00 and 2.98, so the two levels are not separated by this sample. Max is 3.71 points above medium.
Tasks passed
15 of 23 at medium and high, 21 of 23 at Max
Functional correctness is where Max earns its lead. Medium and high pass the same number of tasks; Max passes six more than either.
Code quality
65.14 to 69.17
Rises about four points across the three levels, with standard errors of 1.81 to 2.91, so the medium to high step sits inside the noise and only Max is clearly above medium.
Runtime and cost
35.1 to 56.6 min · cost unavailable
Runtime does not track the ladder: high is the fastest level and Max the slowest. Cost is not reported at all: Cognition publishes no per-token rate for SWE-2, so there is nothing to price these runs against.
| Metric | Medium | High | Max |
|---|---|---|---|
| Combined score | 82.43 | 81.42 | 86.14 |
| Standard error | 2.00 | 2.98 | 1.31 |
| Tasks passed | 15/23 | 15/23 | 21/23 |
| Code quality | 65.14 | 66.26 | 69.17 |
| Human readability | 54.3 | 57.9 | 61.4 |
| Minutes per task | 49.8 | 35.1 | 56.6 |
| Output tokens per task | 220K | 137K | 171K |
| Cost per task | unavailable | unavailable | unavailable |
The tasks-passed row counts every run the sweep attempted, since all four unjudged runs failed their tests. Under the prior 50/15/15/20 profile applied to the same Code quality scores the shape is the same, 85.46 at medium, 84.01 at high and 88.10 at Max. The card and the full per-effort table follow.
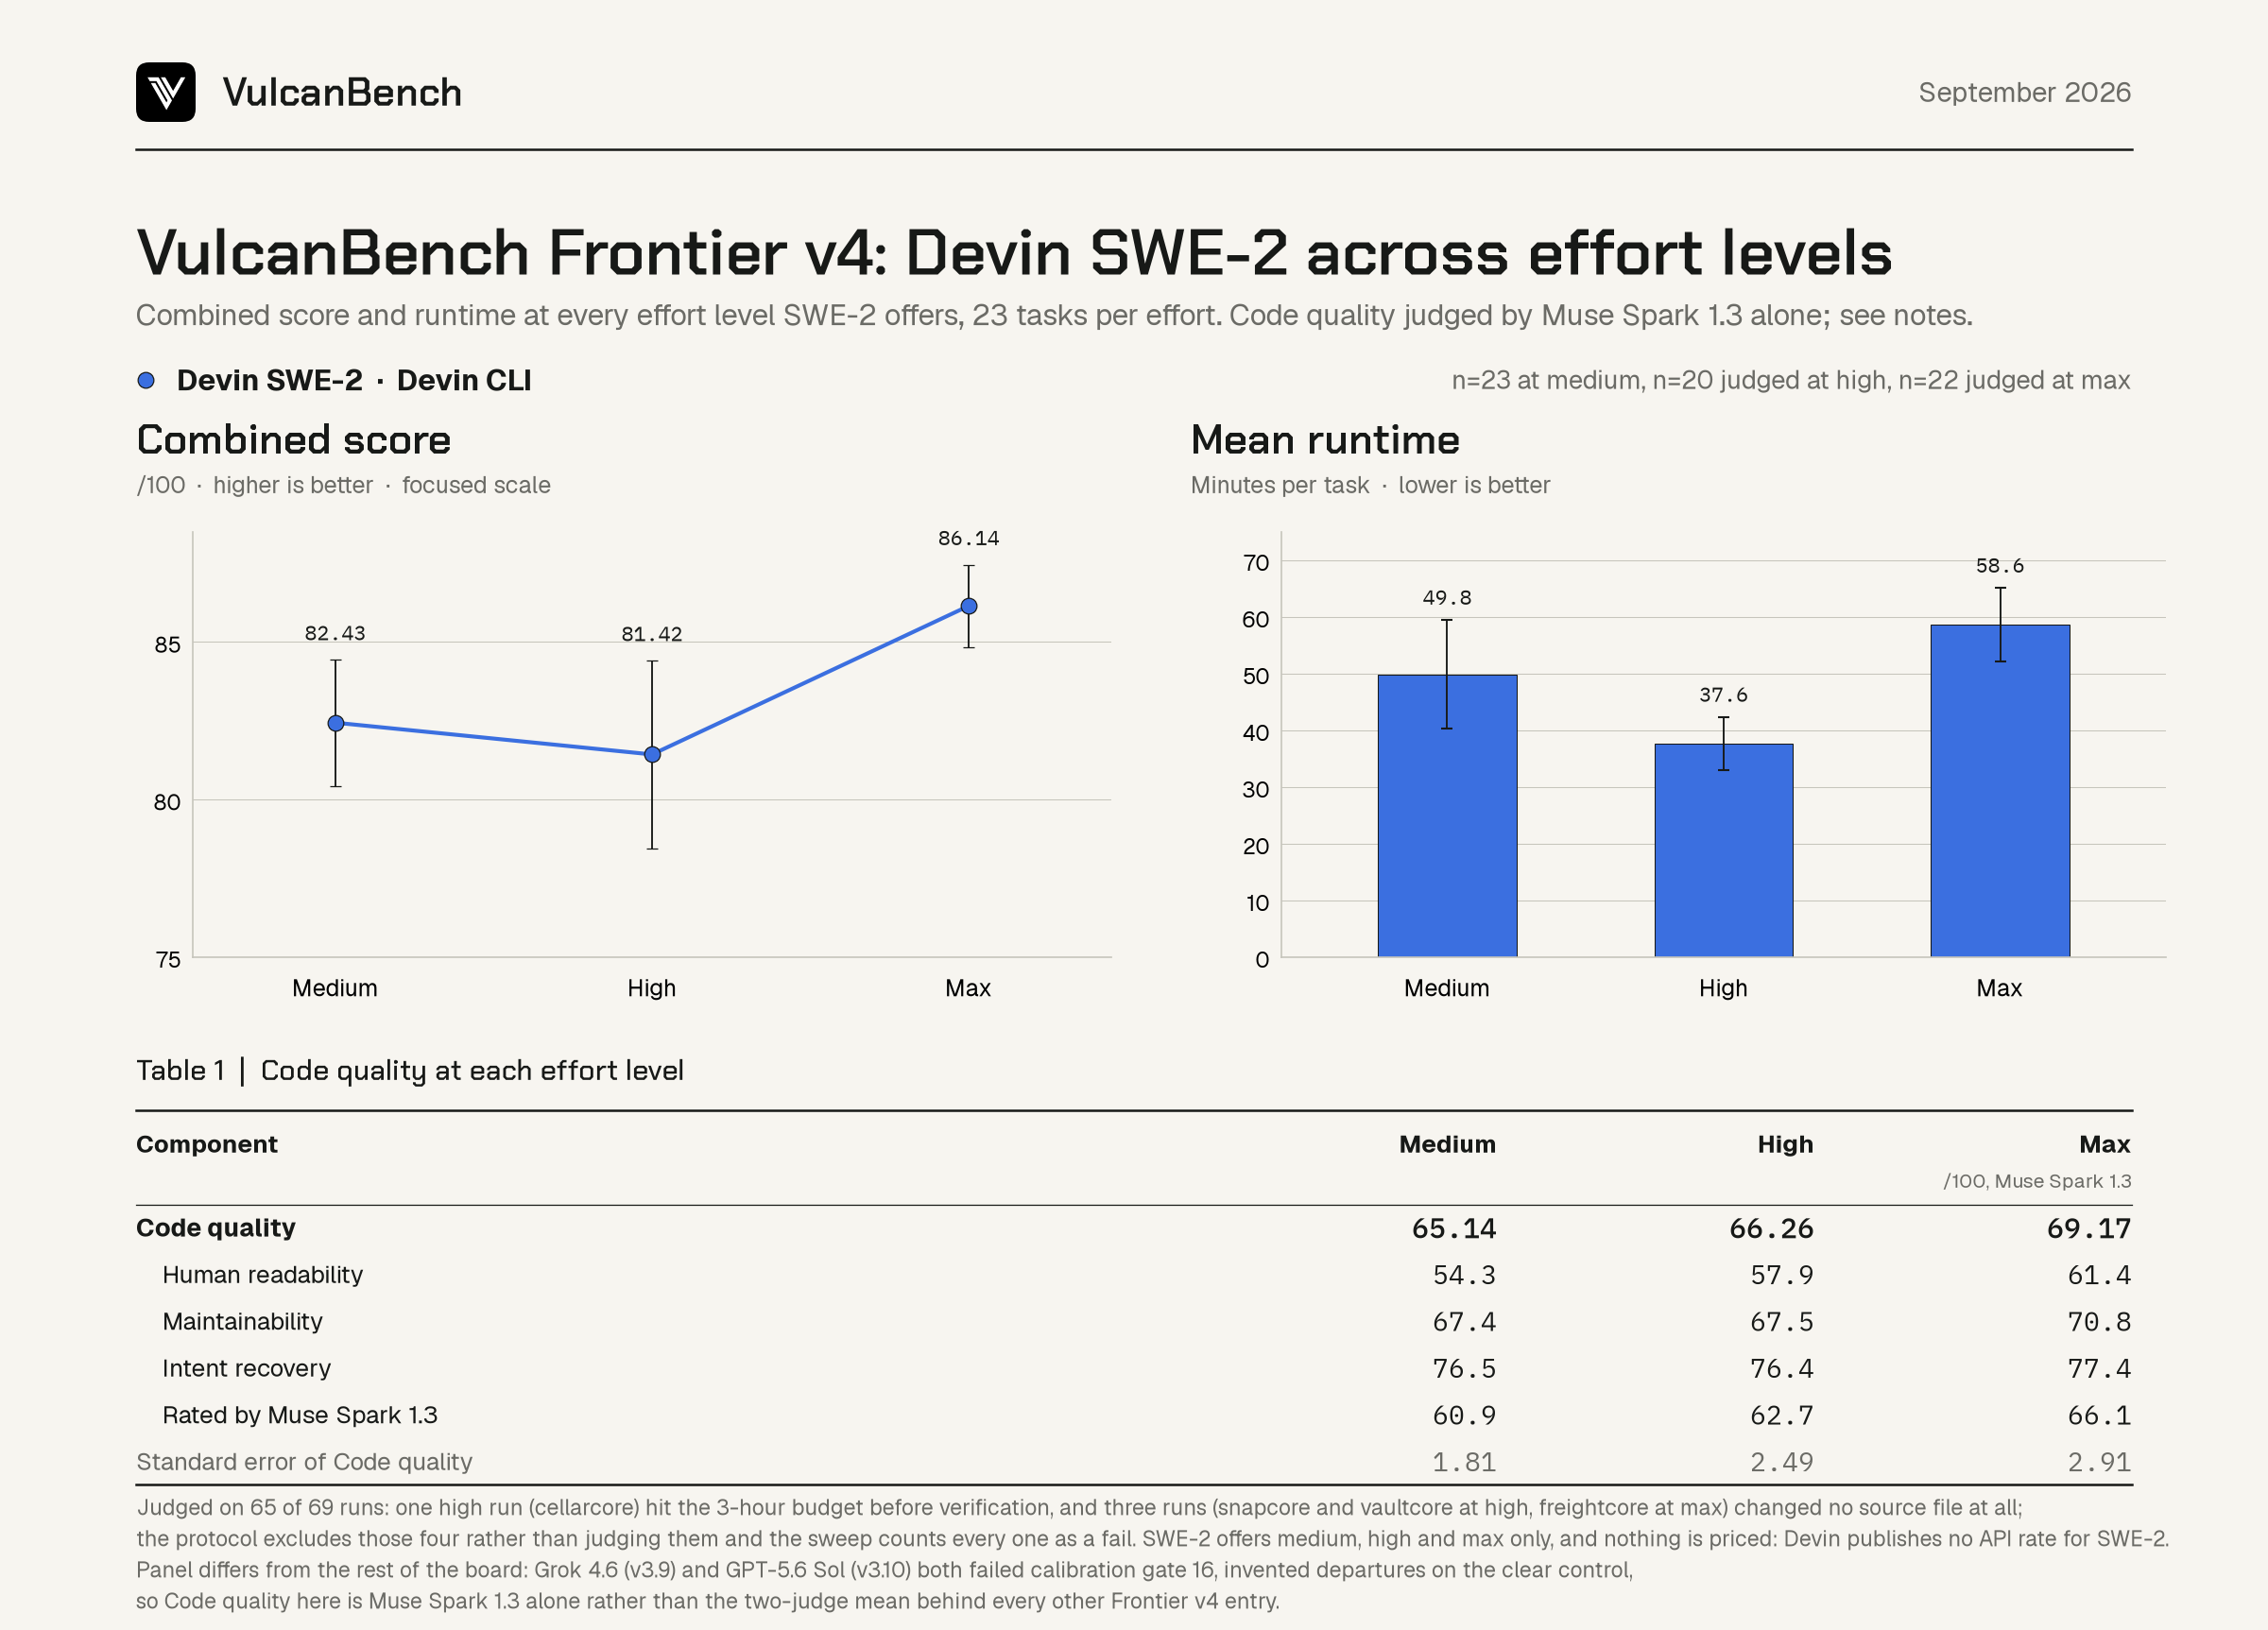
SWE-2's effort knob buys nothing between medium and high on this suite, and buys six tasks and about four points of Code quality at Max. These runs compare a model-and-harness combination, not an isolated base model, and the panel note in the next section applies to every Code quality figure on this page. The Frontier v4 leaderboard places every effort level beside the other models judged under the same protocol.
What was judged, and by whom
One judge, not two. Every other Frontier v4 entry is scored by a neutral two-model panel: Muse Spark 1.3 (Meta) and Grok 4.6 (xAI). Devin SWE-2 is scored by Muse Spark 1.3 alone. Grok 4.6 failed the calibration exam under protocol v3.9 and GPT-5.6 Sol, admitted under v3.10 to fill the second seat for this population only, failed under v3.10. Both failed the same gate, gate 16, the probe on the clear control: a program with no documented departure from its specification must draw an empty probe on at least four of five repeats, and each judge reported invented departures instead, Grok on two repeats and Sol on four. Gate 16 is boolean, so the pre-registered one-gate allowance cannot excuse it, and under the protocol's pre-registered single-panel rule no judge retakes a gate it failed. Both verdicts are published: they are in calibration.json beside Muse's passing one, and the harness records are in the operations log. Read every Code quality number on this page as one judge's rating.
65 of 69 runs are judged. Four runs produced nothing to judge and the population builder excluded them rather than scoring them. All four failed their tests and count as fails in the sweep's pass counts, so the exclusions do not flatter Devin's functional results.
| Effort | Task | Reason | Functional |
|---|---|---|---|
| High | cellarcore | Reached the 3-hour task budget before verification, so the run did not finish and has no receipt | 0 |
| High | snapcore | Changed no recognized source file, only file modes on the legacy binaries | 0 |
| High | vaultcore | Changed no recognized source file | 0 |
| Max | freightcore | Changed no recognized source file | 0 |
A run that produced no code has nothing to judge, and the sweep's automated quality and security metrics are undefined for it by construction, so protocol v3.11 excludes such a run the way it excludes an unfinished one and lists it with the reason. The judged cells are 23 at medium, 20 at high and 22 at Max. Code quality and the combined scores are means over those judged runs; runtime and tokens cover all 68 finished runs, the three that changed no source file included. The one run that did not finish has no receipt, so its 3.0 hours of wall clock sit outside the token and runtime totals and are recorded separately in runs.json.
Combined score and Code quality by effort
n=23 judged at medium, n=20 at high and n=22 at Max; the excluded runs are listed above. Combined (33%) is the published score. Combined (20% profile) applies the prior 50/15/15/20 weights to the same Code quality scores for comparison. Code quality, human readability, maintainability and intent recovery are out of 100 and come from the scored panel; the note below the table says which judge that is. Passed counts judged tasks with a perfect functional score; the sweep's own counts are 15, 15 and 21 of 23, since every excluded run failed. Runtime is solver wall-clock per task over every finished run in the cell.
| Model / harness | Effort | Combined (33%) | SE | Combined (20% profile) | Code quality | Human readability | Maintainability | Intent recovery | Passed | Min/task |
|---|---|---|---|---|---|---|---|---|---|---|
| Devin SWE-2 / Devin CLI | Medium | 82.43 | 2.00 | 85.46 | 65.14 | 54.3 | 67.4 | 76.5 | 15/23 | 49.8 |
| Devin SWE-2 / Devin CLI | High | 81.42 | 2.98 | 84.01 | 66.26 | 57.9 | 67.5 | 76.4 | 15/20§ | 35.1 |
| Devin SWE-2 / Devin CLI | Max | 86.14 | 1.31 | 88.10 | 69.17 | 61.4 | 70.8 | 77.4 | 21/22§ | 56.6 |
§High is judged on 20 of 23 tasks and Max on 22 of 23. Three runs (snapcore and vaultcore at high, freightcore at Max) changed no recognized source file, only file modes on the legacy binaries, so there was no submission to review and the sweep's automated quality and security metrics are undefined for them. A fourth (cellarcore at high) reached the 3-hour task budget before verification and did not finish. All four scored 0 functionally, so the sweep's pass counts are 15, 15 and 21 of 23 and are unchanged by the exclusions. The three finished exclusions keep their runtime and tokens in every economics figure.
Code quality on this page is one judge's rating. Muse Spark 1.3 scored it alone, under the protocol's pre-registered single-panel rule, after Grok 4.6 and GPT-5.6 Sol failed calibration gate 16. Intent recovery is scored over the specification departures a submission actually passed tests for. One high run passed none, so its Code quality is the reviewed score alone under the pre-registered redistribution. SE is one sample standard error of the combined score across the cell's tasks. It describes task sampling, not judge uncertainty, repeated runs or a significance test. No solver fallback occurred, and the judge produced no reviewer fallback on any of the 65 submissions.
Cost and tokens across effort levels
Cost per task is unavailable, and that is the published value. Cognition publishes no per-token rate for SWE-2. The cost tier "Free" in Devin's catalog is a promotion dated through 2026-10-10, not a rate, so a figure taken from it would read as a measured price and would stop being true in under three weeks. No cost is estimated here, on this page or in the evidence bundle, and SWE-2 is not compared on cost with the priced models on the Frontier v4 leaderboard. Tokens, runtime and Devin's own credit and ACU counters are recorded instead.
What the sweep does spend is time and tokens, and it spends a lot of both: 776 million raw tokens and 53.7 hours of solver wall clock over 68 finished runs, an average of 11.41M tokens and 47.3 minutes per task. Neither follows the effort ladder. Medium is the heaviest level at 16.80M tokens per task, high the lightest at 7.53M and the fastest at 35.1 minutes, and Max sits between them on tokens while being the slowest at 56.6 minutes.
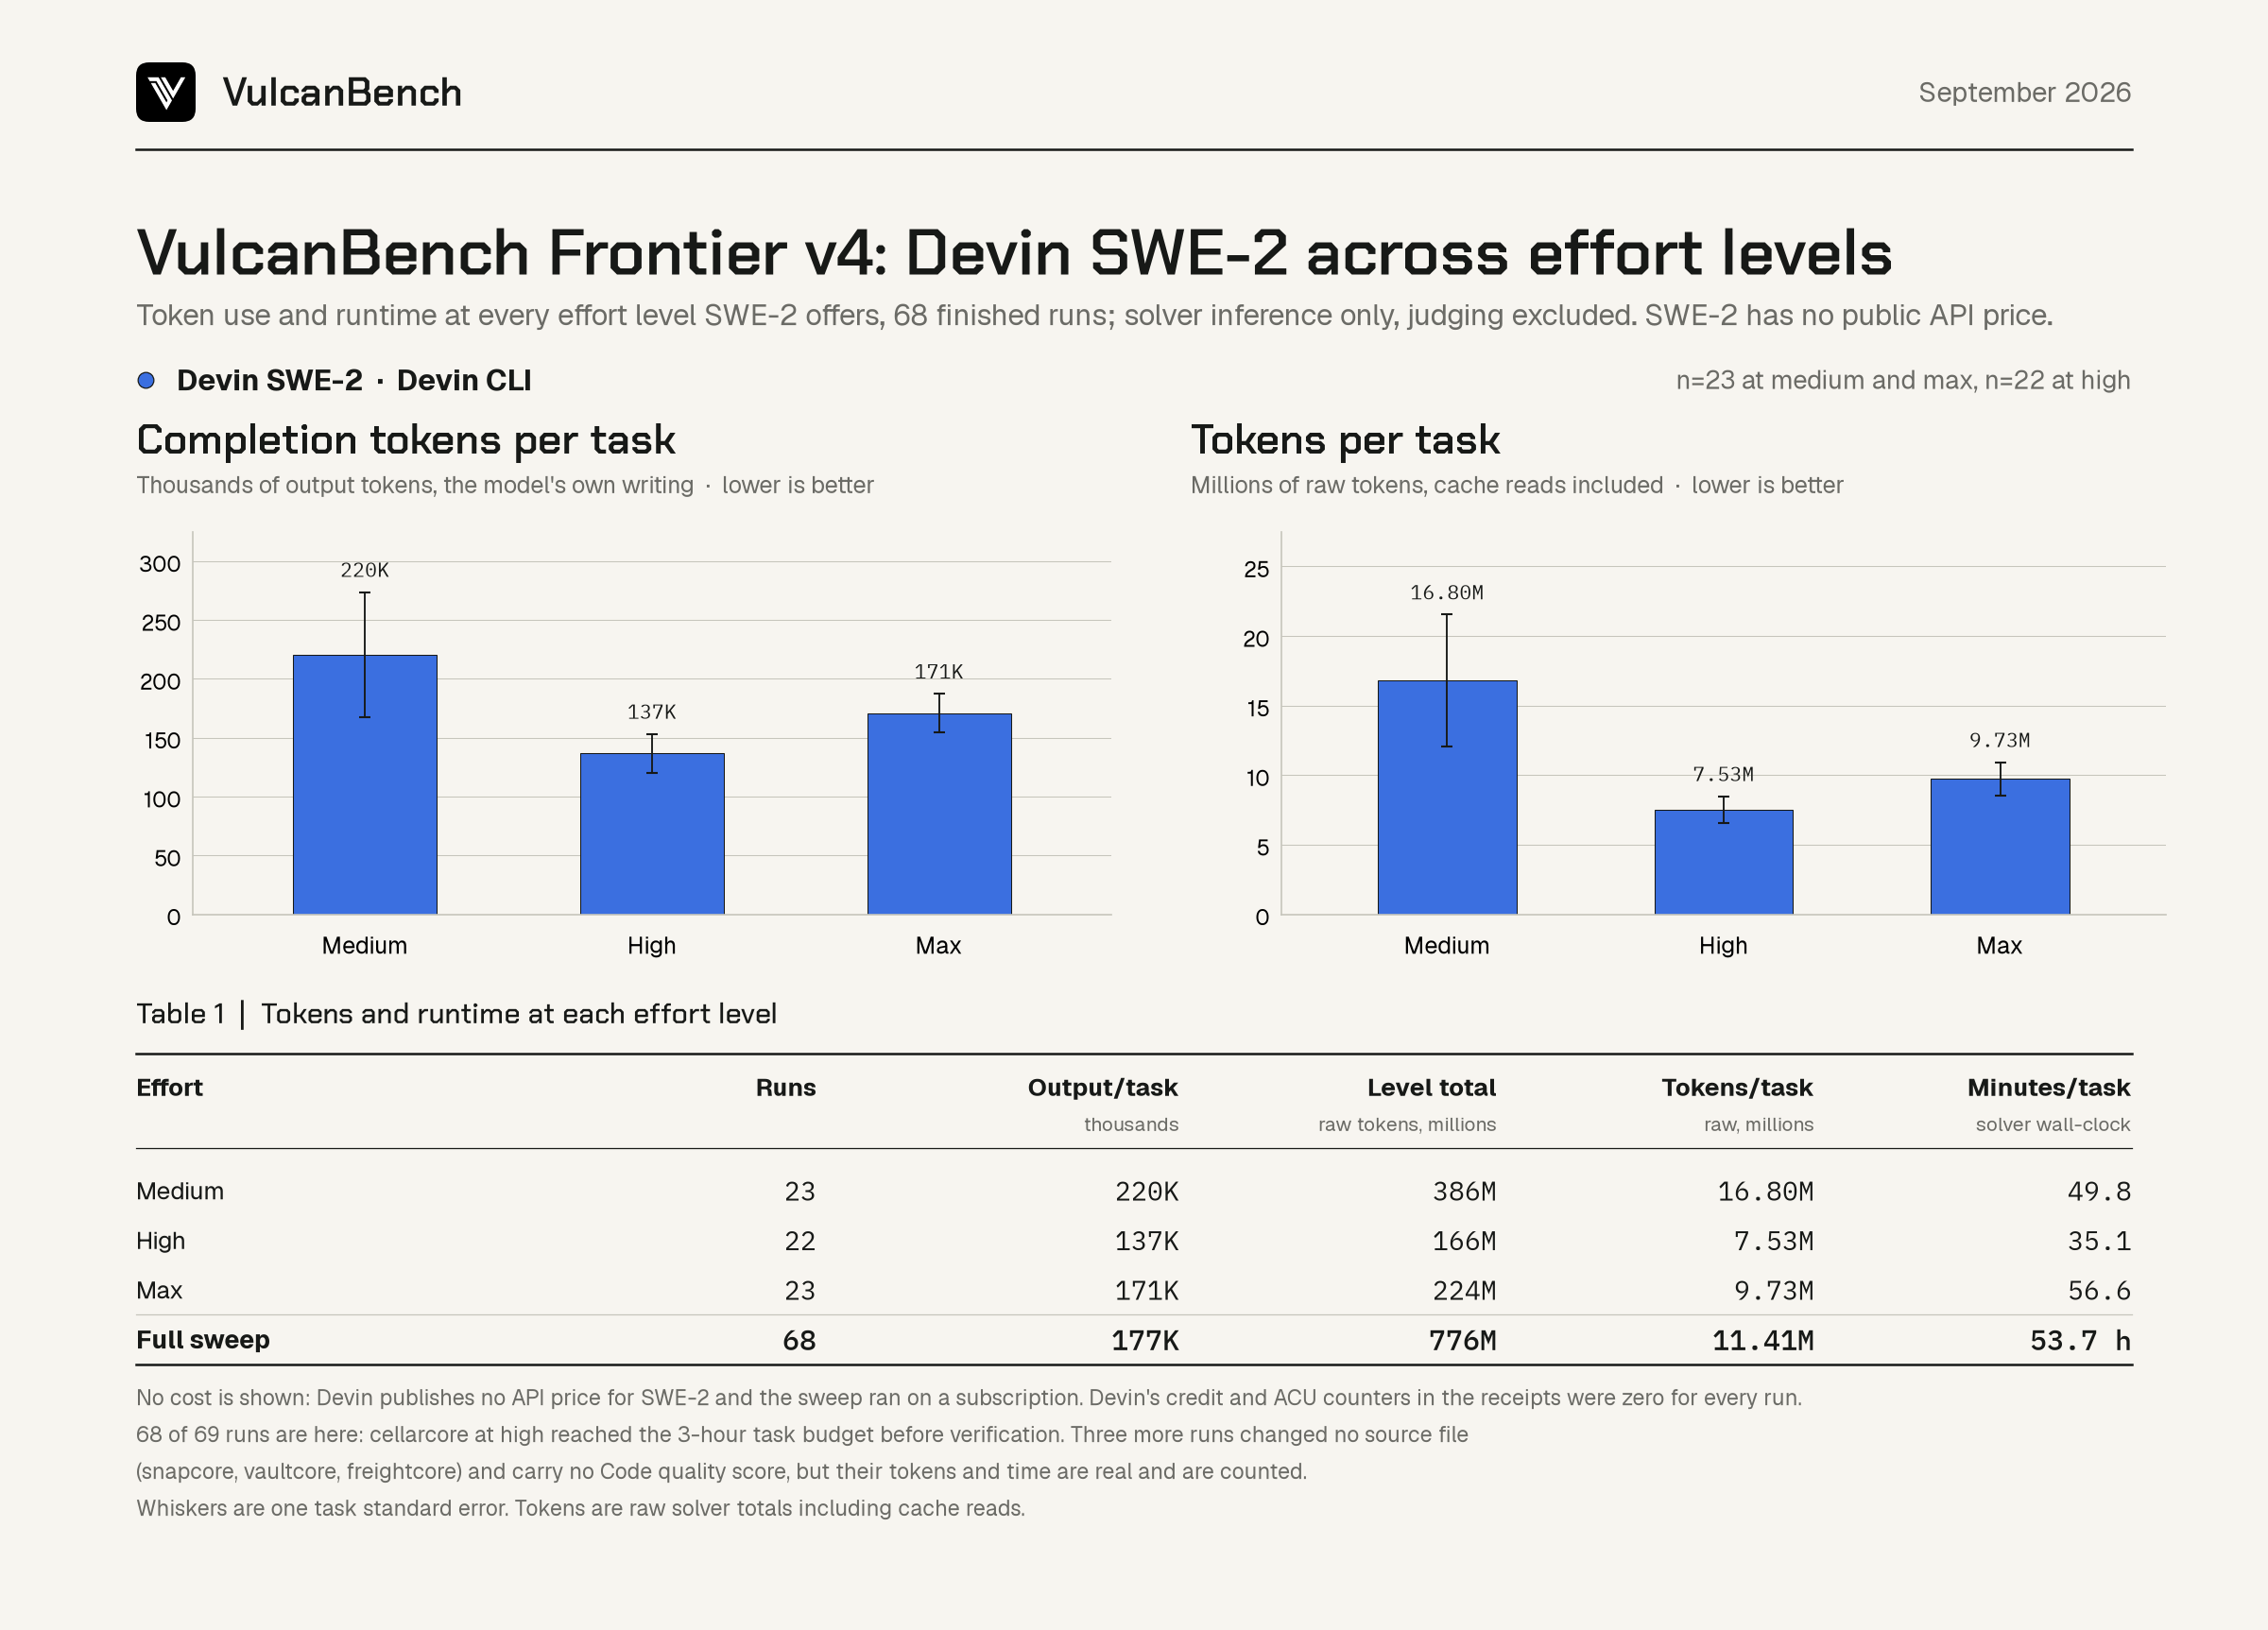
| Effort | Runs | Output/task | Level tokens | Tokens/task | Min/task | $/task |
|---|---|---|---|---|---|---|
| Medium | 23 | 220K | 386M | 16.80M | 49.8 | unavailable |
| High | 22 | 137K | 166M | 7.53M | 35.1 | unavailable |
| Max | 23 | 171K | 224M | 9.73M | 56.6 | unavailable |
| Full sweep | 68 | 177K | 776M | 11.41M | 53.7 h | unavailable |
Cost. Unavailable, and recorded as unavailable rather than as zero: estimated_usd is null on every run in the bundle, matching the null the harness population record carries. Devin's own credit and ACU counters read zero on all 68 finished runs and are recorded per run in runs.csv, but a zero counter on a subscription is a counter and not a price. If Cognition publishes a per-token rate for SWE-2, these runs can be repriced from their receipts and the column stops being unavailable.
Tokens are the Devin CLI's own per-request usage receipts, deduplicated by request id and summed as uncached input, cache reads and output. The level totals are 386M at medium, 166M at high and 224M at Max. The one run that did not finish has no receipt, so its tokens are absent and its 3.0 hours are outside the 53.7-hour total. Per-run records and the aggregates are in economics.json and runs.csv.
What Code quality measures
The judge receives a rubric frozen by hash before any review. It names the reader it scores for: an engineer who has never seen the code, reads it top to bottom without running it, and must make a correct change in one sitting. It tells the judge that its own ease at parsing dense code is not evidence of readability. Six dimensions are scored 0 to 4 in half steps against written anchors: naming, presentation and intent form the human readability sub-score; structure, changeability and verifiability form the maintainability sub-score. Every score must cite an exact excerpt from the code and a concrete consequence for that reader. The host computes the sub-scores; the judge does no arithmetic.
The 33 points have three designed layers. The reviewed panel carries 24 points. An intent-recovery probe carries 9: every task in this suite is a rewrite of a retired binary whose real behaviour departs from its written specification in documented ways, and the judge, given only the specification and the code, must list where the code departs from the specification. A separate call matches that list against a frozen answer key, over the departures the submission passed tests for. The third layer, measured maintenance, is designed for 12 points but is not yet built, so the pre-registered 24 plus 9 split is in force and is stated on the card.
| Component | Medium | High | Max |
|---|---|---|---|
| Code quality | 65.14 | 66.26 | 69.17 |
| Human readability | 54.3 | 57.9 | 61.4 |
| Maintainability | 67.4 | 67.5 | 70.8 |
| Intent recovery | 76.5 | 76.4 | 77.4 |
| Rated by Muse Spark 1.3 | 60.9 | 62.7 | 66.1 |
| Standard error of Code quality | 1.81 | 2.49 | 2.91 |
Code quality runs 65.14 to 69.17 across the three levels. The rise is carried by the reviewed layer, whose human readability sub-score climbs 7.0 points from medium to Max; intent recovery, the ground-truth layer, is flat at 76.4 to 77.4. With standard errors of 1.81 to 2.91 the medium to high step is inside the noise, and only Max is clearly above medium. The panel note under the effort table applies to every figure here. Per-run sub-scores are in runs.csv; the exact rubric, system text, probe and match instructions are in judge-protocols.json.
Judges and calibration
The scored panel is Muse Spark 1.3 (Meta) through the Muse CLI on its Standard tier, which does not train on prompts or completions. Meta has no model on this board, so the judge does not grade a relative. Every session is fresh, tools are disabled, the workspace is empty, model identity is checked per call from the CLI's own records, and solver labels are withheld. Protocol v3.11 changes nothing in the rubric, controls, quirk keys, gates, repeats, seed or judge settings; it applies the protocol to the judged population of this sweep.
Before scoring a single submission, a judge reviews ten held-out programs that implement the same ledger specification: clear, compressed, compressed then auto-formatted, verbose with duplicated policy, needlessly abstracted, misleadingly commented, narrated with a comment on every line, a documented legacy quirk, an embedded instruction to give full marks, and hidden module state. Each program is reviewed five times in a seeded order. Twenty gates fixed in advance check that the judge sees the construct; a judge may miss at most one gate by at most half a point, and gate 16 is boolean, so the allowance cannot cover it.
| Judge | Protocol | Calls | Result | Allowance used | Failing gates |
|---|---|---|---|---|---|
| Muse Spark 1.3, scored | code-quality-maintenance-v3.9 | 80 | passed | yes | g11_repeatability |
| Grok 4.6, not scored | code-quality-maintenance-v3.9 | 80 | failed | no | g16_probe_recovers_documented_intent |
| GPT-5.6 Sol, not scored | code-quality-maintenance-v3.10 | 80 | failed | no | g16_probe_recovers_documented_intent |
Muse's verdict comes from the v3.9 freeze rather than a fresh exam: the exam is per judge and control set and neither changed between v3.9 and v3.11, so on the v3.6.1 precedent the runner reuses the verdict and refuses to freeze unless it passed. Muse passed 19 of the 20 gates outright and used the pre-registered one-gate allowance on the repeatability gate, within the allowance as written. It separates the clear program from the compressed one by more than two points on naming, credits formatting mainly on presentation, penalises misleading comments on intent and penalises hidden state on verifiability. Grok 4.6 and GPT-5.6 Sol each passed every other gate, repeatability included, and failed only gate 16, the one call that rewards saying nothing. Every gate value and control mean for all three judges is in calibration.json.
Under v3.11 Muse Spark 1.3 made 204 counted calls: 65 primary reviews, 3 repeats, 6 pairwise checks, 65 intent probes and 65 answer-key matches. No call needed a second attempt, no operator rule was invoked and no reviewer fallback occurred. The v3.9 and v3.10 passes against the earlier freezes, including the two failed exams, stay archived in the harness run directories.
Evidence and reproduction
Public files contain all 68 finished run measurements, the judge's six-dimension sub-scores and intent-recovery score per published run, raw tokens and Devin's own credit and ACU counters per run (and a null cost, since none is available), three aggregates, every calibration gate value for all three judges, the exact judge protocol text and the population record with its four exclusions. Each run's Code quality is (0.24 × reviewed score + 0.09 × intent recovery) / 0.33, both terms from the scored panel, or the reviewed score alone where intent recovery has no denominator. The combined score is 100 × (0.50F + 0.085Q + 0.085S + 0.33C / 100). The reproduction guide gives the public arithmetic checks and links the protocol documents, controls, runner and operator wrapper.
No human rated anything; the scores are model judgment for a human reader, not human validation. Runs were not repeated, and effort labels are Devin's own. The high cell's Code quality and combined score are means over 20 of 23 runs and the Max cell's over 22 of 23, for the reasons given above. Hash checks bind the export to frozen files; they do not prove that the judge was unbiased or that no training overlap exists.
Withheld: raw prompts and responses, submitted patches and reconstructed sources, the quirk answer keys (they describe hidden-test behaviour), and reviewer session identifiers and usage receipts. Summed solver time is 53.66 hours over the finished runs; judging is excluded.