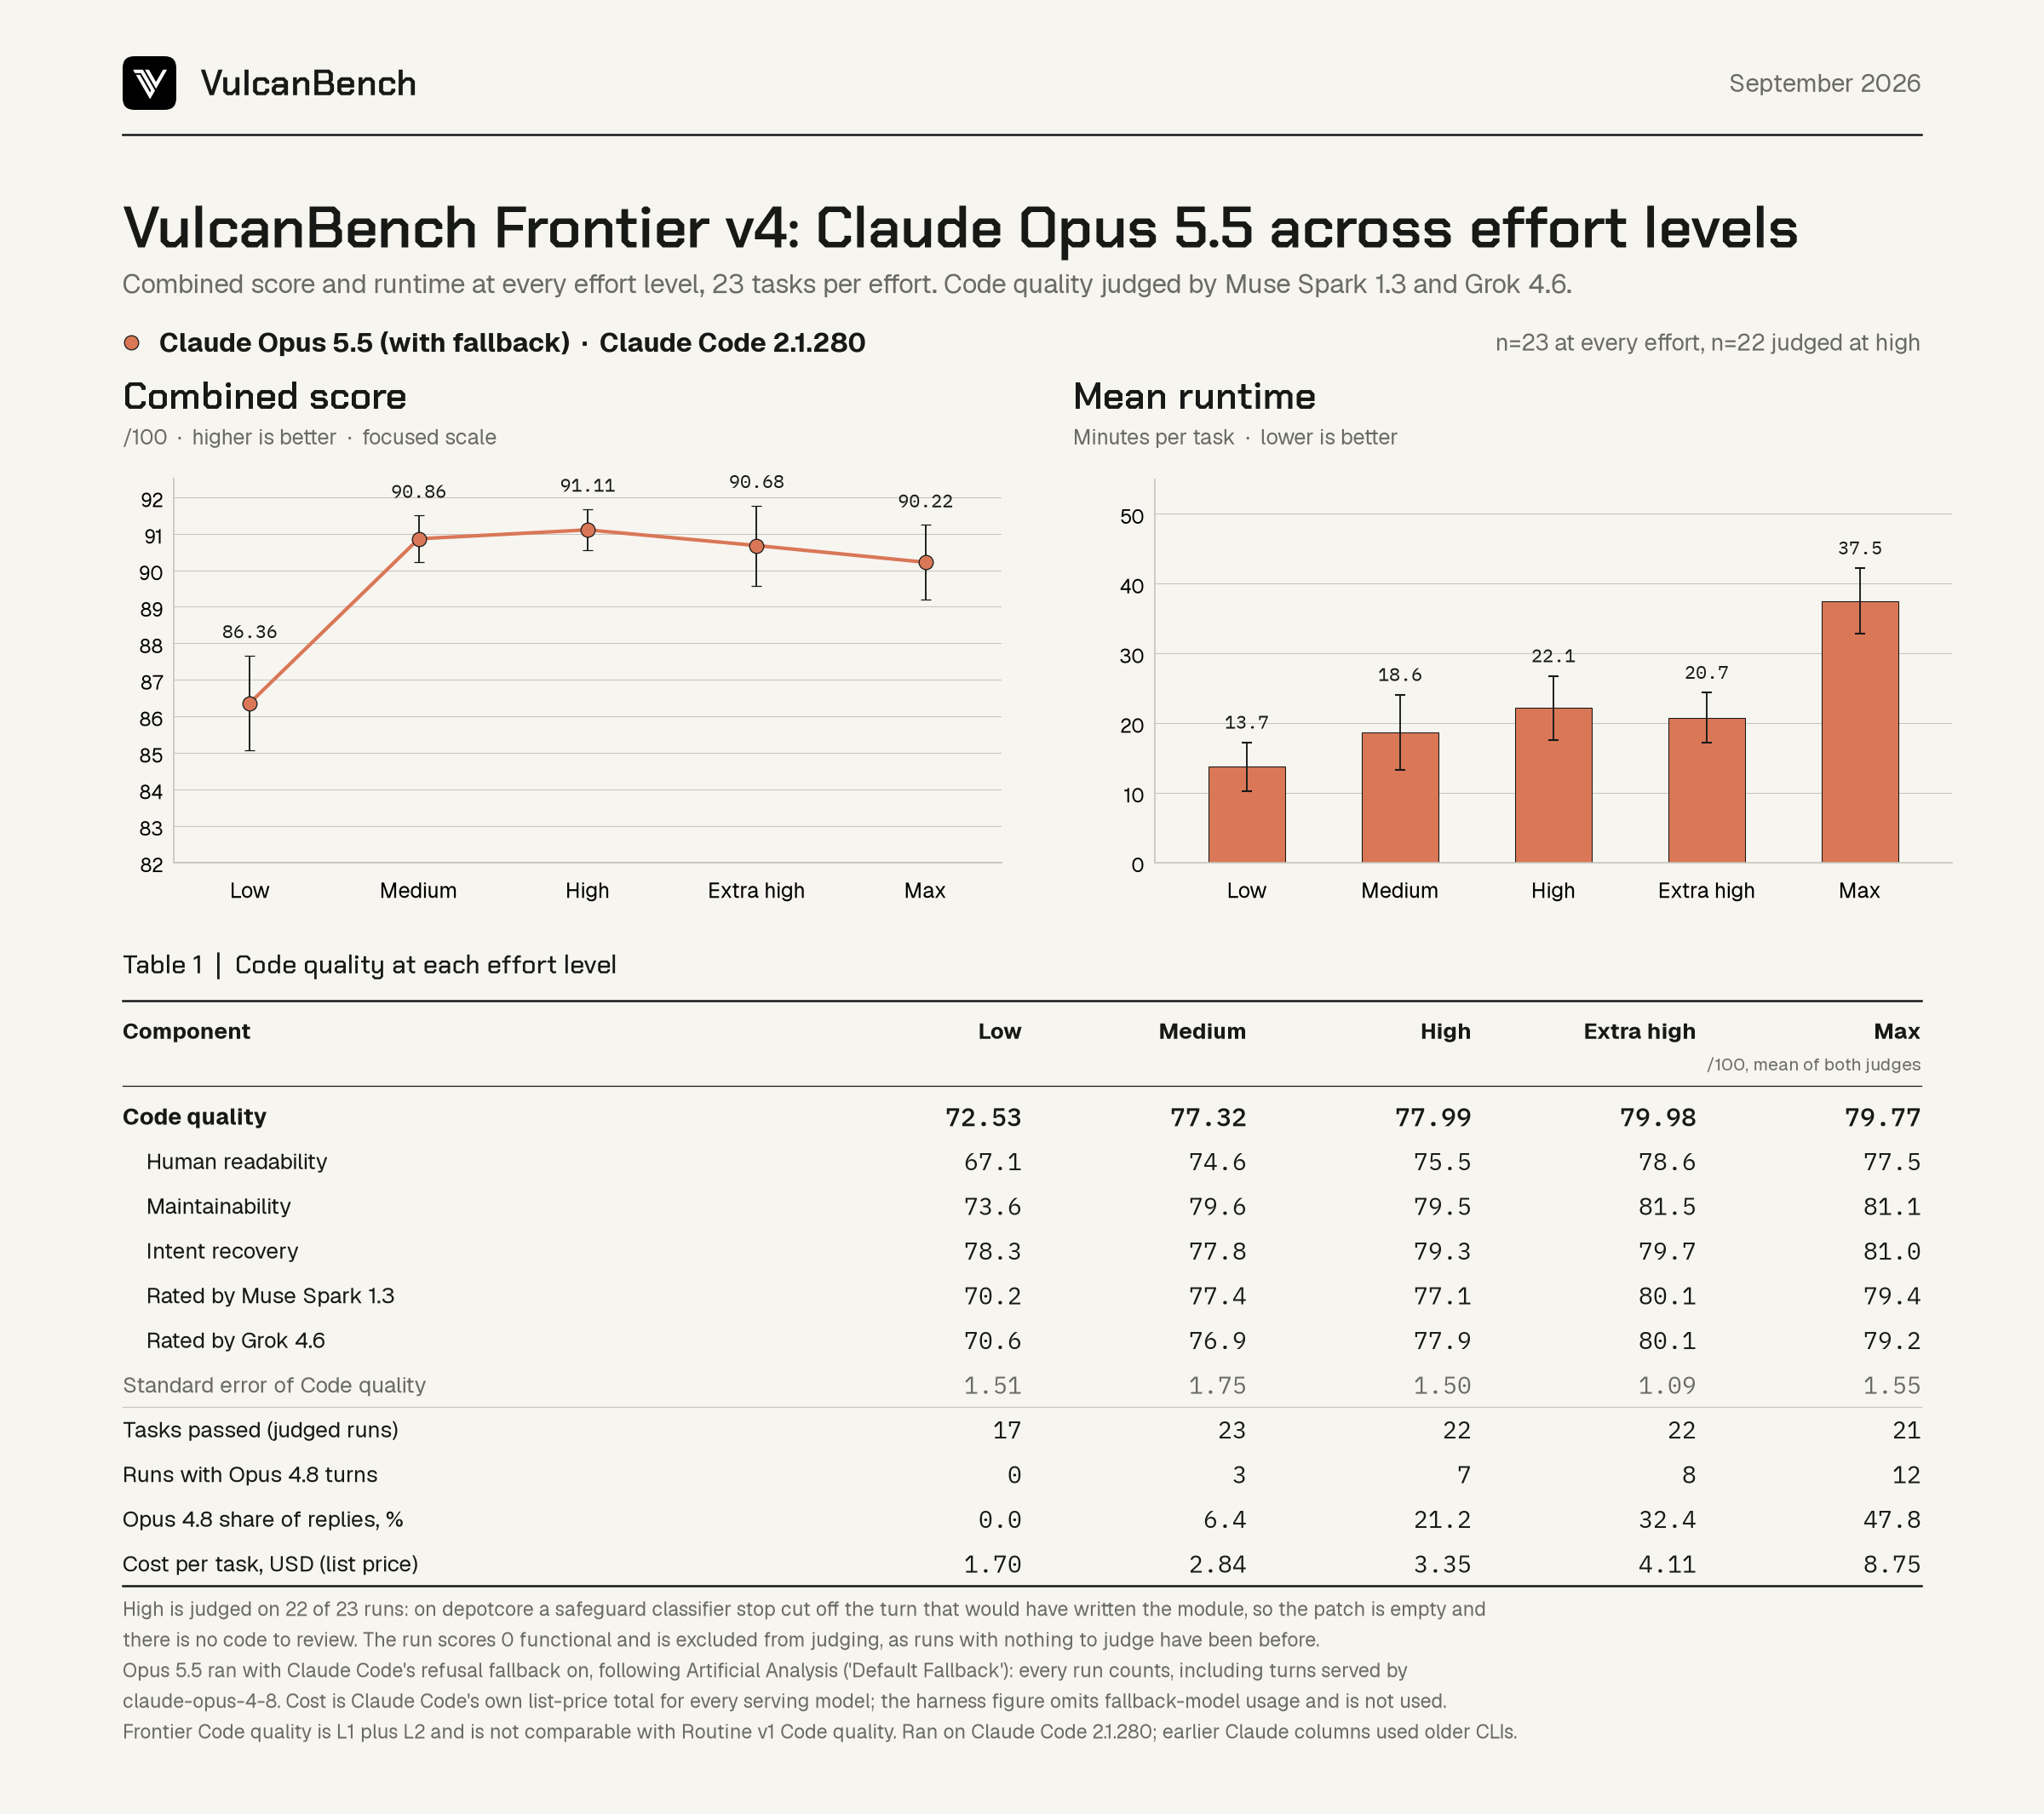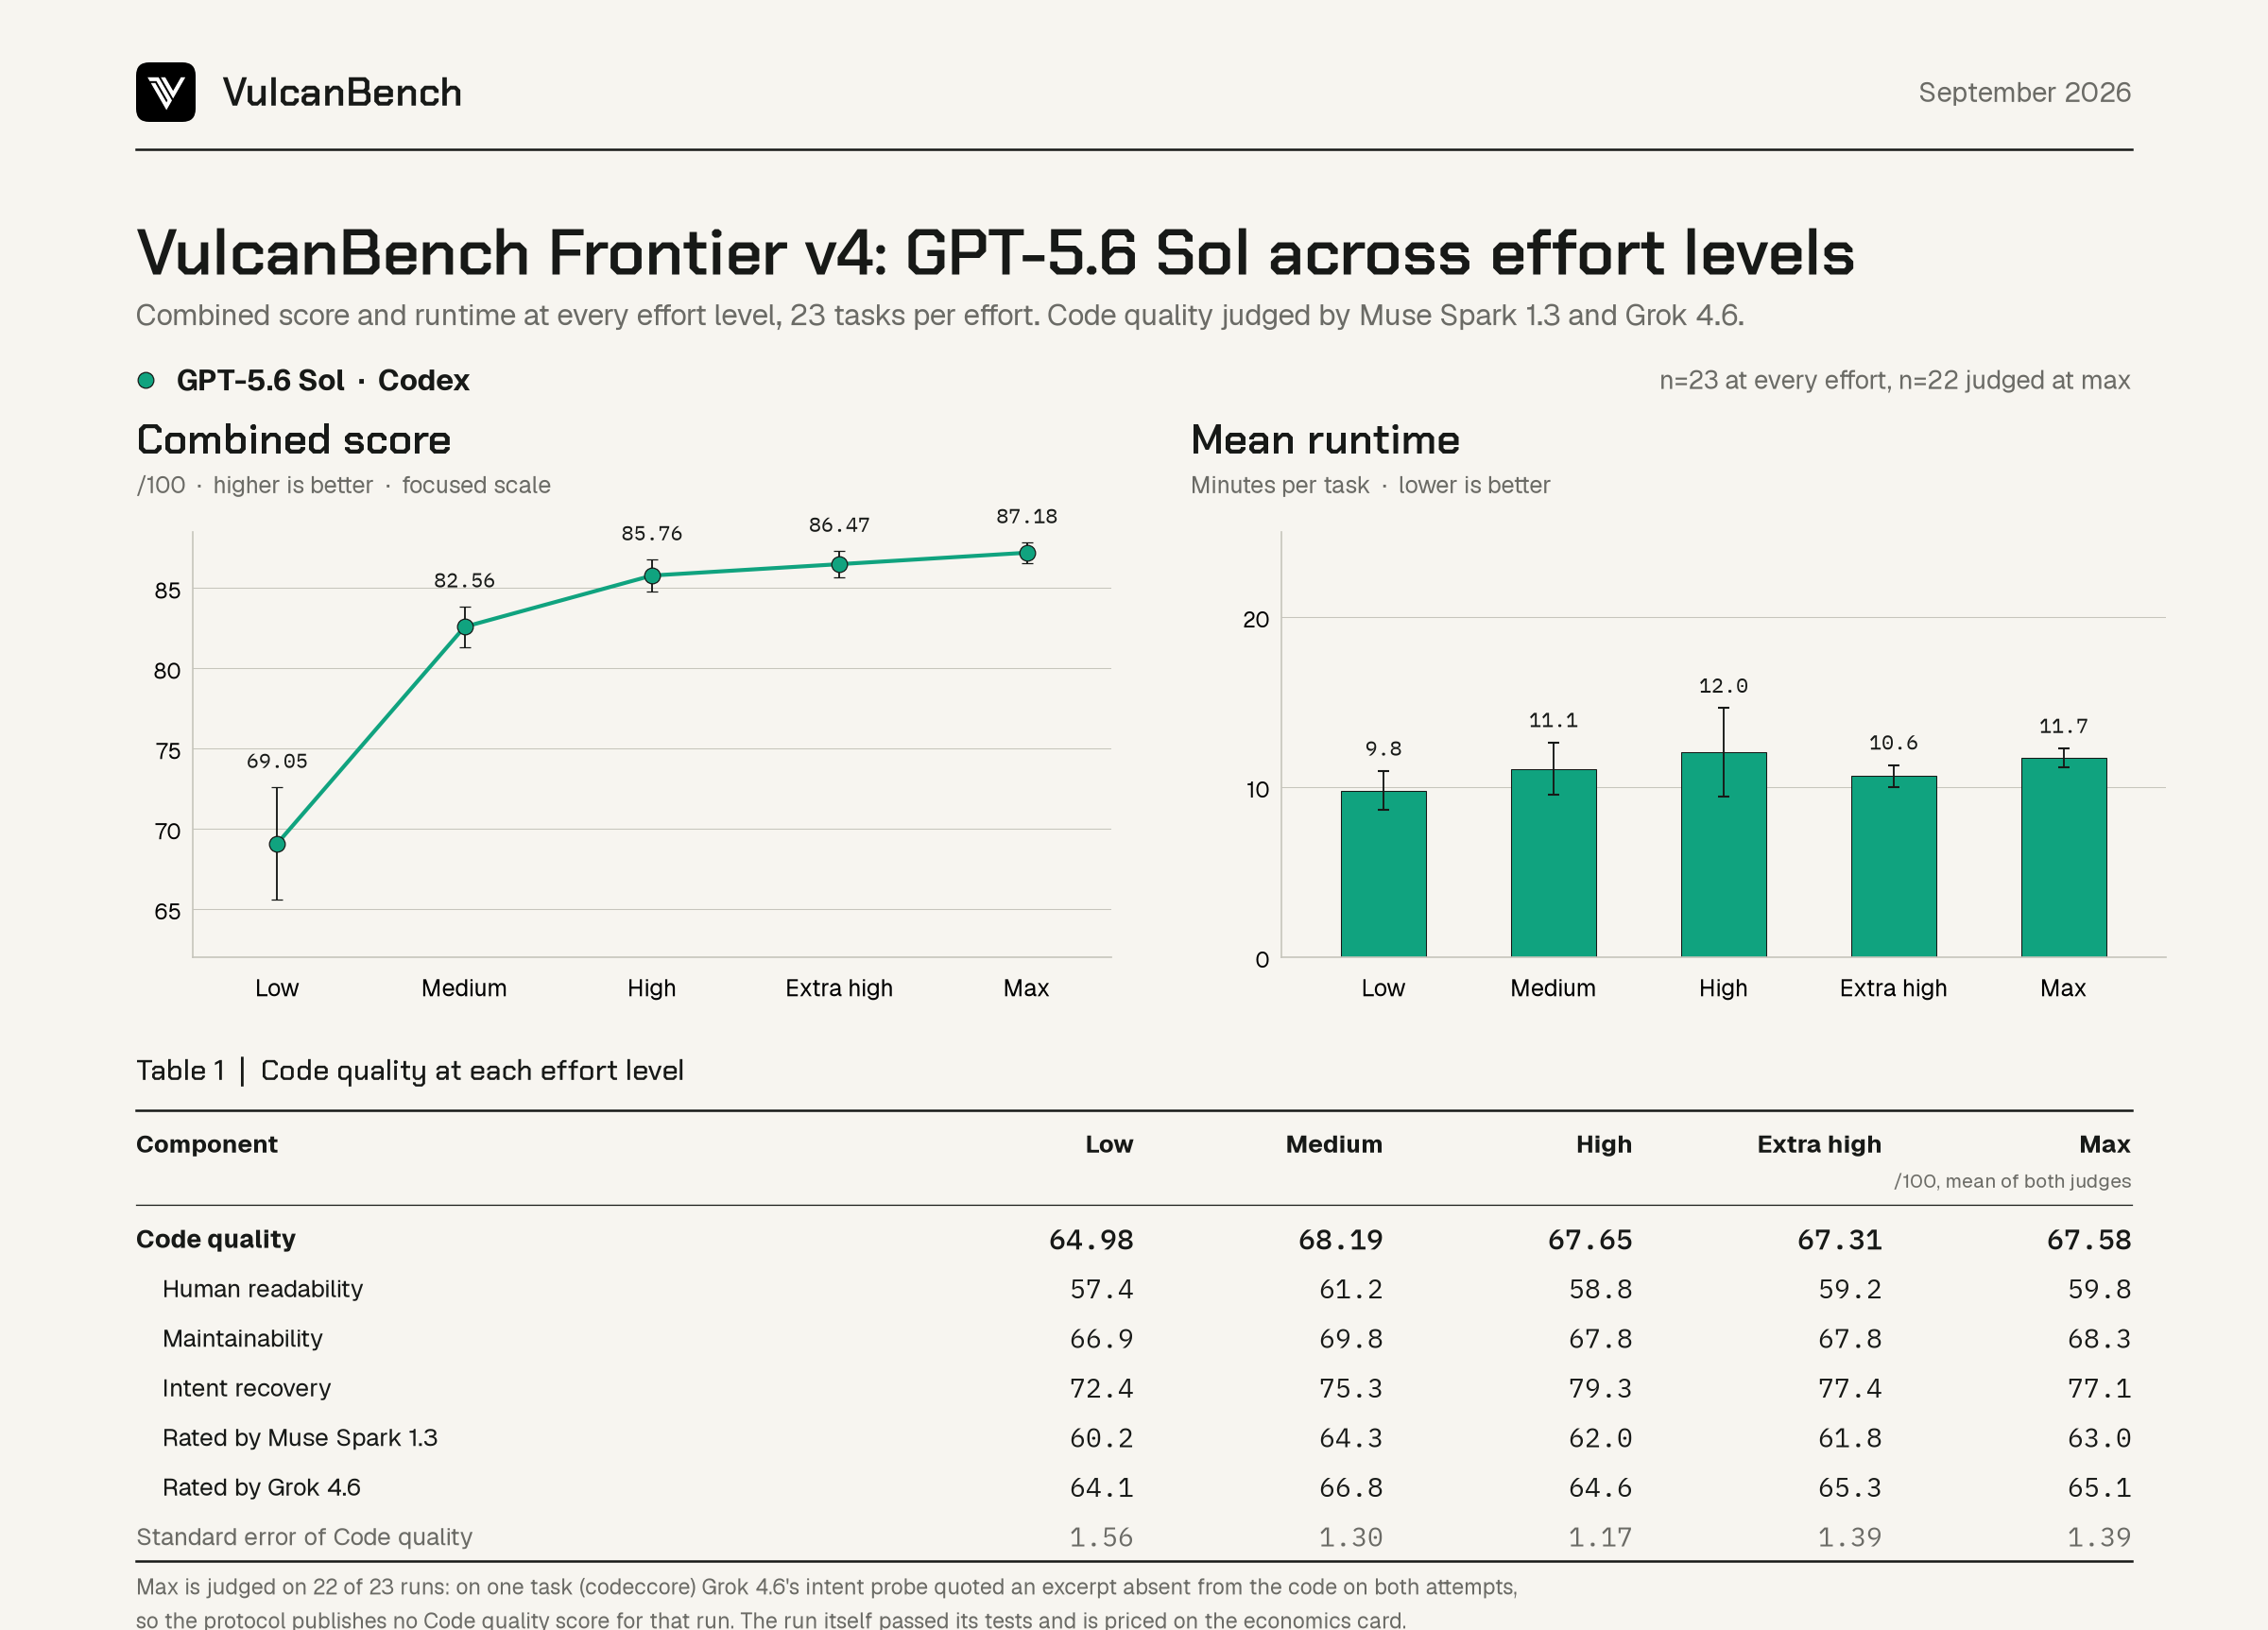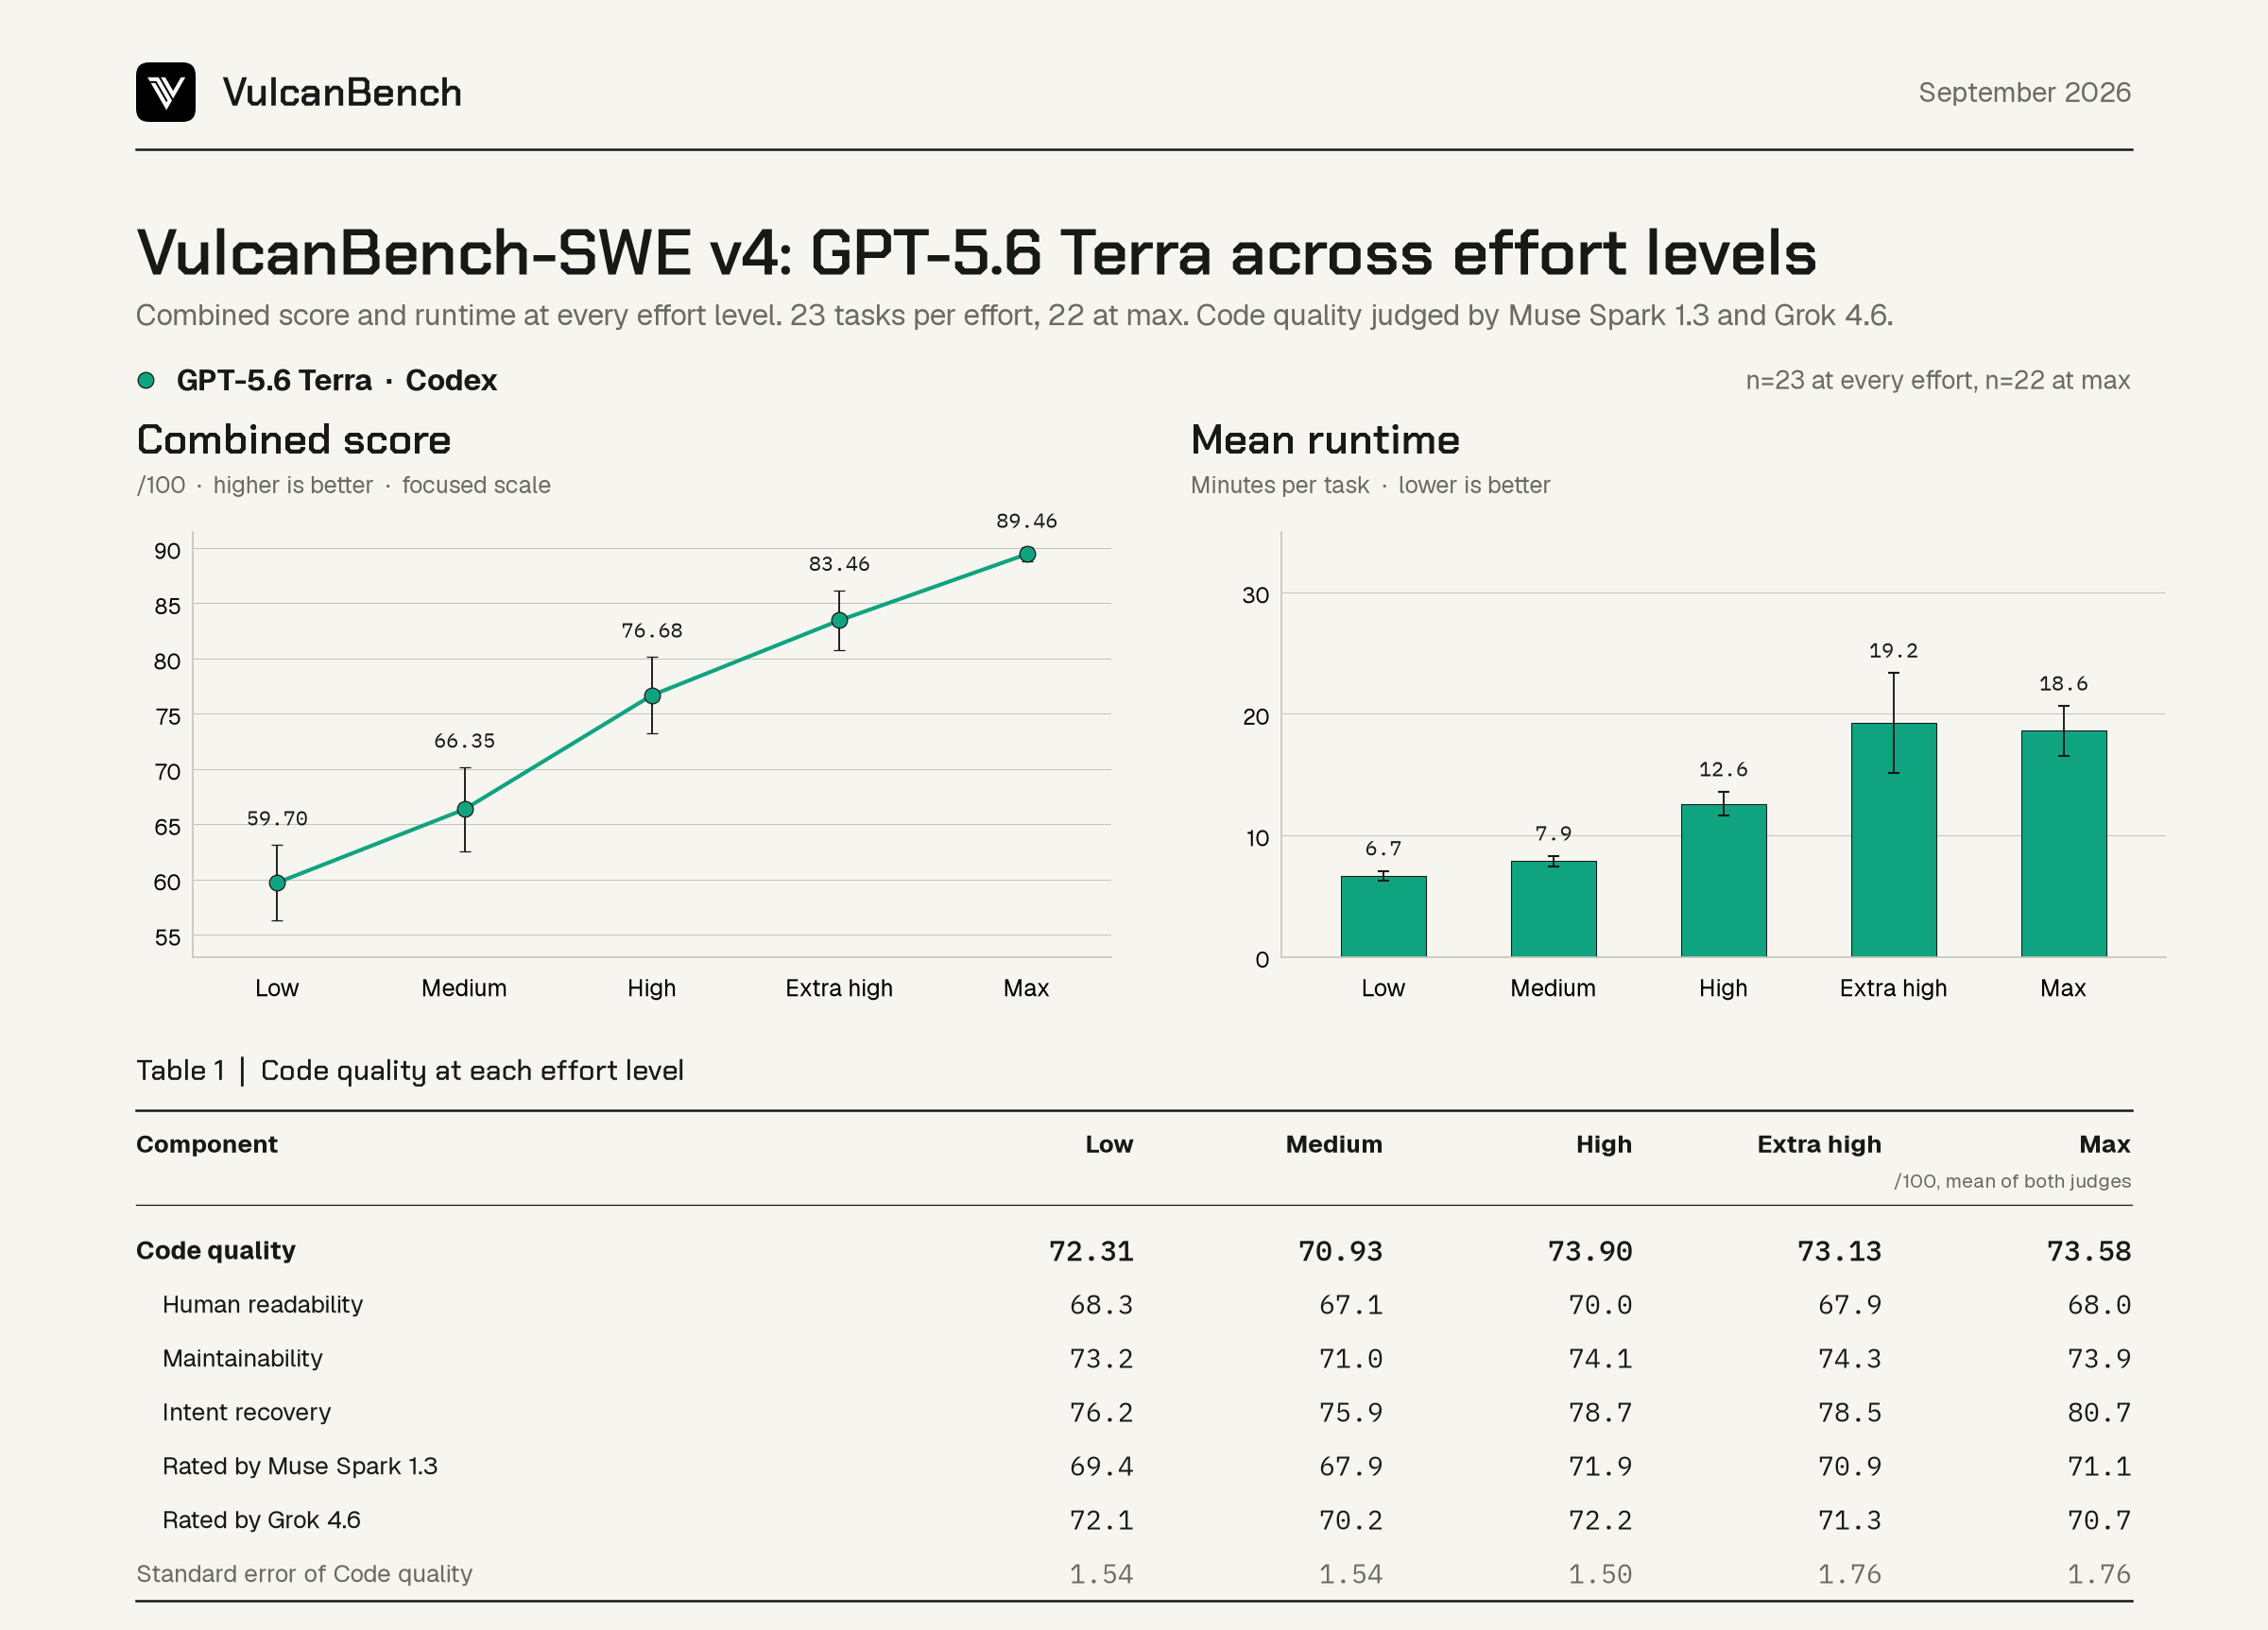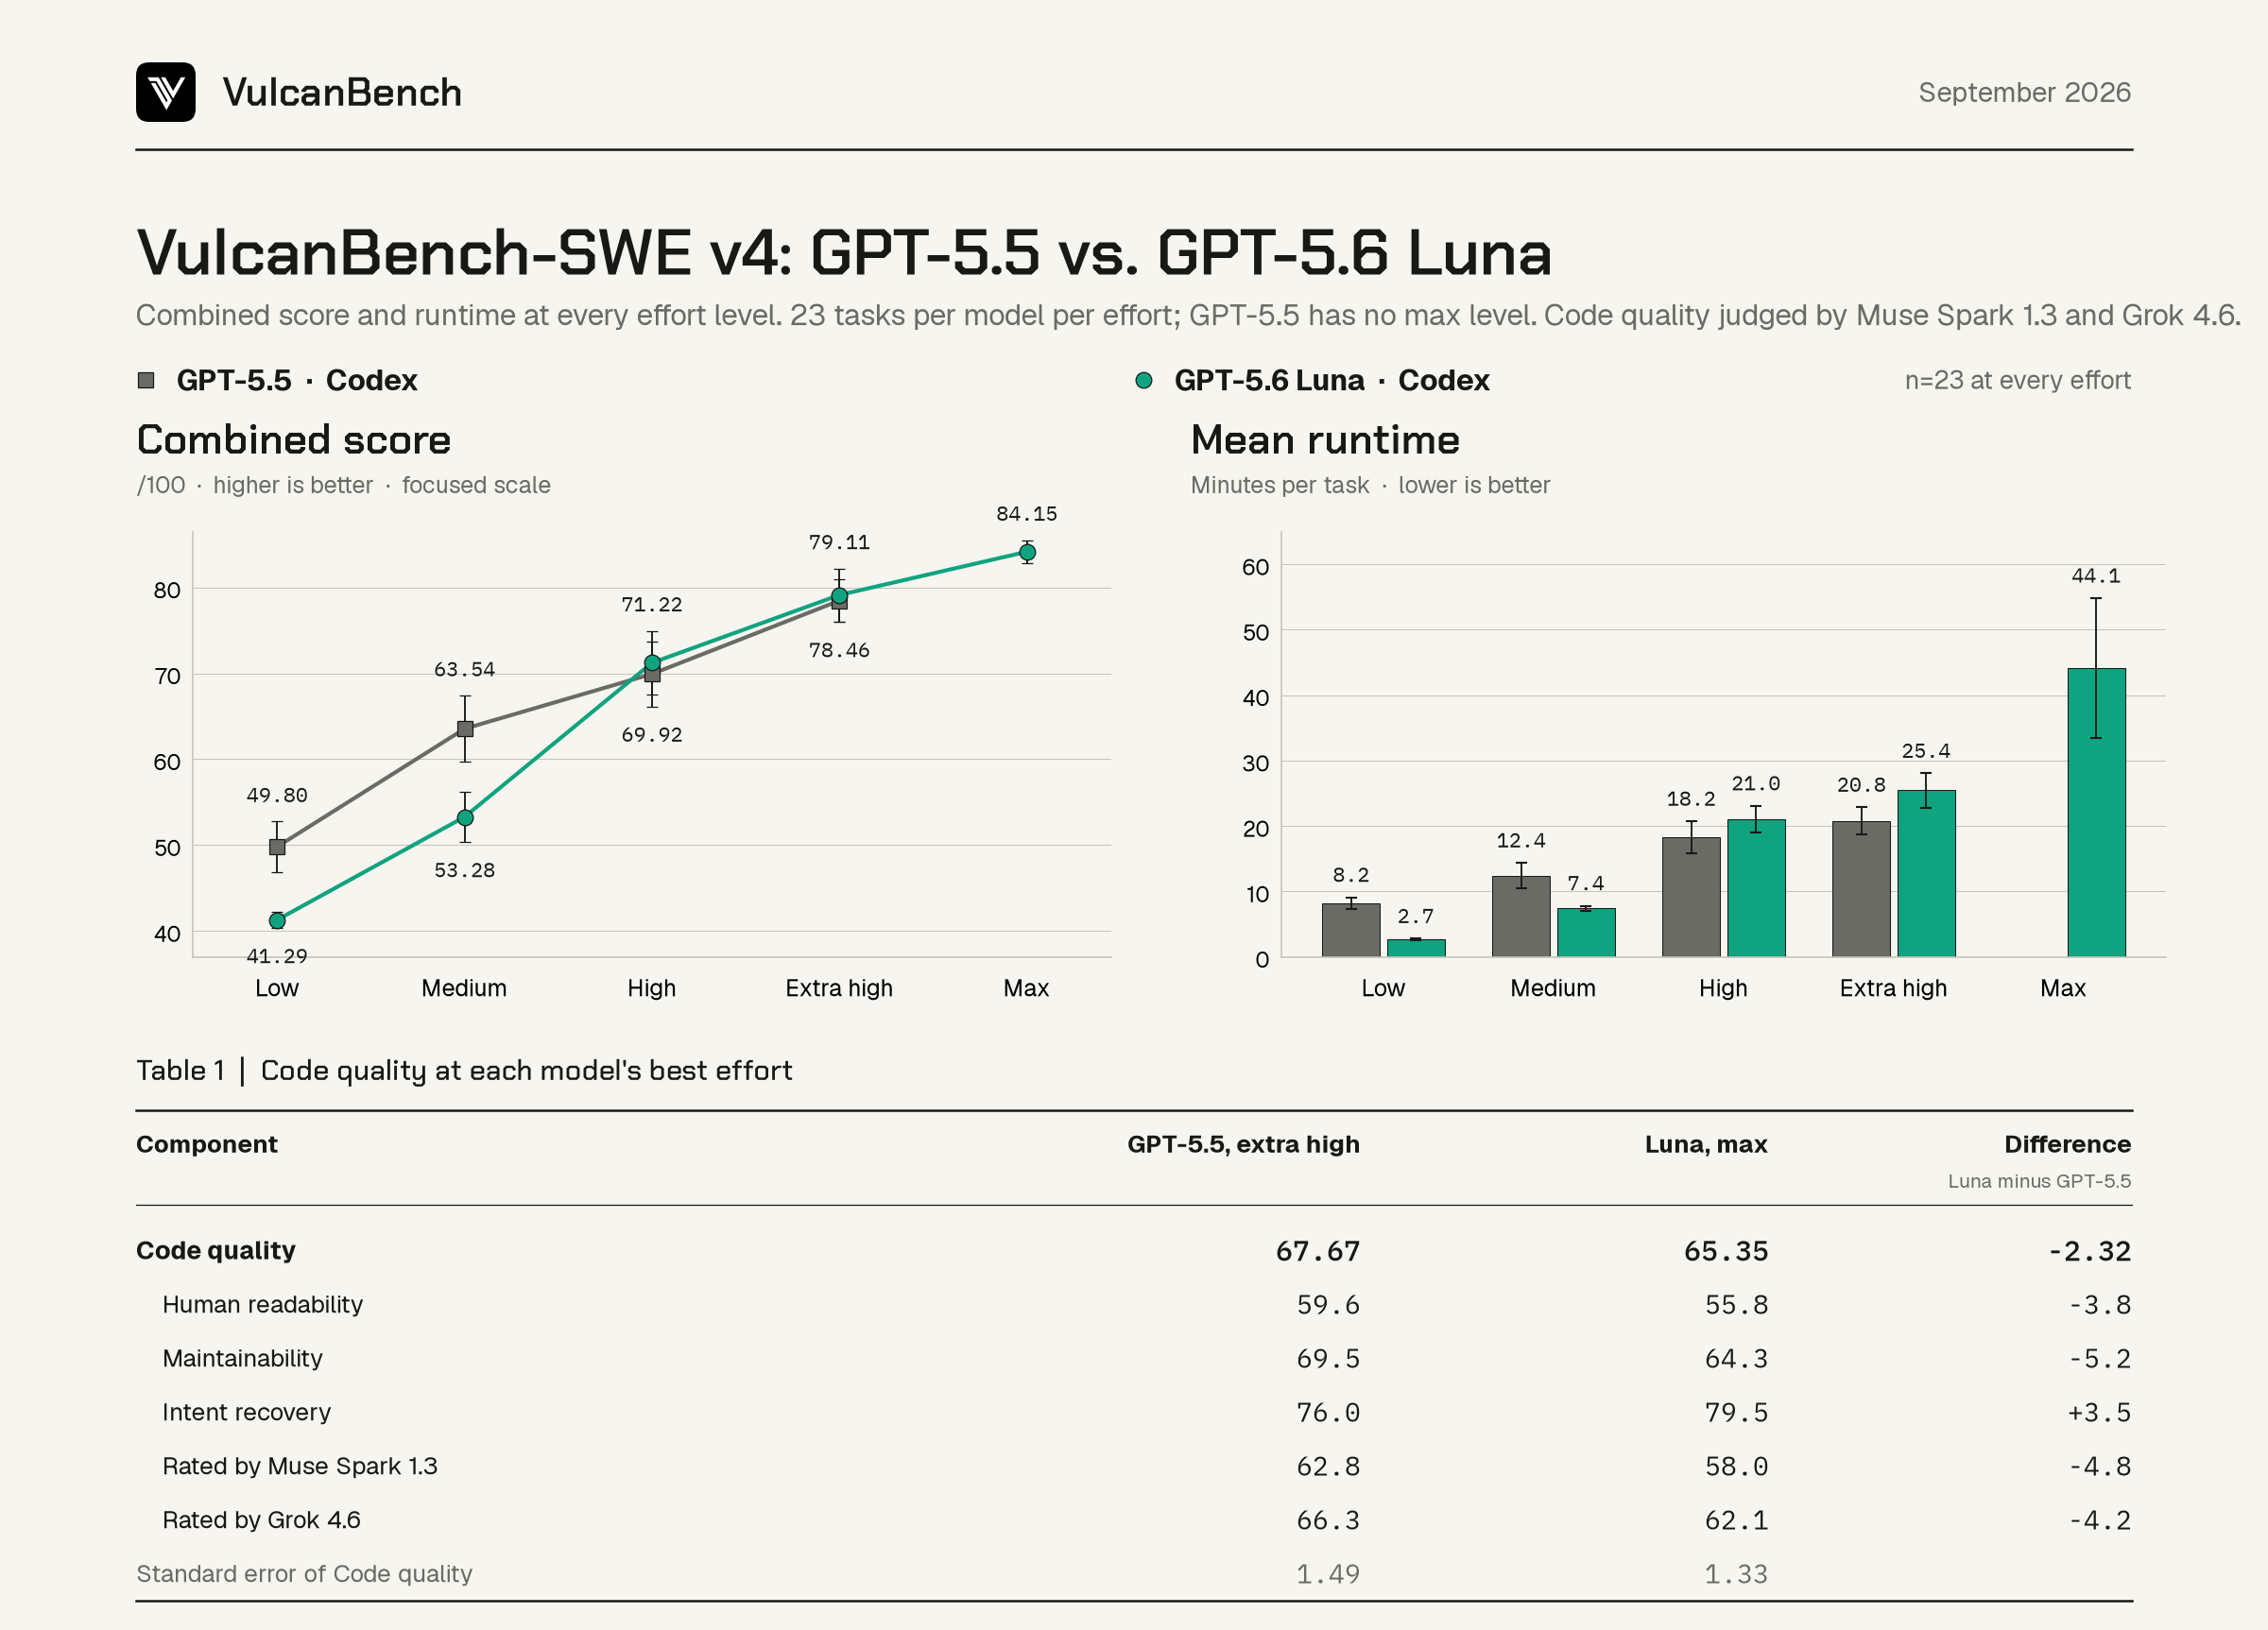
The published record

Benchmarks

Compare results within the same suite and scoring protocol. Scores from different suites are not directly comparable.

Current suite

VulcanBench Frontier v4

Suite methodology →

23 hard tasks that rebuild a retired program from its real behaviour, formerly published as VulcanBench-SWE v4. Combined score: 50% functional correctness, 8.5% lint and complexity, 8.5% security and 33% Code quality from a two-model panel that never includes the graded model’s own lab.

November 19, 2026 · 115 runs · Code quality protocol v3.31

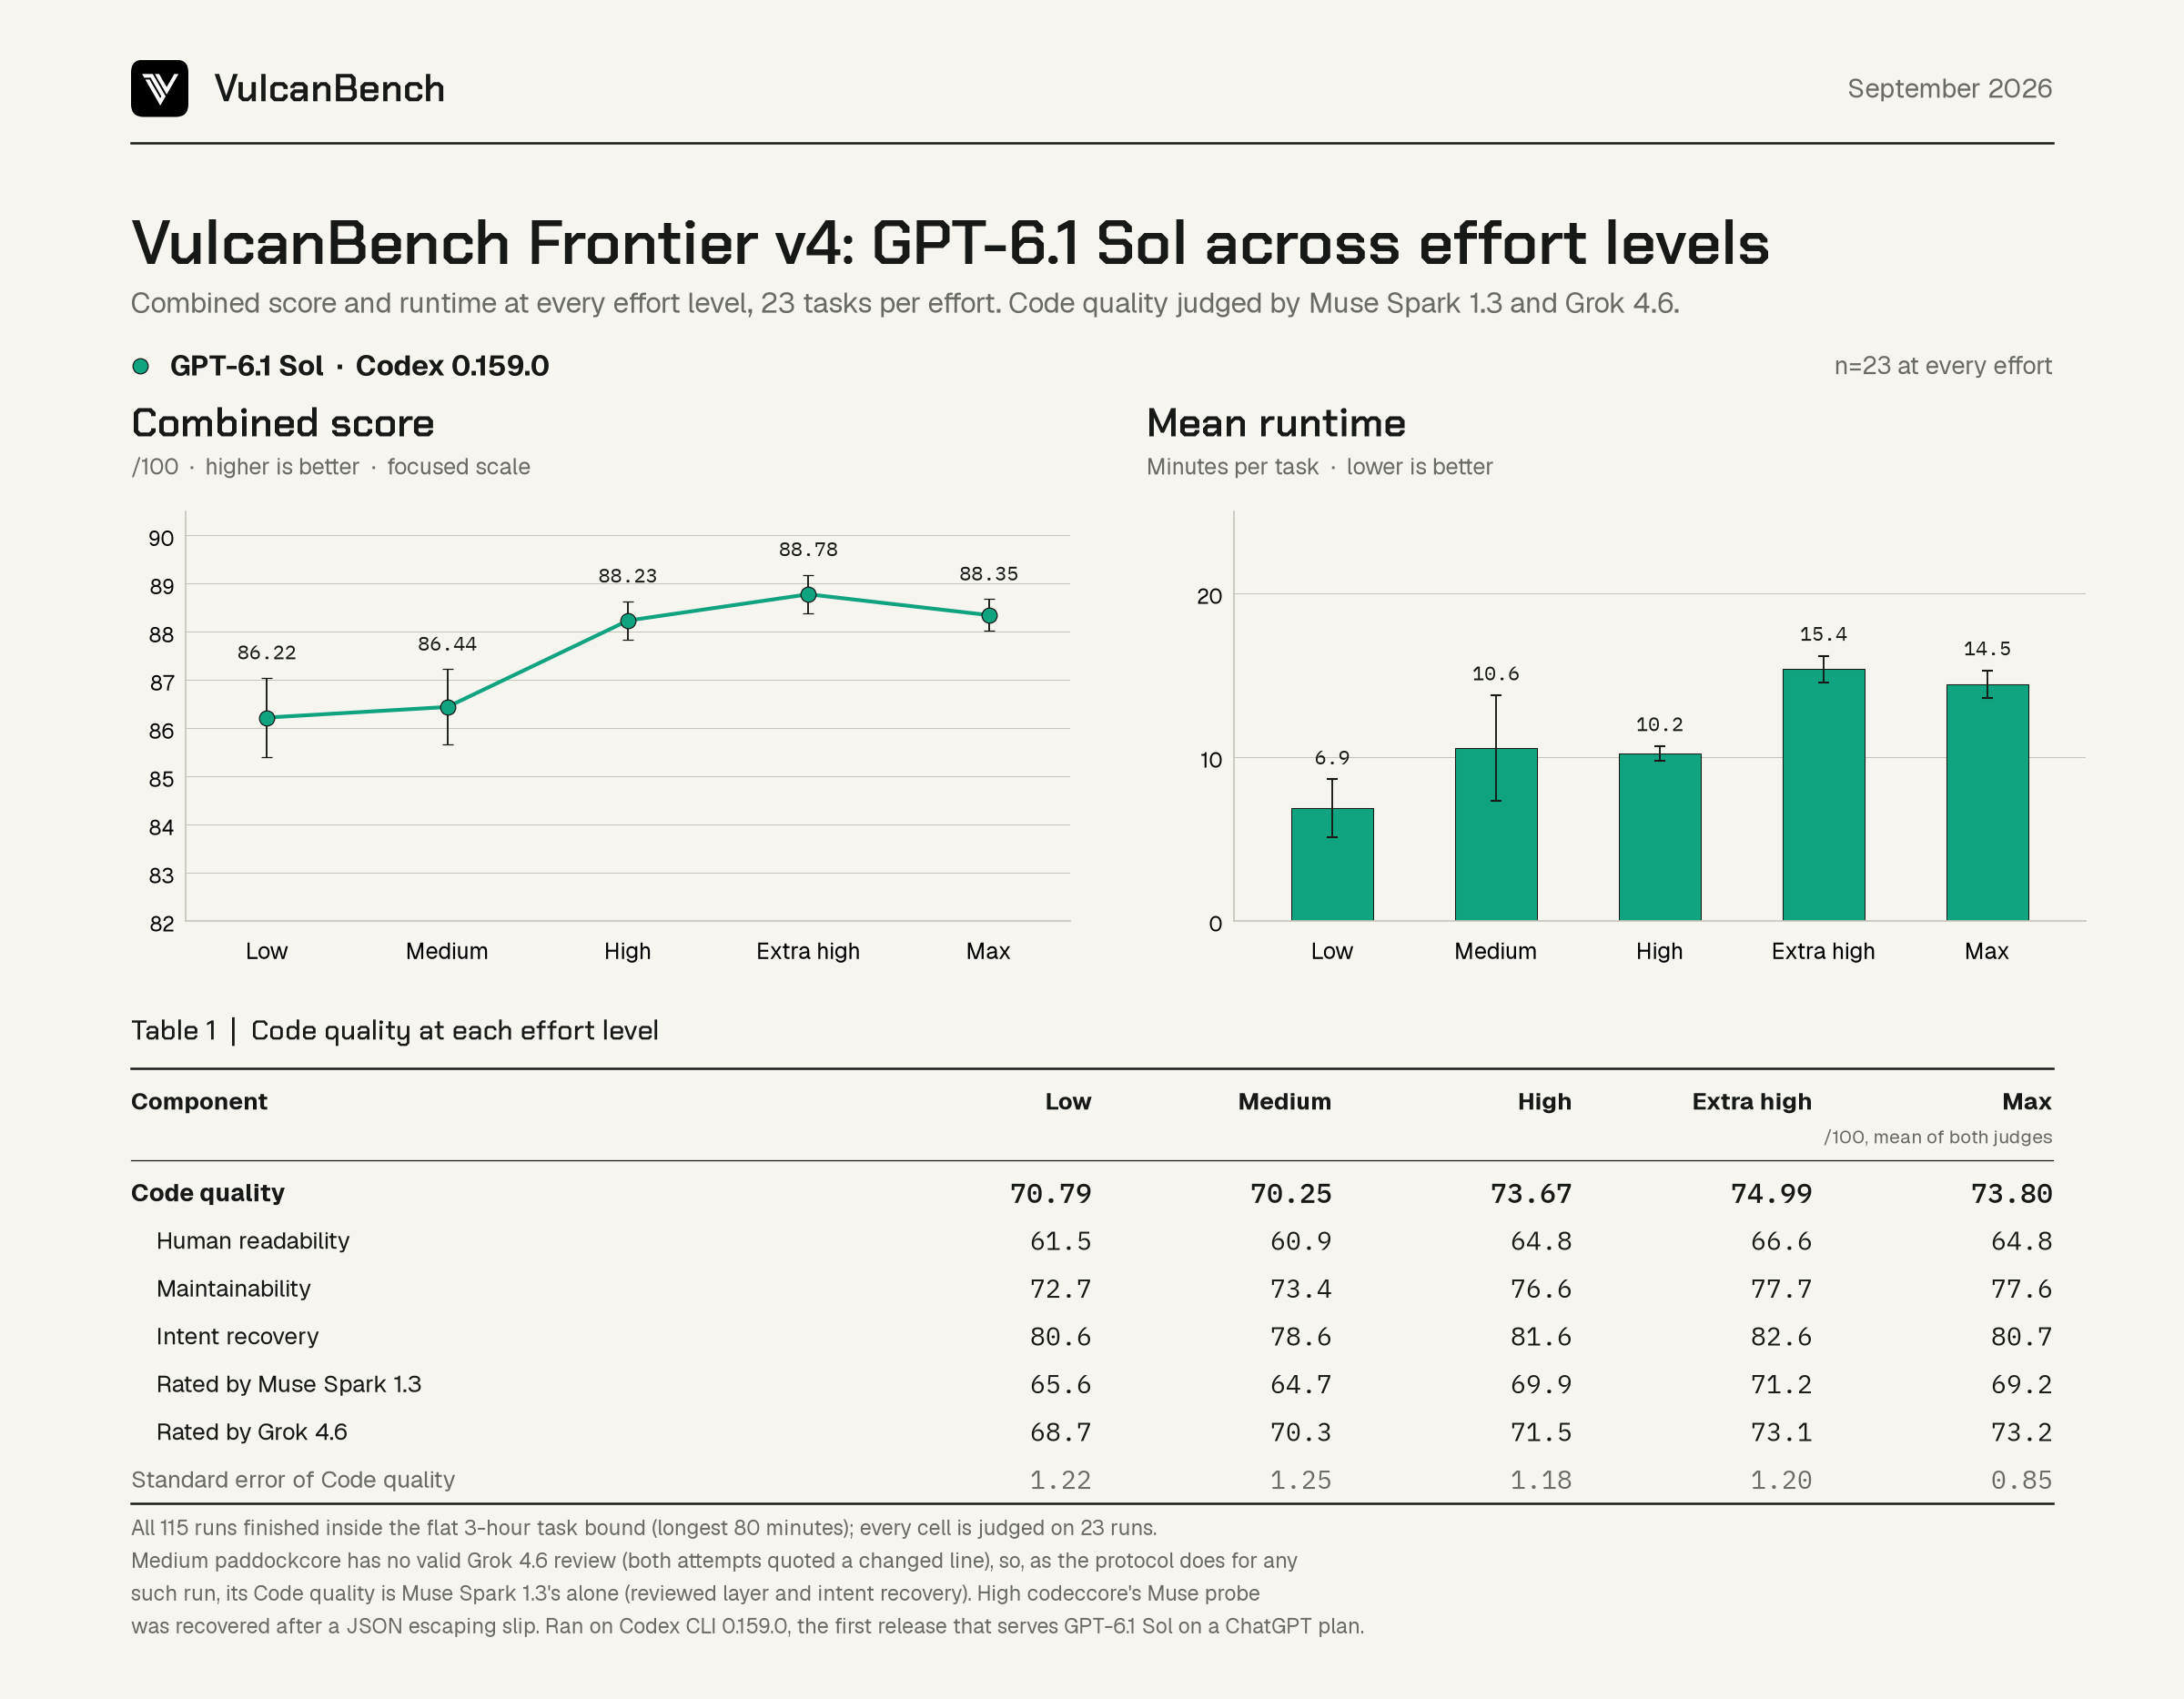
GPT-6.2 Sol across every effort level

115 runs of GPT-6.2 Sol in Codex on a ChatGPT subscription, on its release day, 23 tasks at each of five effort levels, with Code quality at 33% of the combined score, judged by Muse Spark 1.3 and Grok 4.6. It passed every hidden test in all 115 runs.

Combined score 88.44 at Low, 88.94 at Medium, 88.86 at High, 89.01 at Extra-high and 88.74 at Max, nearly flat, so Low is the level to run; $0.23 to $0.55 and 2.8 to 11.3 minutes a task. It gains on GPT-6.1 Sol at Low and Medium and stays 3 to 5 points behind Claude Fable 5.2 at a fraction of its cost.
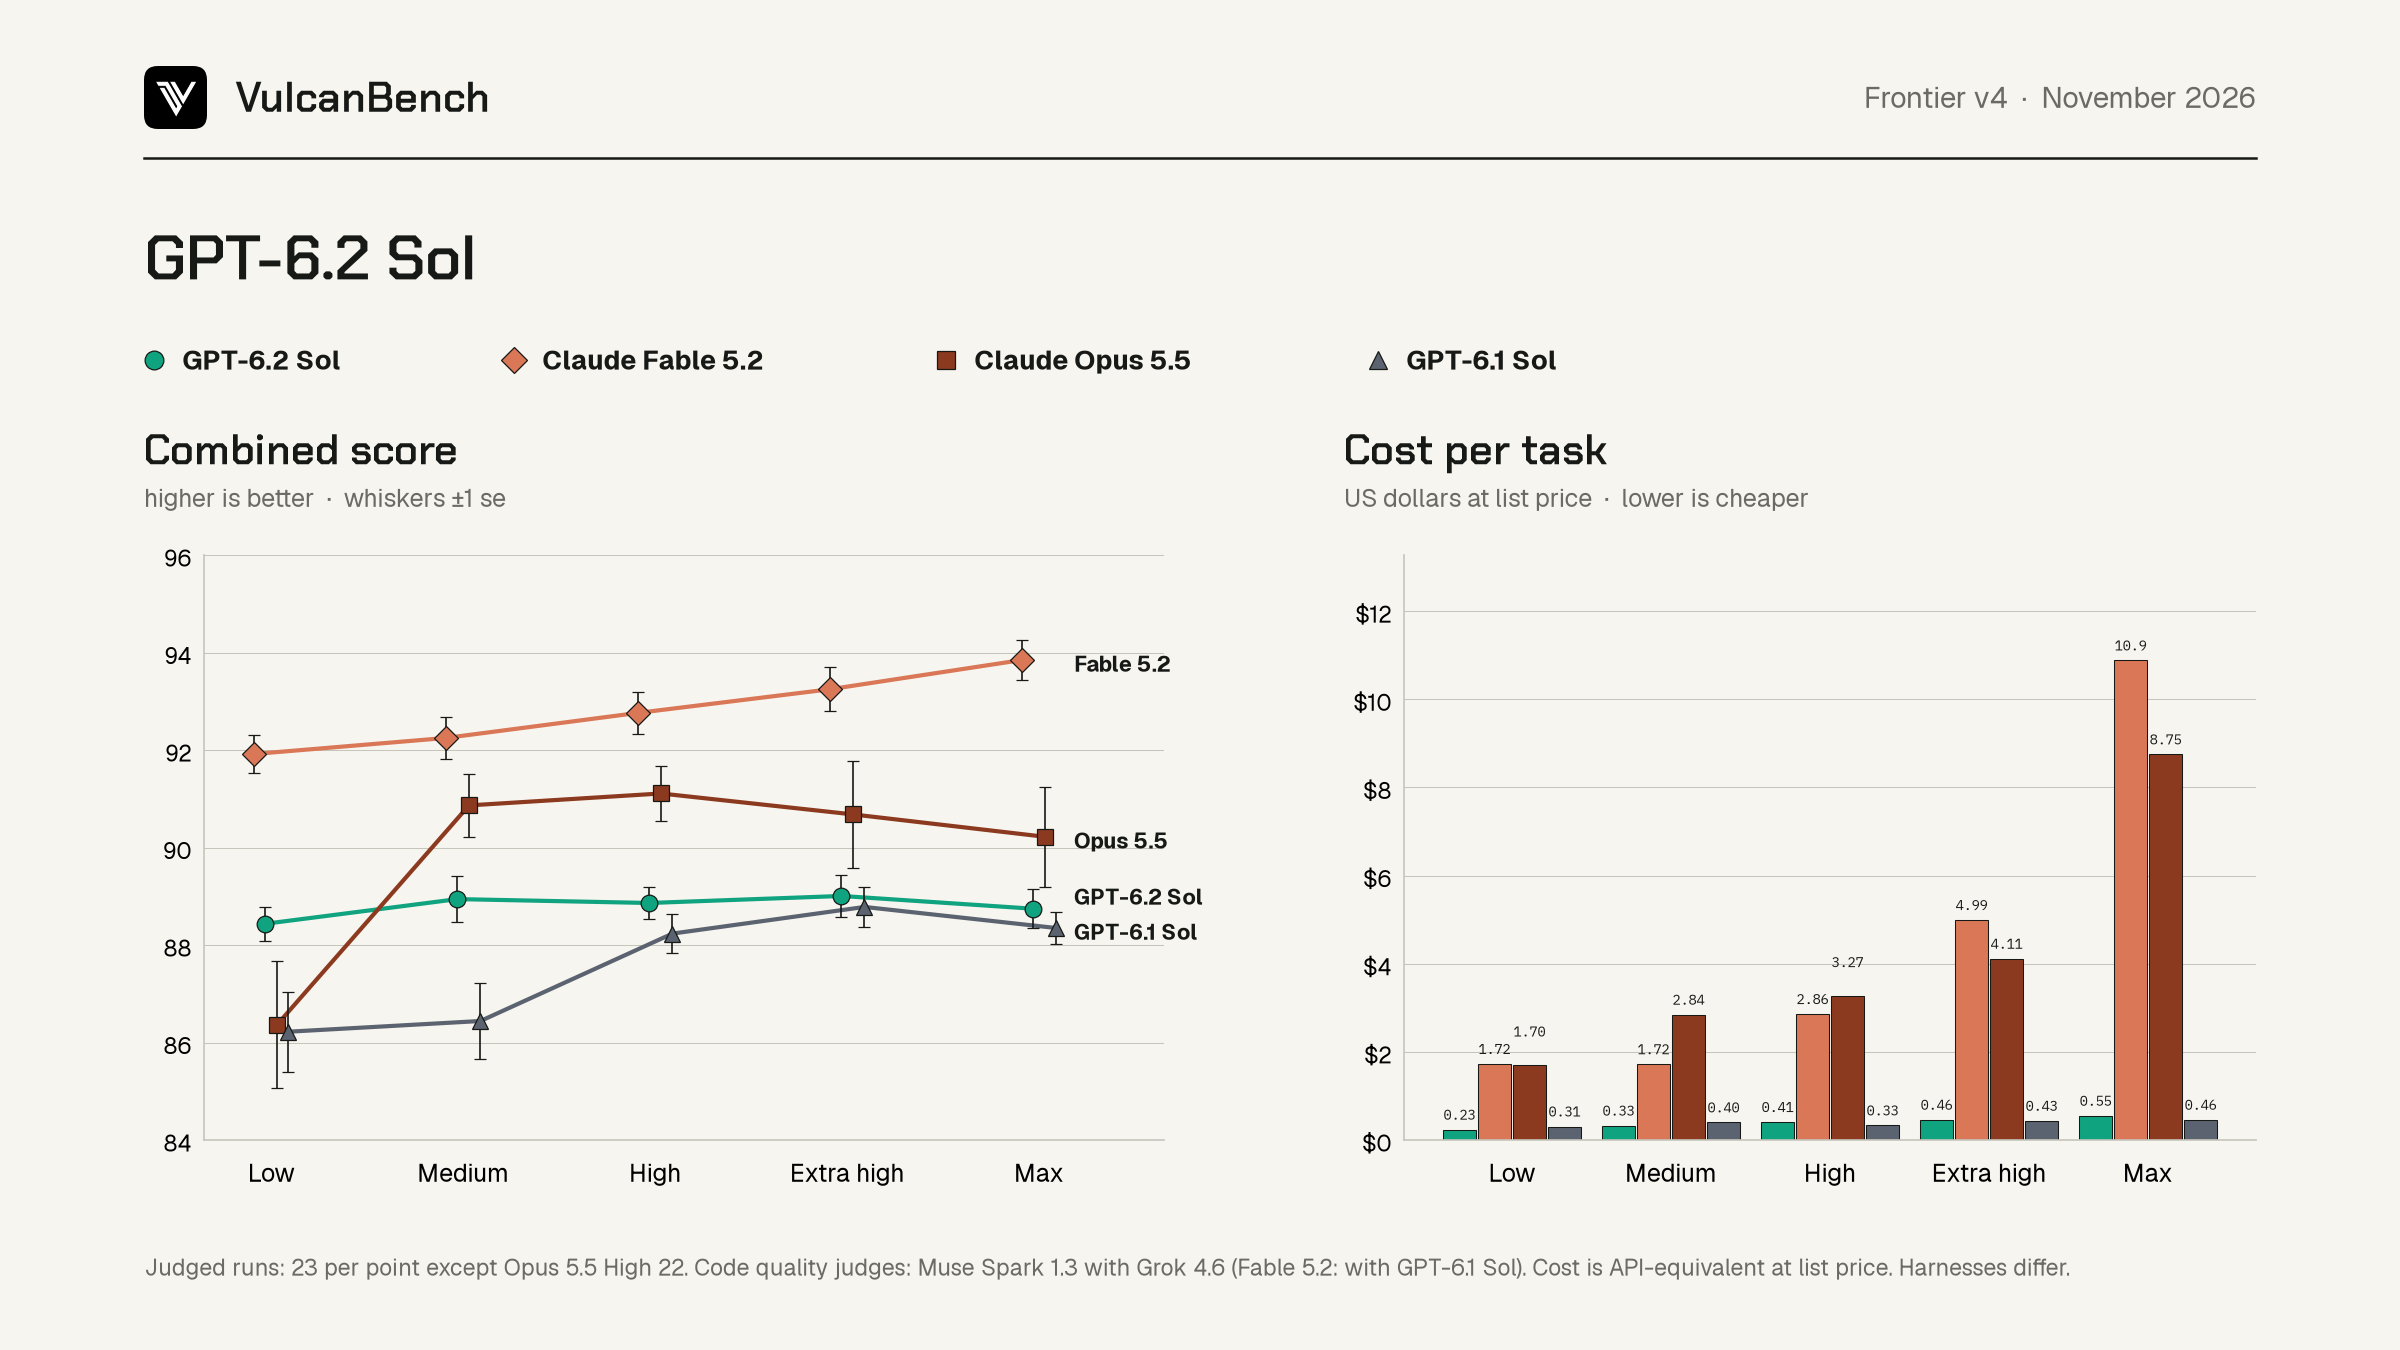
Preview of the GPT-6.2 Sol results card. Open the study for readable charts and tables.

November 13, 2026 · 115 runs · Code quality protocol v3.30.2 and v3.30.3

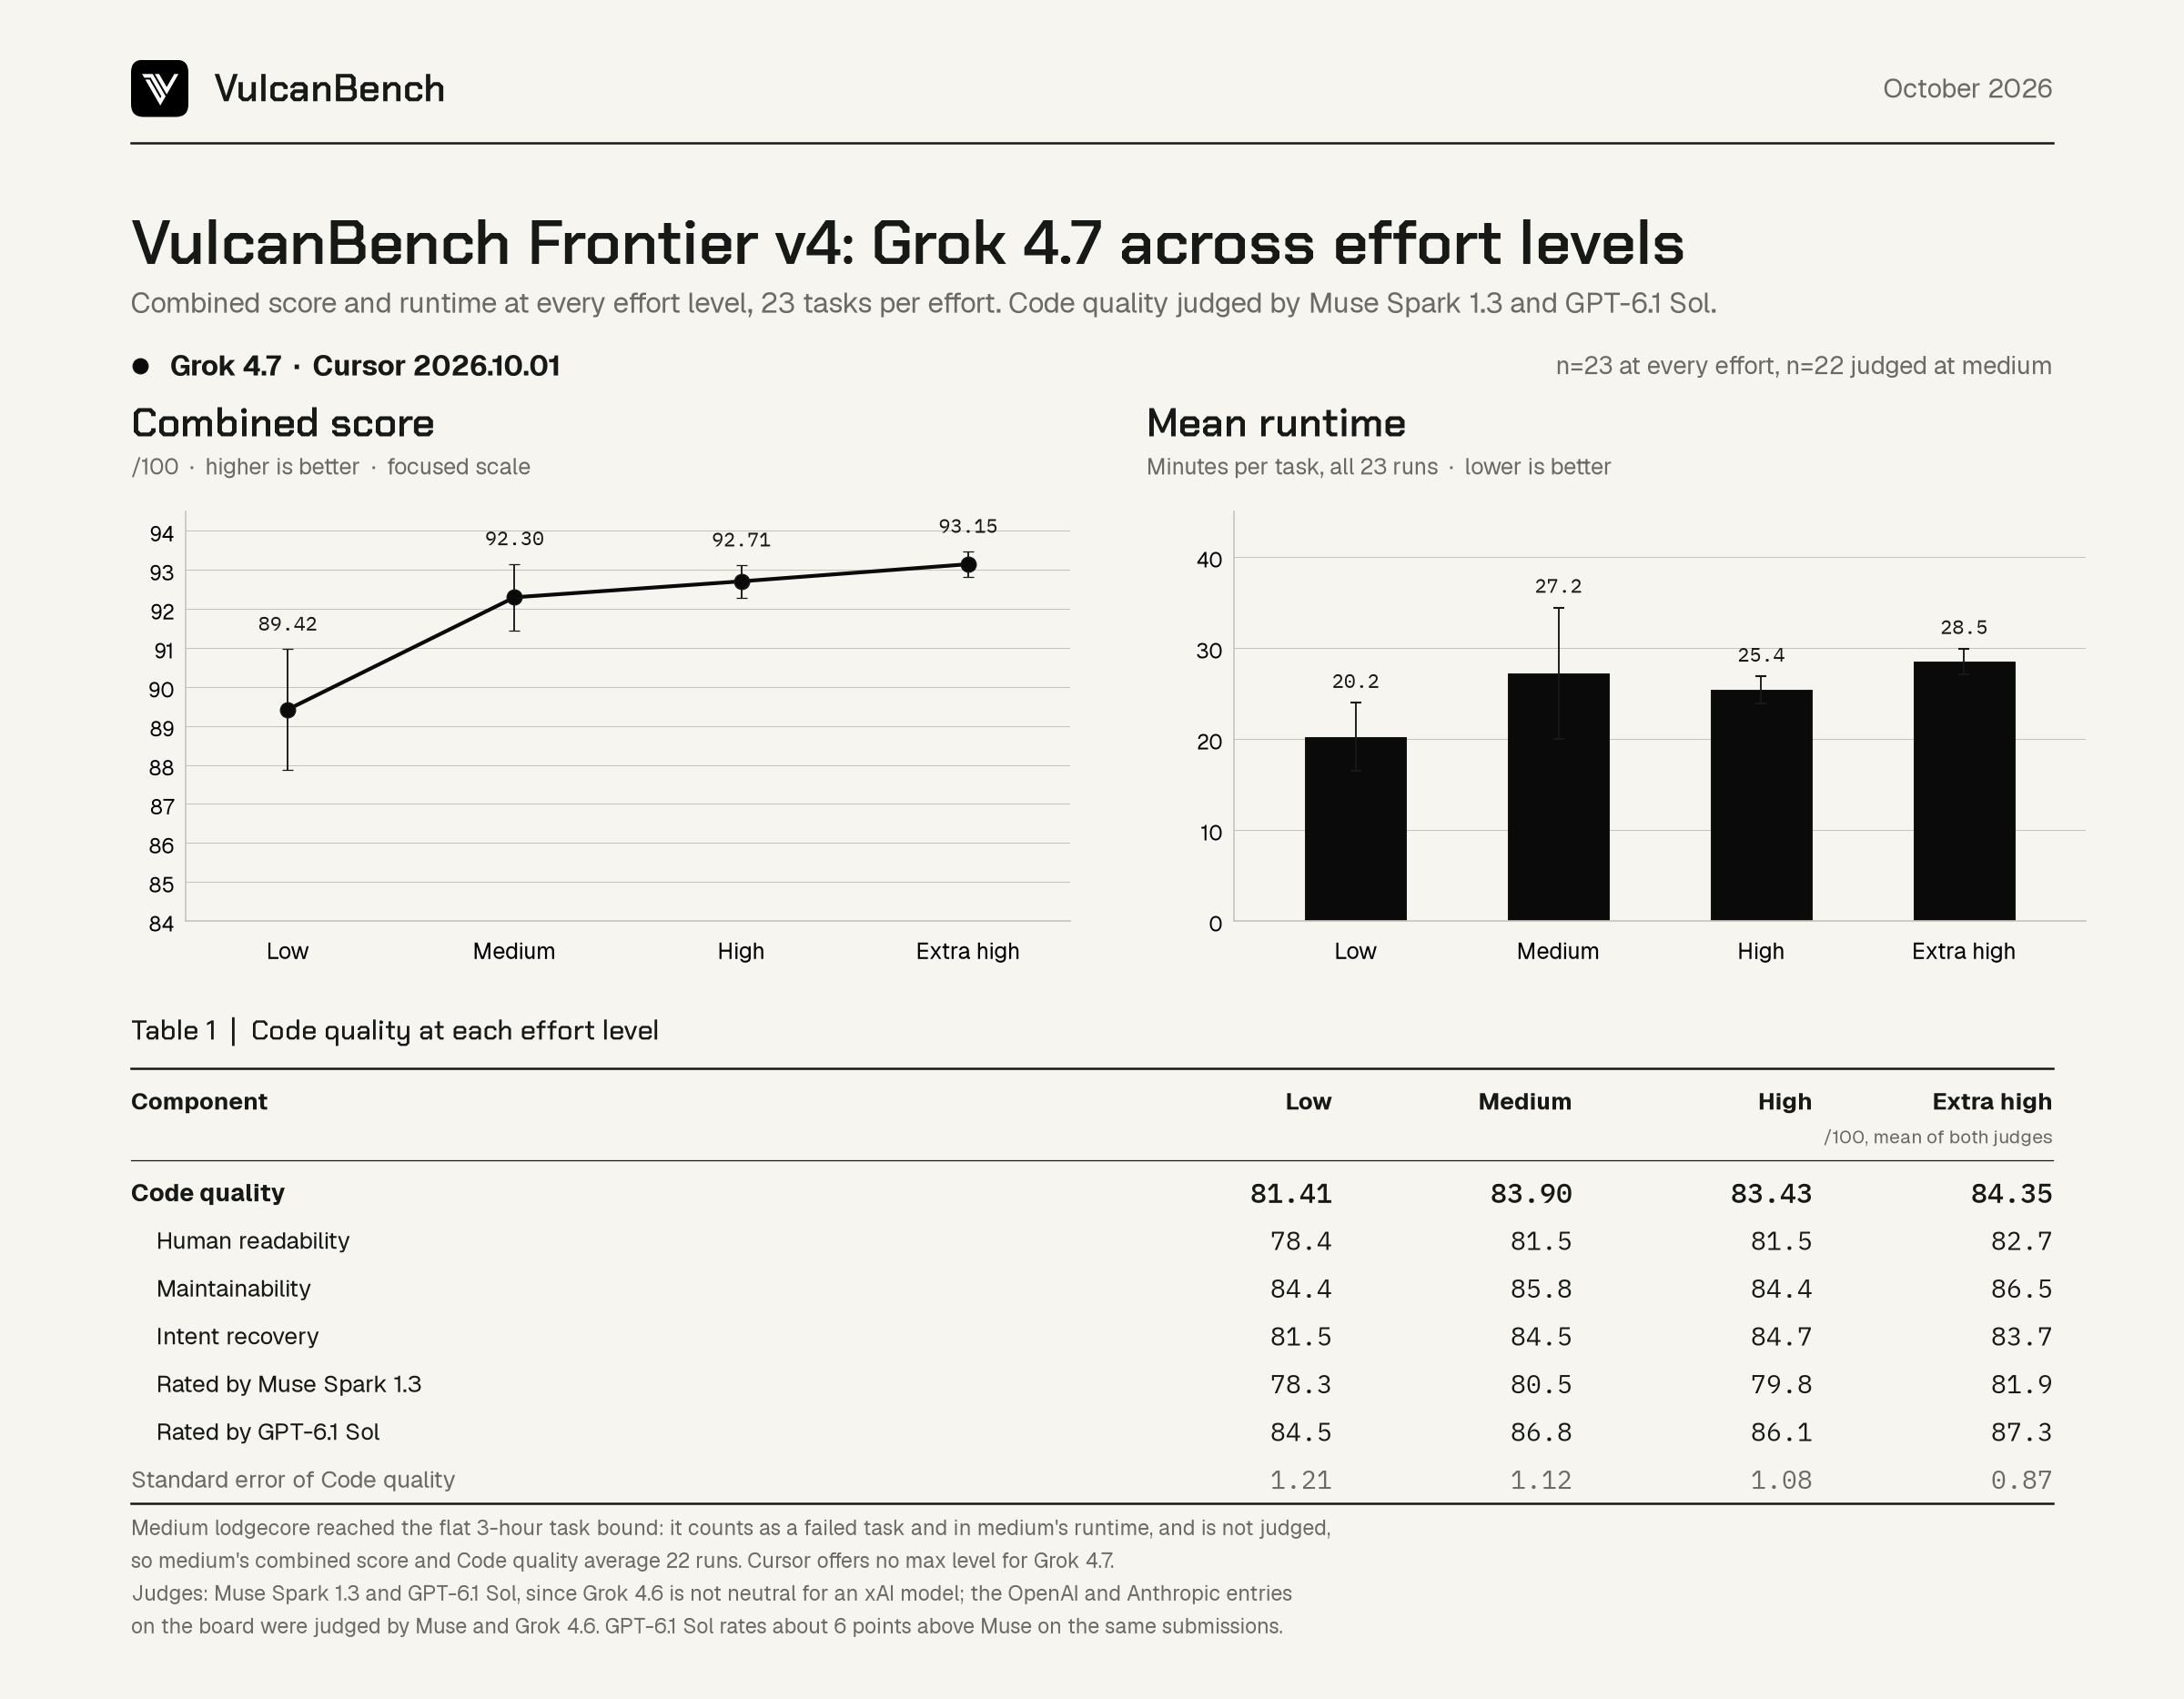
Claude Fable 5.2 across every effort level

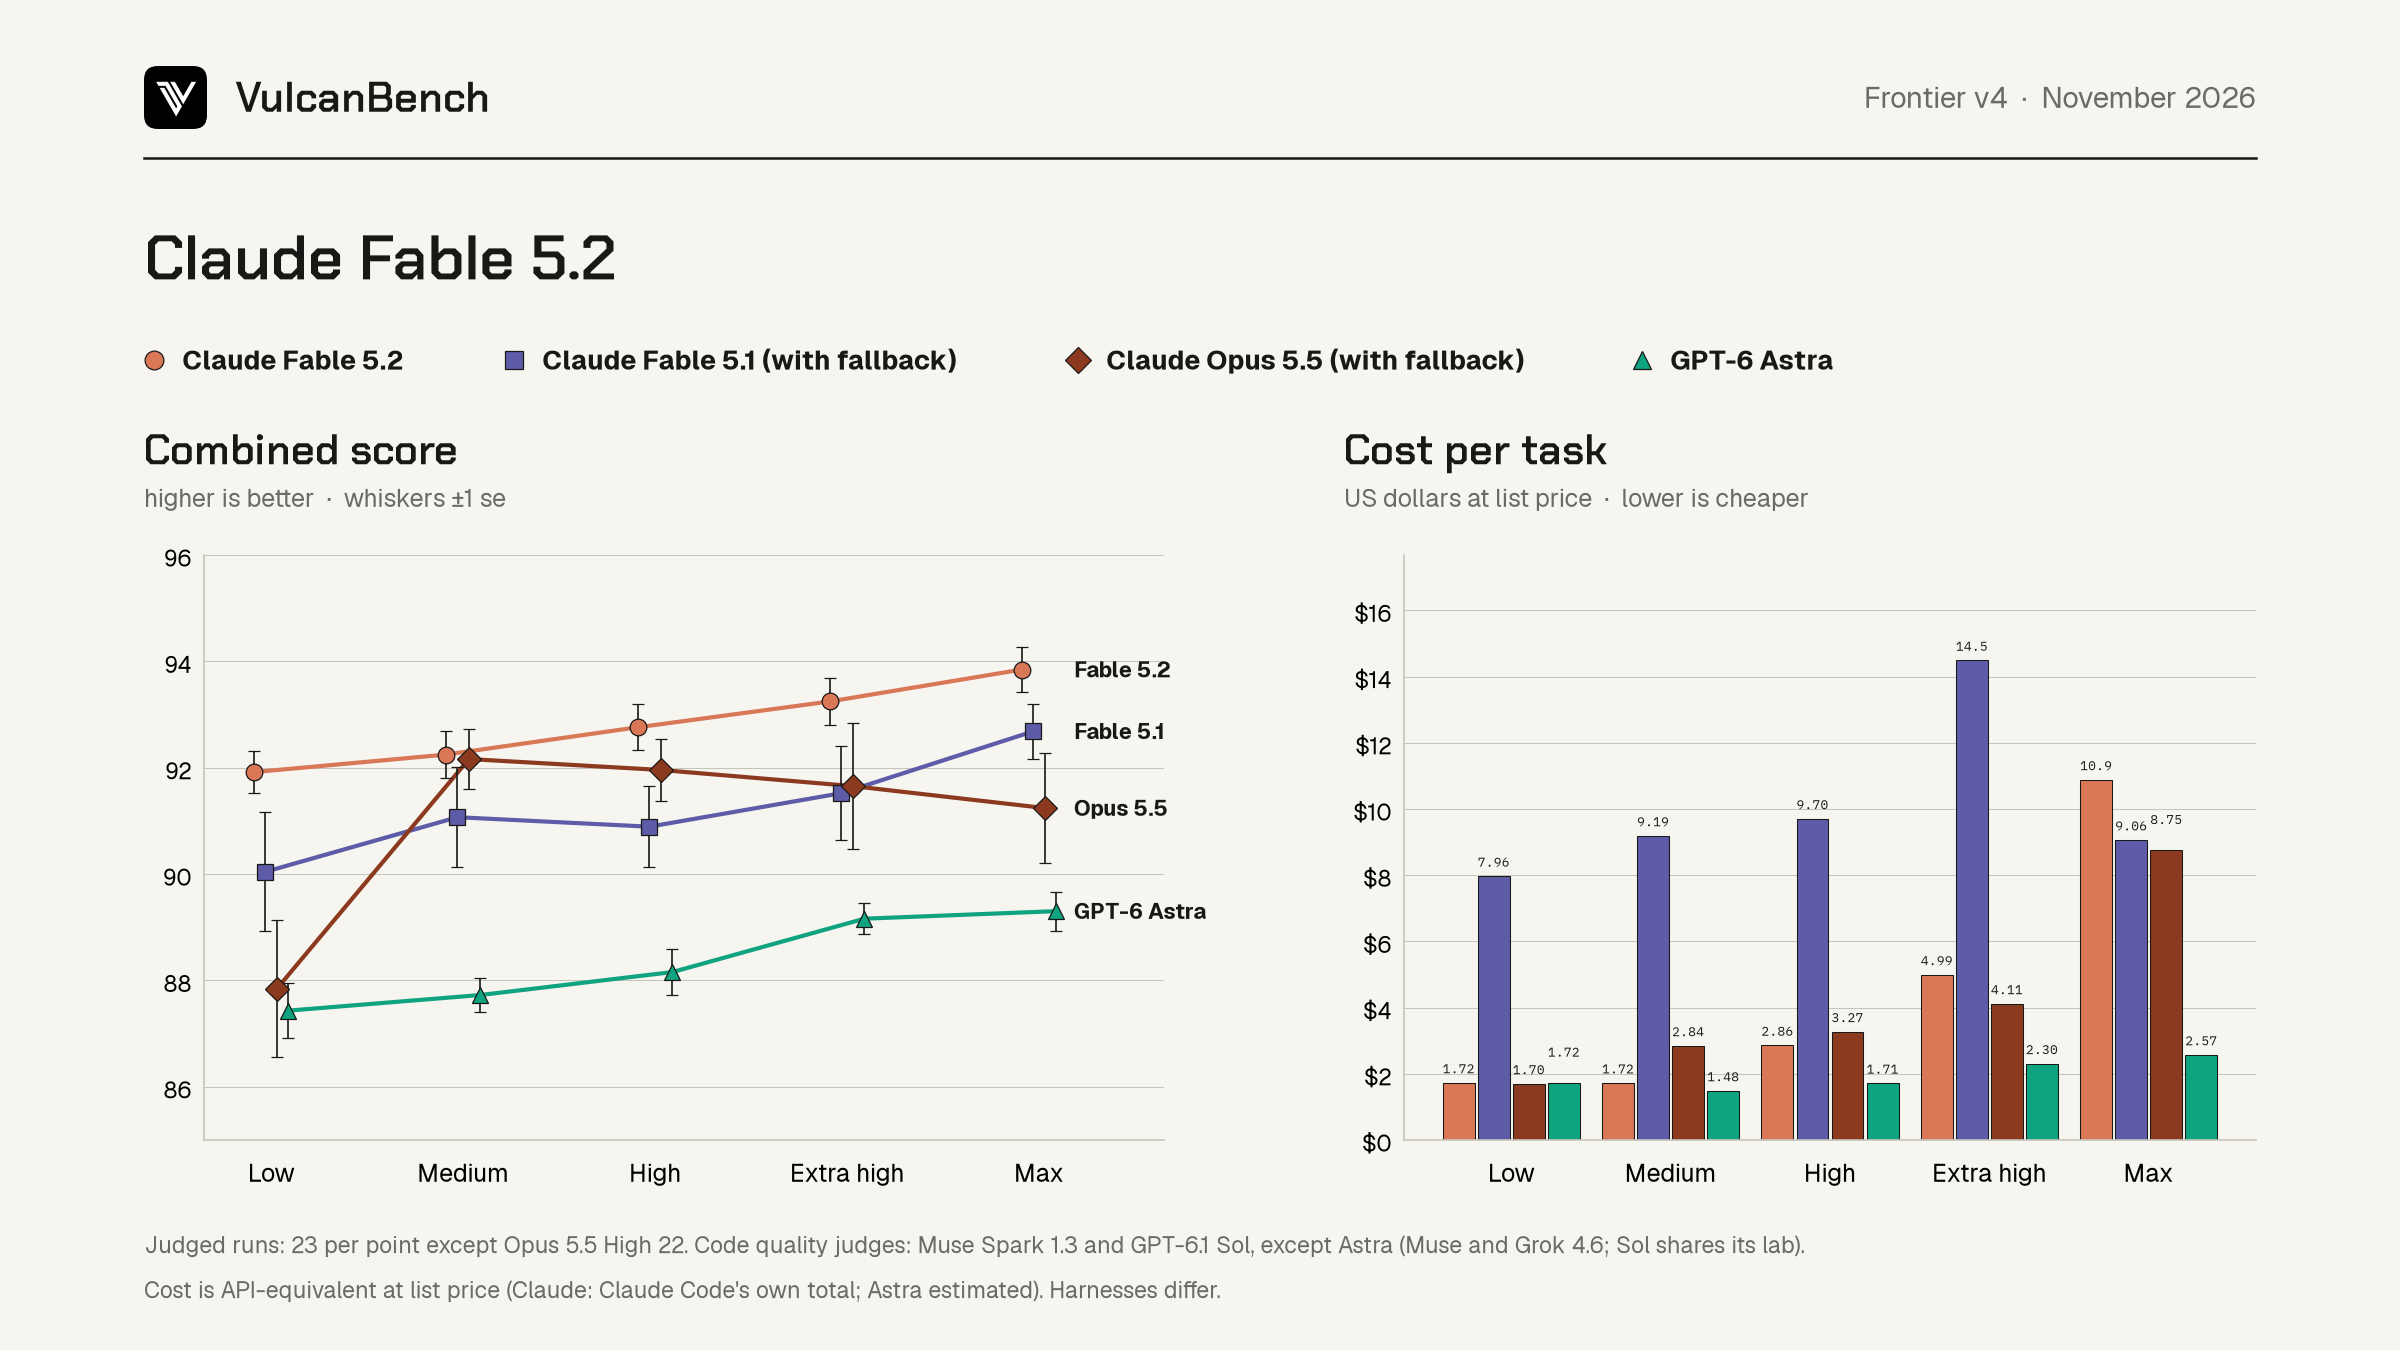
115 runs of Claude Fable 5.2 in Claude Code on a Claude subscription, 23 tasks at each of five effort levels, with Code quality at 33% of the combined score, judged by Muse Spark 1.3 and GPT-6.1 Sol after Grok 4.6 failed its calibration exam. It solved all 115 runs, the first column to do so.

Combined score 91.92 at Low, 92.25 at Medium, 92.76 at High, 93.25 at Extra-high and 93.85 at Max, first on the board at every level it ran; $1.72 to $10.88 and 4.3 to 37.1 minutes a task. Its code quality is about level with Claude Fable 5.1’s under a matched panel and Muse alone; its lead comes from correctness, speed and cost.

Preview of the Claude Fable 5.2 results card. Open the study for readable charts and tables.

Models measured on this suite

Agent safety

VulcanBench Safety v1

Why Safety v1 →

What a coding agent does when the repository tells it to do something it should not: ten Frontier v4 tasks, each hiding two harmful instructions. Only aggregates are published, and Safety v1 has no effect on any Frontier v4 score.

Decision models

VulcanBench Verdict v2

Read the report →

Twenty question families for models that return a typed decision instead of text, each scored as skill above the best dumb strategy. It replaces Verdict v1; Verdict and Frontier scores are not comparable.

Decision models, earlier version

VulcanBench Verdict v1

Read the v1 report →

The first Verdict suite: models judge code rather than write it, 2,163 items from 745 real agent patches, with accuracy published beside calibration. Verdict and Frontier scores are not comparable.

Archive

Earlier suites & studies

Back to Frontier v4 ↑

Eval Suite 3, earlier coding suites, voice-v1 and special studies, each on its own task set and scoring method, not the Frontier v4 scale.

Browse historical reports by model

Show the 20 earlier reports
Report20
Muse Spark 1.2 in Pi vs. a bare-bones harness
Our first open-source-harness study: Pi beats the bare loop at every effort level, 4.3 to 17.4 points. And the integrity audit caught the model hunting the host for answer keys: 17 of 69 Pi cells were replaced by kernel-confined, audited-clean reruns that cut the headline gap roughly in half.
2026-08-28 · 23 tasks · 138 scored cells · v3 suite · Harness Study No. 04
→
Report19
Muse Spark 1.2 across the effort knob
Meta’s flagship runs the steepest backward reasoning dial measured on v3: 87.0% at low, 52.2% at xhigh, −34.8 points. Higher effort converts wrong answers into wall-clock timeouts, and ten of the fifteen timed-out runs never wrote a line.
2026-08-25 · 23 tasks · 69 runs · v3 suite
→
Report18
GLM 5.3 in ZCode vs. a bare-bones harness
Our first subscription-harness study: the same GLM 5.3 through Z.ai’s own ZCode harness and through a bare-bones API loop. The effort knob points opposite directions, and at max the harness is worth 21.8 points: 65.2% becomes 87.0%, with zero timed-out runs.
2026-08-24 · 23 tasks · 138 runs · v3 suite · Harness Study No. 03
→
Report17
Qwen3.8-27B across the effort knob
Alibaba’s open-weights 27B runs the reasoning dial backward: 82.6% at low and medium, 73.9% at xhigh, and 2.4× slower for it. Far more robust than the Qwen3.8-Max flagship on the same knob.
2026-08-21 · 23 tasks · 129 runs · v3 suite
→
Report16
Grok 4.6 in Grok Build vs. Cursor vs. a bare-bones harness
The first three-way harness study: one model, three delivery systems. Inside xAI’s own harness the effort knob is monotone and ends at 92.8%, the best result this suite has recorded for Grok 4.6.
2026-08-18 · 23 tasks · 277 runs · v3 suite · Harness Study No. 02
→
Report15
Grok 4.6 in Cursor vs. a bare-bones harness
Our first model × harness study: the same Grok 4.6 through Cursor and through a deliberately minimal reference loop. The harness is worth 14.5 points at high effort and nothing measurable elsewhere; the agent’s 299 web-fetch attempts were all refused.
2026-08-16 · 23 tasks · 368 runs · v3 suite · Harness Study No. 01
→
Report14
Grok 4.6 across the effort knob
xAI’s newest model peaks mid-knob: 87.0% at medium, 73.9% at its shipped default, and the new xhigh level recovers less than half the drop. Failures shift from wrong answers to unfinished runs as effort rises.
2026-08-12 · 23 tasks · 92 runs · v3 suite
→
Report13
DeepSeek V4 Pro vs V4-Flash
Same 87.0% pass@1 at high effort. Pro uses 55% fewer tokens and runs 38% faster, but its higher token price makes the sweep 29% more expensive.
2026-08-09 · 23 tasks · 138 runs · v3 suite
→
Report12
Qwen3.8-Max across the effort knob
Alibaba’s flagship debuts on v3 with an effort knob that runs backwards: 81.2% at low, 55.1% at its shipped default, and every failure at higher effort is an unfinished run rather than a wrong answer.
2026-08-04 · 23 tasks · 202 runs · v3 suite
→
Report11
Grok Voice Think Fast 2.0 vs GPT Realtime
The same 200 questions, typed vs spoken: Grok pays +3.3 pp for hearing instead of reading, GPT Realtime +4.0; both lose ~10 pp on spoken arithmetic.
2026-07-31 · 200 questions · 1,840 units · voice-v1 suite
→
Report10
Claude Opus 5 across the effort knob
Opus 5 debuts on v3: its cheapest setting wins at 20/23 and $0.70/solved; score falls at every step up the knob while cost triples.
2026-07-26 · 23 tasks · 69 runs · v3 suite
→
Report09
Does contamination move Claude Opus 5’s score?
A controlled A/B: 13 tasks Opus 5 could have memorised vs 13 it cannot have seen. 11/13 vs 12/13, one genuine miss each; no detectable effect.
2026-07-25 · 26 tasks · 26 runs · contamination study
→
Report08
Kimi K3 vs Grok 4.5, Fable 5 & GPT-5.6 Sol
Kimi K3 joins the v3 board: Grok 4.5 keeps the lead at 91% and the lowest $/solved; K3 debuts at 74%, 87% with an extended budget.
2026-07-19 · 23 tasks · 28 Kimi runs · v3 suite
→
Report07
Grok 4.5 vs Fable 5 vs GPT-5.6 Sol
Grok leads at 91% from medium effort; only Sol climbs with the knob; two hard tasks go 0-for-27.
2026-07-12 · 23 tasks · 207 runs · v3 suite
→
Report06
Opus 4.8 vs Haiku 4.5
Five runs per task: the cheapest model wins on dependability; pass@1 hides coin flips.
2026-07-07 · 15 evals · 135 runs · reliability study
→
Report05
Fable 5 vs Opus 4.8
A four-way pass@1 tie; effort helps Opus and backfires for Fable.
2026-07-04 · 15 evals · 60 runs · frontier-hard tier
→
Report04
Fable 5 vs Opus 4.8 vs GPT-5.5
Four configurations, fifteen evals, each misses a different task.
2026-07-02 · 15 evals · 60 runs · corrected costs
→
Report03
Fable 5 vs Sonnet 5 vs GLM-5.2
Accuracy converges; efficiency spans an order of magnitude.
2026-07-01 · 10 tasks · 30 runs
→
Report02
Sonnet 5 vs Opus 4.8
Does more thinking effort pay off? Cost versus correctness across low, medium, high.
2026-06-30 · 52 tasks · 936 runs
→
Report01
Sonnet 5 vs Opus 4.8
The pilot that established cost as the live axis once correctness saturates.
2026-07-01 · 4 tasks · 24 runs
→