October 12, 2026 · 115 runs · Code quality protocol v3.24
Claude Haiku 5.5 across every effort level
115 runs of Claude Haiku 5.5 through Claude Code on a Claude Max subscription, 23 tasks at each of five effort levels, Low to Max. Code quality carries 33% of the combined score and is judged for a human reader by Muse Spark 1.3 and Grok 4.6 under the same rubric, controls and gates as the other Frontier v4 reports, so Haiku 5.5 takes its place on the Frontier v4 leaderboard beside Claude Sonnet 5.5 and Claude Opus 5.5. Every run finished inside the 3-hour task bound. Four runs carry no Code quality score: three that a safety classifier stopped with an empty patch, and one whose judge probe had no valid answer; all four count in tasks passed, time and cost. For Haiku 5.5 beside Claude Sonnet 5.5, GPT-6.1 Sol and GPT-6 Luna, see the comparison page.
How the test works
A retired program to rebuild
Each of the 23 tasks is a legacy binary with a written specification and an issue. Its real behaviour departs from the specification in documented ways, and hidden tests check the rewrite against the binary.
One attempt per task and level
Claude Haiku 5.5 works in Claude Code with the binary, the specification and the code, once per task at each effort level, inside a flat 3-hour bound, one task at a time.
Tests and two judges score it
Hidden tests give functional correctness. Two calibrated judges from labs other than Anthropic rate the code for a human reader and try to recover the documented departures.
Scores, time and cost per level
Each level gets a combined score, tasks passed, minutes and cost. Cost is Claude Code’s own list-price total for each run, beside a floor and a ceiling for Haiku’s two price tiers.
Combined score = 50% functional correctness + 8.5% lint and complexity + 8.5% security + 33% Code quality, averaged over the judged runs in each level, as on every other board column. Frontier Code quality is the reviewed layer plus intent recovery; it is never compared with Routine v1 Code quality.
Across every effort level
Claude Haiku 5.5 (claude-haiku-5-5) ran every task once at each of its five effort levels, 23 tasks per cell, through Claude Code 2.1.293 to 2.1.296 on a Claude Max subscription, from October 8, 10:40 UTC, to October 11, 22:49 UTC, 2026, on the owner’s Mac in the local sandbox, one task at a time, with two pauses between tasks. Combined score weights are 50% functional correctness, 8.5% lint and complexity, 8.5% security and 33% Code quality, judged for a named human reader by Muse Spark 1.3 and Grok 4.6 with a ground-truth intent-recovery probe. No run reached the flat 3-hour task bound; the longest, Medium depotcore, took 126 minutes. Anthropic’s default effort for Haiku 5.5 is Medium, on the API and in Claude Code.
Combined score
84.03 to 92.16
Combined score is 84.42 at Low and 84.03 at Medium, then rises to 88.01 at High, 91.83 at Extra-high and 92.16 at Max. Standard errors narrow from 1.97 and 2.50 at Low and Medium to 0.39 and 0.37 at the top two levels.
Tasks passed
13 of 23 at Low and Medium, 22 of 23 from Extra-high
pass@1 is 0.565 (±0.106) at Low and Medium, 0.739 (±0.094) at High and 0.957 (±0.043) at Extra-high and Max. Of the 231 hidden behaviours the tasks test for, it fixes 202, 195, 215, 216 and 216. The one task missed at Extra-high and Max is paddockcore, stopped by a safety classifier.
Code quality
74.83 to 81.30
Code quality rises at every step, from 74.83 at Low to 81.30 at Max, with standard errors of 1.03 to 1.58.
Runtime and cost
19.0 to 27.7 min · $0.84 to $1.54 per task
Extra-high is the fastest and cheapest level (19.0 minutes, $0.84 a task); Max is the slowest and dearest (27.7 minutes, $1.54). The whole sweep comes to $138.31 as Claude Code reports it, between a floor of $31.10 and a ceiling of $155.50.
| Metric | Low | Medium | High | Extra-high | Max |
|---|---|---|---|---|---|
| Combined score | 84.42 | 84.03 | 88.01 | 91.83 | 92.16 |
| Standard error | 1.97 | 2.50 | 1.42 | 0.39 | 0.37 |
| Judged runs | 23 | 22 | 23 | 22 | 21 |
| Tasks passed | 13/23 | 13/23 | 17/23 | 22/23 | 22/23 |
| Hidden behaviours fixed | 202/231 | 195/231 | 215/231 | 216/231 | 216/231 |
| Code quality | 74.83 | 76.07 | 77.60 | 80.13 | 81.30 |
| Human readability | 71.1 | 74.1 | 73.9 | 76.9 | 78.7 |
| Minutes per task | 22.9 | 24.0 | 26.8 | 19.0 | 27.7 |
| Standard error of minutes | 5.4 | 6.4 | 3.3 | 1.9 | 2.6 |
| $ per task (Claude Code) | $1.04 | $1.36 | $1.25 | $0.84 | $1.54 |
| Standard error of $ per task | $0.33 | $0.52 | $0.34 | $0.16 | $0.28 |
Under the prior 50/15/15/20 profile applied to the same Code quality scores the ladder runs 85.92 to 93.31. Runtime and cost here cover every run; the score card averages the judged runs, so its minutes and cost at Medium, Extra-high and Max (24.9, 19.4 and 27.9 minutes; $1.41, $0.87 and $1.55) differ slightly from these, and its tasks-passed row at Max counts the 21 judged runs (21 of 21).
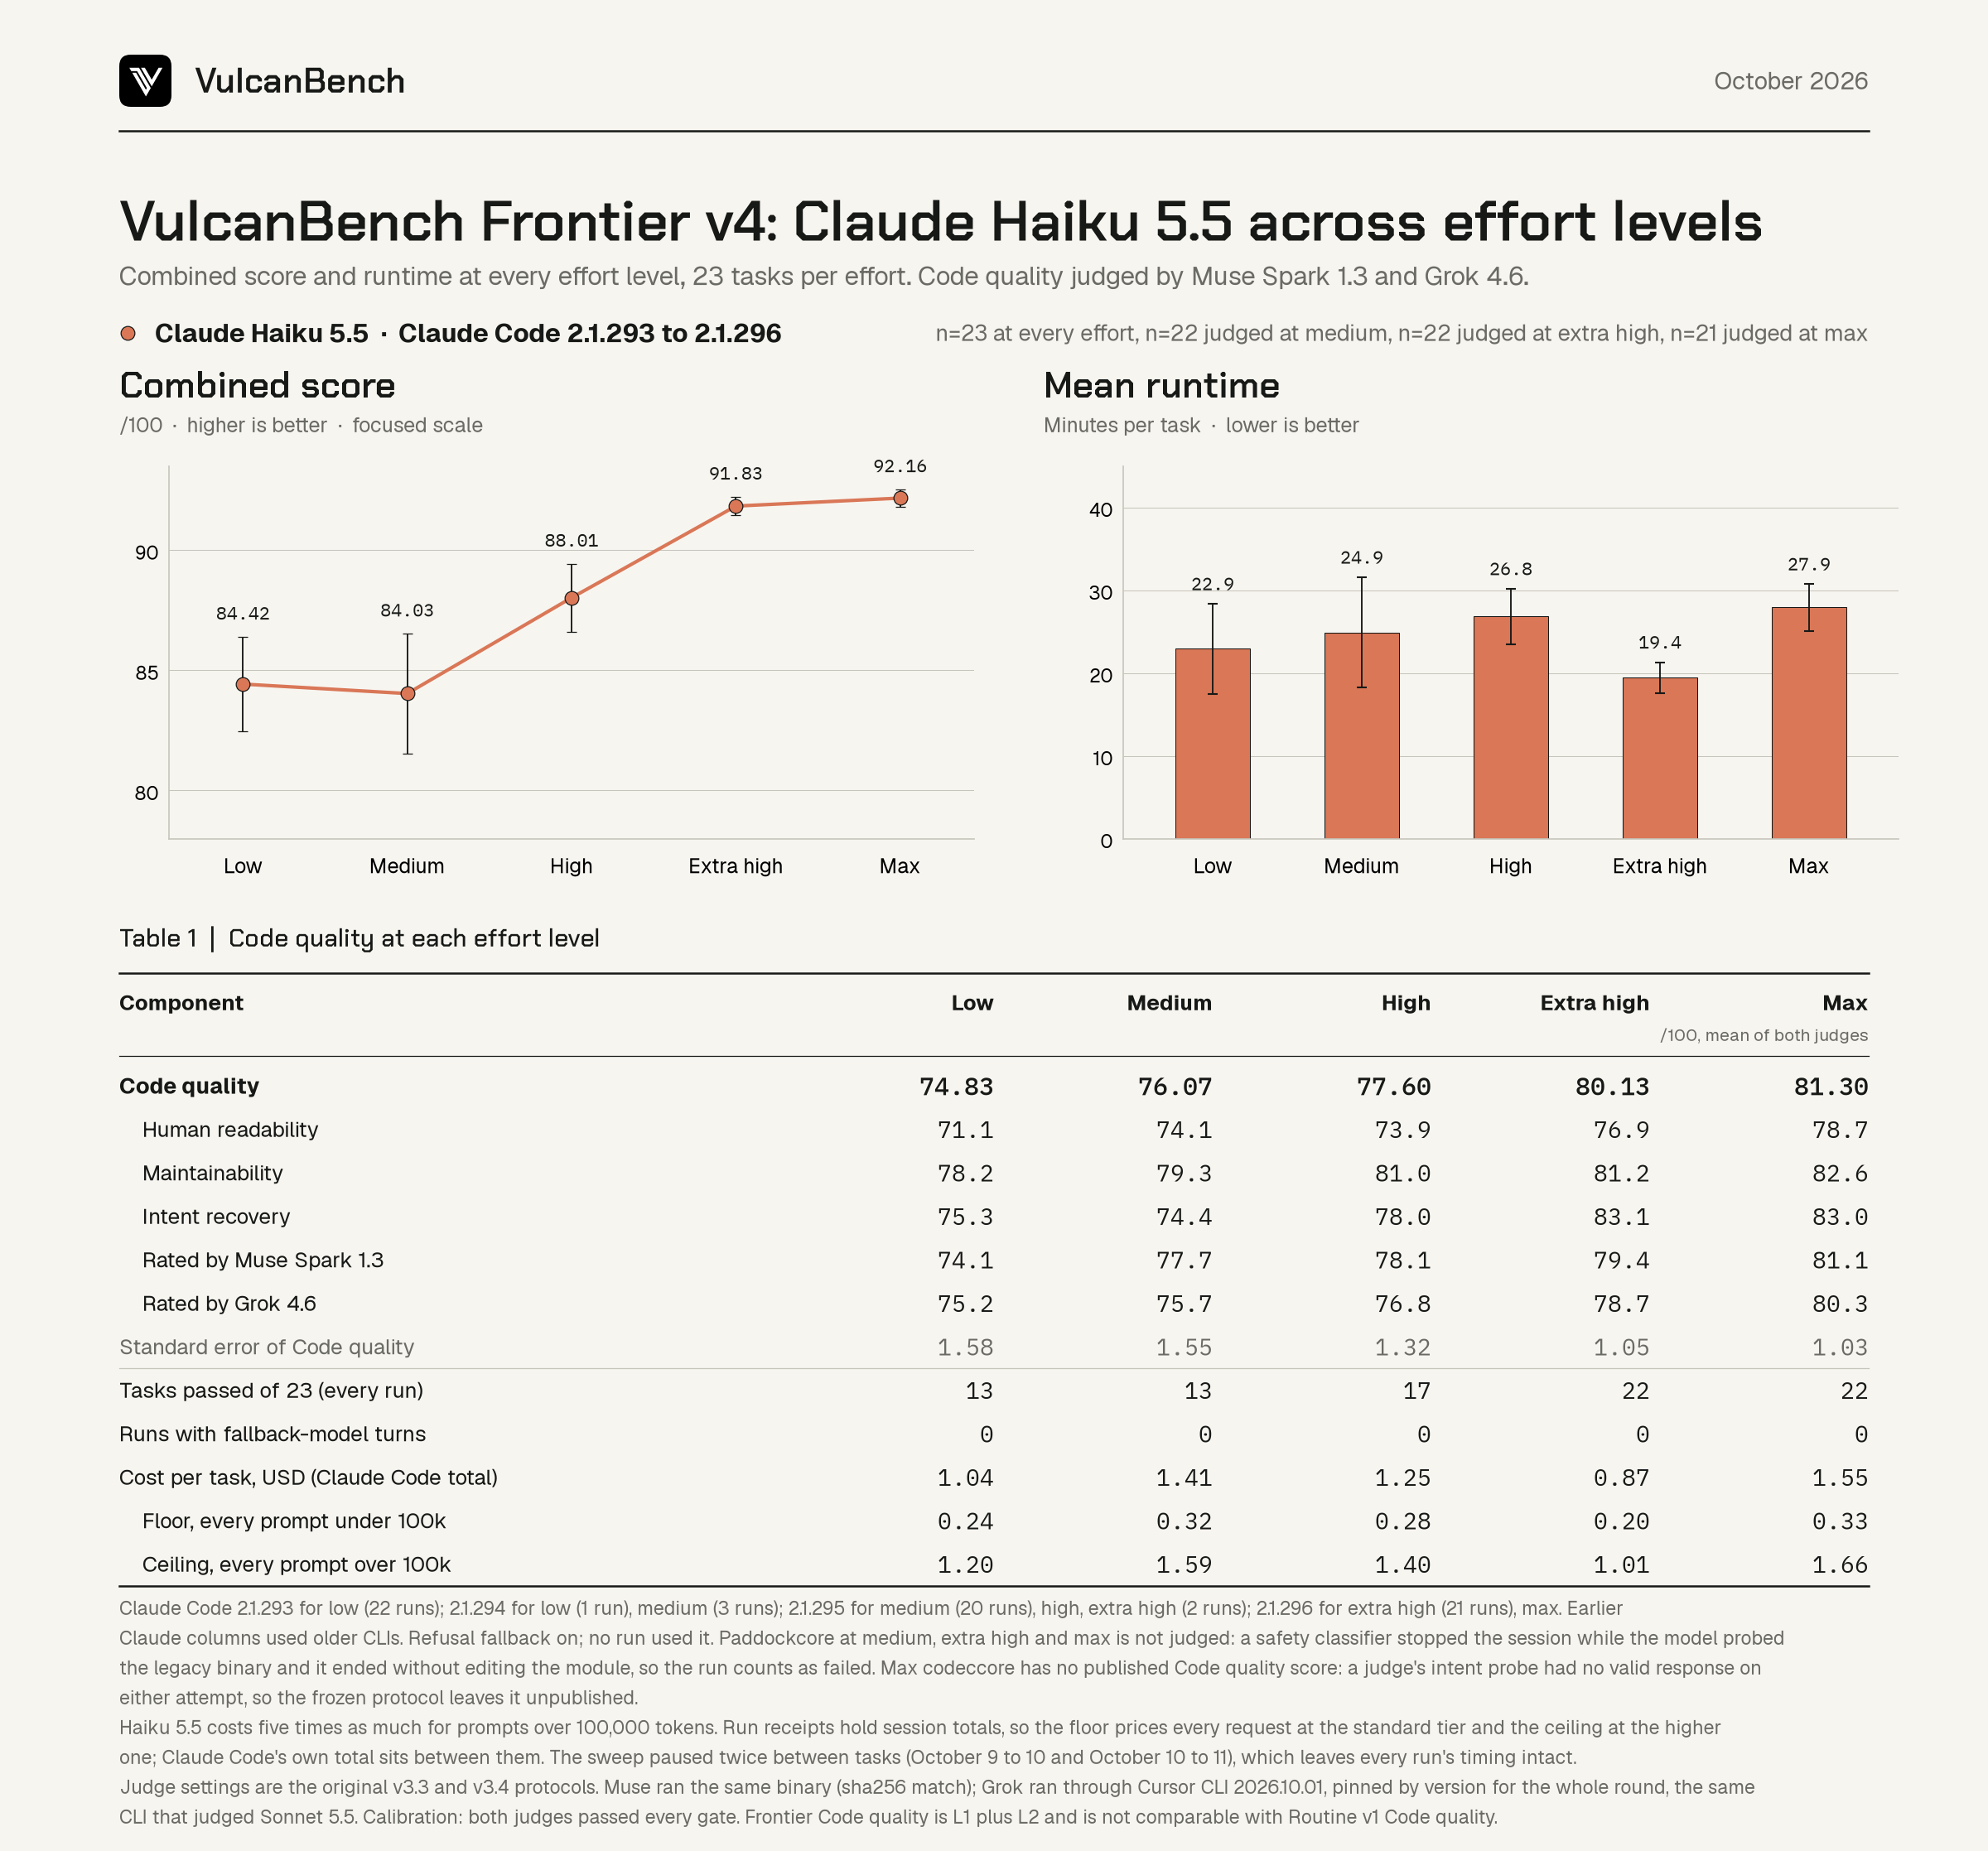
Haiku 5.5 is flat from Low to Medium and climbs from High: Extra-high and Max are within 0.33 points of each other and both pass 22 of 23 tasks, the one miss at each being paddockcore, stopped by a safety classifier. At Max it has the highest combined point estimate of any column judged by Muse Spark 1.3 and Grok 4.6, level with Claude Sonnet 5.5 at Max (92.02 ± 0.35) within the errors. These runs compare a model-and-harness combination, not an isolated base model; the Frontier v4 leaderboard places every Haiku 5.5 effort level beside the other models judged under the same rubric.
Combined score and Code quality by effort
n=23 runs at every level; the Judged column gives the runs with a published Code quality score (* fewer than 23, see the next section). Combined (33%) is the published score over the judged runs. Combined (20% profile) applies the prior 50/15/15/20 weights to the same Code quality scores for comparison. Code quality, human readability, maintainability and intent recovery are out of 100 and equal means of the two judges. Passed counts all 23 runs. Runtime is solver wall-clock per task over every run in the cell.
| Model / harness | Effort | Combined (33%) | SE | Combined (20% profile) | Code quality | Human readability | Maintainability | Intent recovery | Judged | Passed | Min/task |
|---|---|---|---|---|---|---|---|---|---|---|---|
| Claude Haiku 5.5 / Claude Code | Low | 84.42 | 1.97 | 86.45 | 74.83 | 71.1 | 78.2 | 75.3 | 23/23 | 13/23 | 22.9 |
| Claude Haiku 5.5 / Claude Code | Medium | 84.03 | 2.50 | 85.92 | 76.07 | 74.1 | 79.3 | 74.4 | 22/23* | 13/23 | 24.0 |
| Claude Haiku 5.5 / Claude Code | High | 88.01 | 1.42 | 89.69 | 77.60 | 73.9 | 81.0 | 78.0 | 23/23 | 17/23 | 26.8 |
| Claude Haiku 5.5 / Claude Code | Extra-high | 91.83 | 0.39 | 93.18 | 80.13 | 76.9 | 81.2 | 83.1 | 22/23* | 22/23 | 19.0 |
| Claude Haiku 5.5 / Claude Code | Max | 92.16 | 0.37 | 93.31 | 81.30 | 78.7 | 82.6 | 83.0 | 21/23* | 22/23 | 27.7 |
Four factors by effort, over the judged runs. Functional correctness averages 88.72, 87.03, 94.06, 100.00 and 100.00 from Low to Max; lint and complexity 80.85, 81.73, 81.99, 81.47 and 81.31; security 100.00, 99.55, 98.91, 99.55 and 99.05. Only the Code quality factor depends on the judges.
Intent recovery is scored over the specification departures a submission actually passed tests for. Every judged Haiku 5.5 run passed at least one, so no run fell back to the reviewed score alone. SE is one sample standard error across the cell’s judged tasks. It describes task sampling, not judge uncertainty, repeated runs or a significance test. Every published run is the equal mean of both judges, and neither judge produced a reviewer fallback.
Four runs without a Code quality score
- Three safety-classifier stops. On paddockcore at Medium, Extra-high and Max, a safety classifier stopped the session while Haiku 5.5 probed the legacy binary, after 4.7, 9.3 and 29.7 minutes, and the run ended with an empty patch: there is no code to review. As for Claude Opus 5.5’s High depotcore, these runs are excluded from judging, count as failed tasks, and are priced and timed. The combined score at those three levels is over the judged runs, so it does not include these failures; tasks passed does.
- Max codeccore is unpublished. Grok 4.6’s intent probe for this run gave no valid answer after the protocol’s single retry: attempt 1 quoted a code line absent from the run, which no recovery rule accepts, and attempt 2 was not valid JSON. The frozen protocol therefore publishes no Code quality or combined score for the run, exactly as for the same task under v3.7 and v3.17. The run passed its tests, so it counts as a passed task, and it is priced and timed.
Max is therefore judged on 21 of 23 runs, and Medium and Extra-high on 22.
Cost, tokens and Haiku’s price tiers
Haiku 5.5 has two list prices per token. Anthropic’s pricing page, checked October 7, 2026, charges $0.10 input, $0.125 for 5-minute cache writes, $0.01 for cache reads and $0.50 output per million tokens for prompts up to 100,000 tokens, and five times as much on every line ($0.50, $0.625, $0.05 and $2.50) for prompts over 100,000 tokens. Claude Code’s receipts hold the session’s cumulative usage, not the size of each request, so a run cannot be split between the tiers after the fact. Each run therefore carries three figures: Claude Code’s own list-price total (cli_reported_cost_usd, which prices each request at its own tier and is the published cost), a floor that prices every request at the standard tier, and a ceiling that prices every request at the higher one. Haiku 5.5 ran on a Claude Max subscription, so all three are API-equivalent estimates, not bills; judging is excluded.
| Effort | Runs | $/task | ±SE | Floor | Ceiling | Level total | Tokens/task | Min/task |
|---|---|---|---|---|---|---|---|---|
| Low | 23 | $1.04 | $0.33 | $0.24 | $1.20 | $23.82 | 14.51M | 22.9 |
| Medium | 23 | $1.36 | $0.52 | $0.31 | $1.53 | $31.17 | 19.47M | 24.0 |
| High | 23 | $1.25 | $0.34 | $0.28 | $1.40 | $28.69 | 16.98M | 26.8 |
| Extra-high | 23 | $0.84 | $0.16 | $0.20 | $0.98 | $19.31 | 9.34M | 19.0 |
| Max | 23 | $1.54 | $0.28 | $0.33 | $1.65 | $35.33 | 17.97M | 27.7 |
| Full sweep | 115 | $1.20 | $0.27 | $1.35 | $138.31 | 1,800M | 46.2 h |
Reading the floor and ceiling. Claude Code’s total sits well toward the ceiling at every level: most of Haiku 5.5’s requests carry long prompts. The floor and ceiling price cache writes at the 5-minute rate, as the harness cards do; two runs (Medium lodgecore and Max depotcore) wrote cache entries with the 1-hour lifetime, which cost more, so Claude Code’s total for them sits up to 0.4% above their ceiling.
Tokens are Claude Code’s usage for the session from its final record: input, cache reads, cache writes and output, with cache reads the bulk. Every reply in every run came from claude-haiku-5-5, so no other model’s usage is in these totals. Per-run figures are in economics.json and runs.csv.
On the Frontier v4 board
Haiku 5.5’s best level, Max at 92.16 ± 0.37 (n=21), ranks 4th of the board’s 63 model and effort columns, behind only Grok 4.7’s three top levels, which are judged by a different panel (Muse Spark 1.3 and GPT-6.1 Sol). Among columns judged by Muse Spark 1.3 and Grok 4.6 it is the highest point estimate: 0.14 points above Claude Sonnet 5.5 at Max (92.02 ± 0.35) and 0.32 above Claude Fable 5.1 at Max (91.84 ± 0.47), both well within the errors. Extra-high ranks 7th, High 25th, Low 37th and Medium 40th. The leaderboard carries every column; Haiku 5.5’s cells carry the ‡‡ footnote with the disclosures below.
The board’s combined scores are over judged runs. Haiku 5.5’s Medium, Extra-high and Max cells leave out the failed paddockcore runs that a safety classifier stopped, so read them beside tasks passed, which counts every run.
What Code quality measures
Every judge receives the same rubric, frozen by hash before any review. It names the reader it scores for: an engineer who has never seen the code, reads it top to bottom without running it, and must make a correct change in one sitting. It tells the judge that its own ease at parsing dense code is not evidence of readability. Six dimensions are scored 0 to 4 in half steps against written anchors: naming, presentation and intent form the human readability sub-score; structure, changeability and verifiability form the maintainability sub-score. Every score must cite an exact excerpt from the code and a concrete consequence for that reader. The host computes the sub-scores; the judge does no arithmetic.
The 33 points have three designed layers. The reviewed panel carries 24 points. An intent-recovery probe carries 9: the judge, given only the specification and the code, lists where the code departs from the specification, and a separate call matches that list against a frozen answer key, over the departures the submission passed tests for. The third layer, measured maintenance, is designed for 12 points but is not yet built, so the pre-registered 24 plus 9 split is in force. Frontier Code quality is therefore the reviewed layer plus intent recovery, and it is never compared with Routine v1 Code quality, which is scored on a different suite and population.
| Component | Low | Medium | High | Extra-high | Max |
|---|---|---|---|---|---|
| Code quality | 74.83 | 76.07 | 77.60 | 80.13 | 81.30 |
| Human readability | 71.1 | 74.1 | 73.9 | 76.9 | 78.7 |
| Maintainability | 78.2 | 79.3 | 81.0 | 81.2 | 82.6 |
| Intent recovery | 75.3 | 74.4 | 78.0 | 83.1 | 83.0 |
| Rated by Muse Spark 1.3 | 74.1 | 77.7 | 78.1 | 79.4 | 81.1 |
| Rated by Grok 4.6 | 75.2 | 75.7 | 76.8 | 78.7 | 80.3 |
| Standard error of Code quality | 1.58 | 1.55 | 1.32 | 1.05 | 1.03 |
Both sub-scores rise with effort, human readability from 71.1 to 78.7 and maintainability from 78.2 to 82.6, and readability is the weaker of the two at every level. The two judges agree closely: within 2.1 points at every level, Grok 4.6 higher at Low and Muse Spark 1.3 higher from Medium up. Per-run sub-scores from each judge are in runs.csv; the exact rubric, system text, probe and match instructions are in judge-protocols.json.
Judges and calibration
The scored panel is Muse Spark 1.3 (Meta) through the Muse CLI on its Standard tier, and Grok 4.6 (xAI) through the Cursor CLI at medium effort, with equal weight. Both judges are from labs other than Anthropic, so neither grades a relative of Haiku 5.5. Every session is fresh, tools are disabled, the workspace is empty, model identity is checked per call from the CLI’s own records, and solver labels are withheld. Protocol v3.24 changes nothing in the rubric, controls, quirk keys, gates, repeats, seed, weights or judge settings from v3.23; it applies the protocol to this population, and both judges retook the calibration exam under it before any counted call.
Judge settings and versions. The judge settings are read from the original v3.3 and v3.4 protocol files, recovered from the owner’s private backup, whose sha256 equal the published values (v3.3 b82da598, v3.4 1d80e097). Muse Spark 1.3 ran the same binary as every earlier round (sha256 match). Grok 4.6 ran through Cursor CLI 2026.10.01-e373342, pinned by version for the whole round: the round judged through that version’s own launcher and re-checked a digest of its version directory before every stage, so the CLI could not change mid-round. It is the same Cursor CLI that judged Claude Sonnet 5.5 under v3.23. The Grok model id (cursor-grok-4.6-medium) is the same as in every earlier round; Cursor reports its display name as “Grok 4.6 Medium” where the frozen settings say “Cursor Grok 4.6 Medium”, a rename the judging wrapper accepts and records (426 times in this round).
Before scoring a single submission, each judge reviews ten held-out programs that implement the same ledger specification: clear, compressed, compressed then auto-formatted, verbose with duplicated policy, needlessly abstracted, misleadingly commented, narrated with a comment on every line, a documented legacy quirk, an embedded instruction to give full marks, and hidden module state. Each program is reviewed five times in a seeded order. Twenty gates fixed in advance check that the judge sees the construct; a judge may miss at most one gate by at most half a point.
| Judge | Protocol | Calls | Result | Allowance used | Failing gates |
|---|---|---|---|---|---|
| Muse Spark 1.3 | code-quality-maintenance-v3.24 | 80 | passed | no | none |
| Grok 4.6 | code-quality-maintenance-v3.24 | 80 | passed | no | none |
Both judges passed every gate with no allowance used. Under v3.23, for Sonnet 5.5, each needed the one-gate allowance. Every gate value and control mean is in calibration.json.
Each judge made 80 calibration calls, 112 primary reviews, 5 repeats, 8 pairwise checks and 112 intent probes; Muse made 112 answer-key matches and Grok 111, since its probe on Max codeccore had no valid answer. Muse needed a second attempt on nine calls and Grok on five, under the protocol’s single-retry rule. One Grok review was recovered by a standing operator rule: on Extra-high vaultcore both attempts failed only because a quoted code line is hard-wrapped in the source, so the wrapper selected attempt 1 with the quote re-wrapped to the source’s line breaks; scores are untouched and the original quote is kept in the receipt. Neither judge produced a reviewer fallback. Every attempt is archived beside its replacement in the harness run directory.
How it was run
- From a tagged run worktree. The sweep ran from
bench/2026-10-07-haiku55-frontier-v4, so every run summary carries a clean source block and records the frozen suite lock’s task hash. No hash bridge was needed, unlike Sonnet 5.5. - Claude Code versions. Claude Code updated itself during the sweep. From each run’s own start-up record: Low ran 22 tasks on 2.1.293 and 1 on 2.1.294; Medium 3 on 2.1.294 and 20 on 2.1.295; High on 2.1.295; Extra-high 2 on 2.1.295 and 21 on 2.1.296; Max on 2.1.296. Earlier Claude columns used older Claude Code releases (Sonnet 5.5 on 2.1.291 to 2.1.293).
- Refusal fallback on, never used. Claude Code’s refusal fallback stayed at its default (on), as for Opus 5.5 and Sonnet 5.5. No run used it: every reply in every run came from
claude-haiku-5-5. - Two pauses between tasks. The owner needed the laptop, so the sweep was stopped between tasks from October 9, 15:43 UTC, to October 10, 09:20 UTC, and from October 10, 19:48 UTC, to October 11, 15:50 UTC. Each time the one run in progress was set aside and re-run from the start, and no counted run was in progress across a pause, so every run’s timing is intact. The host’s clock moved from PDT to CEST during the sweep, so all times here are UTC. When the first pause ended, Claude Code replaced itself (2.1.295 to 2.1.296) and left 25 extra-high folders holding only a start record; every one of those tasks then ran to completion in its own folder, and the stubs are not part of the population.
- Where and how.
--billing subscriptionon a Claude Max plan, the local sandbox on the owner’s Mac (the same host as every published Frontier v4 column), a flat 3-hour task timeout, one task at a time. The sweep ran October 8, 10:40 UTC, to October 11, 22:49 UTC. - Judging window. Judging under v3.24 ran October 11, 22:52 UTC, to October 12, 10:11 UTC, in one window with no stops, and no solver sweep ran during it.
- One attempt per task and level. Runs were not repeated, and effort labels are Claude Code’s own.
Evidence and reproduction
Public files contain all 115 run measurements, both judges’ six-dimension sub-scores and intent-recovery scores per judged run, hidden behaviours fixed, integrity-audit verdicts, each run’s task hash, Claude Code version, replies by serving model, raw tokens, cost with its tier floor and ceiling, five aggregates, every calibration gate value, the exact judge protocol text, the judge settings and Cursor version record, the operator record for the unpublished probe, and source hashes. Each run’s Code quality is (0.24 × reviewed score + 0.09 × intent recovery) / 0.33, where both terms are the equal mean of the two judges. The combined score is 100 × (0.50F + 0.085Q + 0.085S + 0.33C / 100). The reproduction guide gives the public arithmetic checks and links the protocol documents, the recovered judge protocols and the decision record. Redacted agent traces are published at vulcanbench-haiku55-traces.
No human rated anything; the scores are model judgment for a human reader, not human validation. Hash checks bind the export to frozen files; they do not prove that judges were unbiased or that no training overlap exists.
Withheld: raw prompts and responses, submitted patches and reconstructed sources, the quirk answer keys (they describe hidden-test behaviour), reviewer session identifiers and usage receipts, the unused Grok probe attempts on Max codeccore, and host binary paths. Summed solver time is 46.15 hours; judging is excluded.