The public suites measure models on public code. The eval suite builder measures them on yours. It takes the pull requests your team already merged and turns them into tasks with hidden tests, so the question “which model, at which effort, for our codebase” gets the same answer the public reports give, on your own work.
Pick merged pull requests from a GitHub repository you own. Private repositories work too.
Each pull request becomes a task: the repository as it was before the change, an issue describing the problem, and hidden tests that fail before the change and pass after it. The model must fix the issue without seeing the original change.
Review each task, accept the good ones and drop the rest. Then freeze the suite, so every later run measures the same tasks and results stay comparable.
Run models and effort levels on your frozen suite from the Launch page. Every run records pass or fail, time, tokens and cost, the way the public reports do.
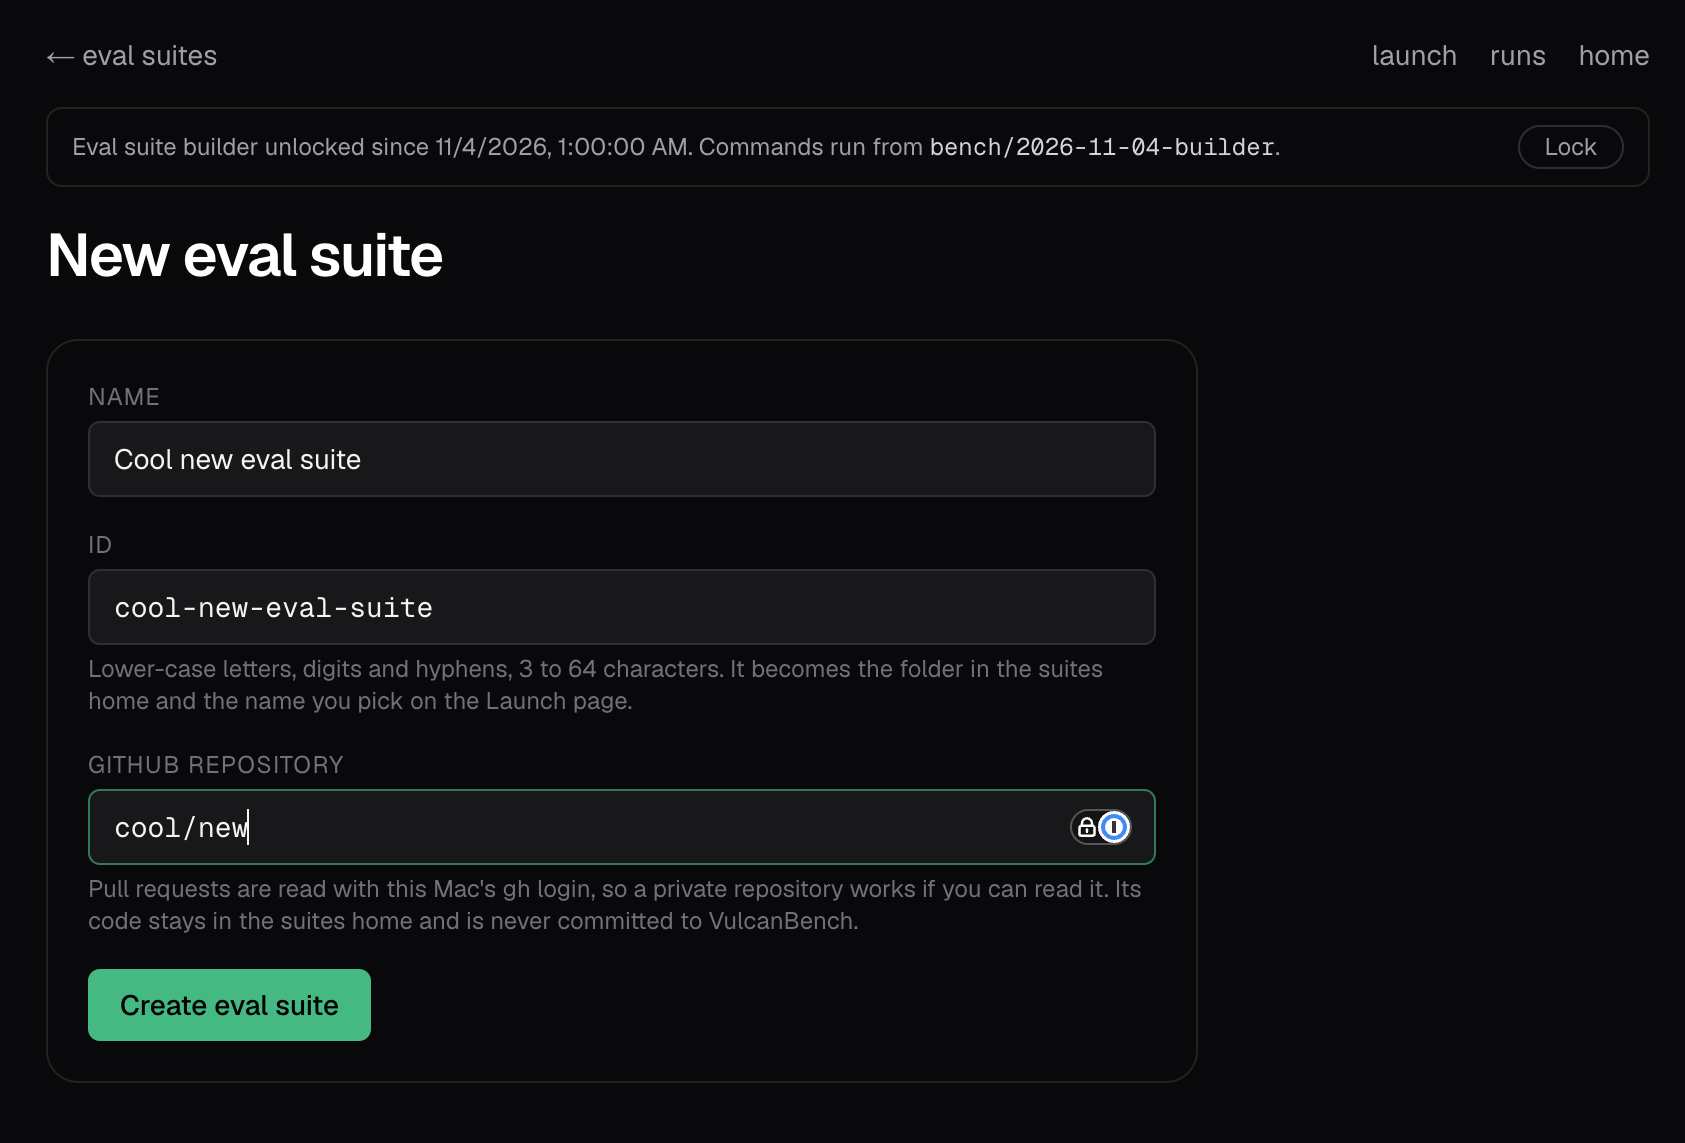
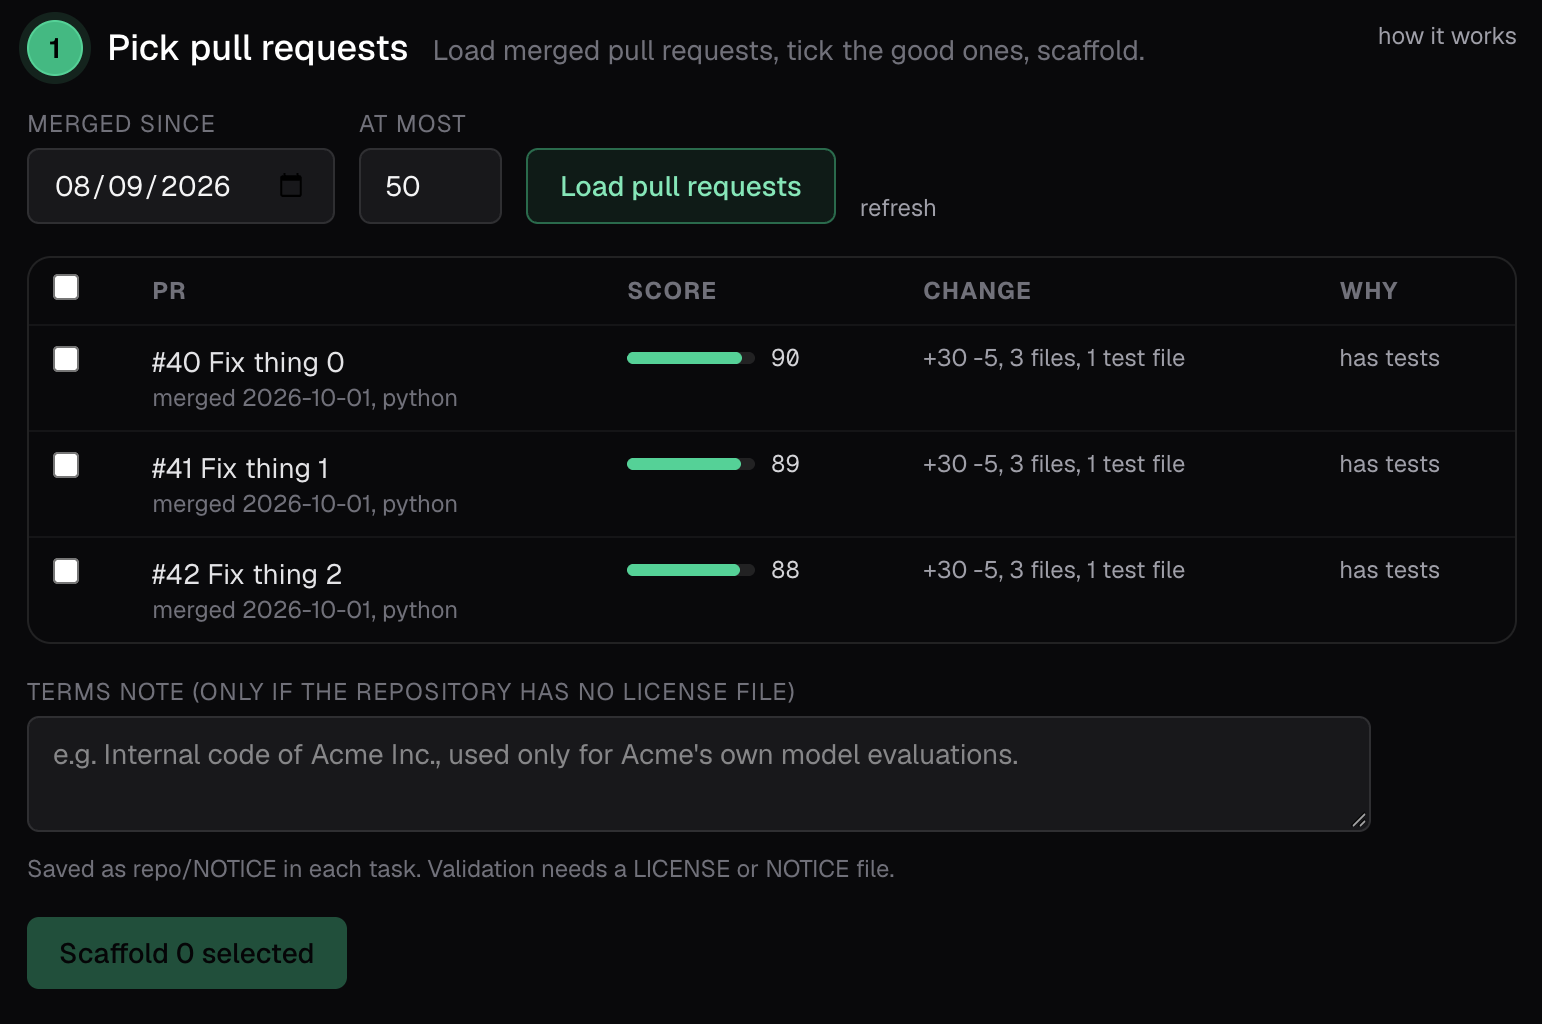
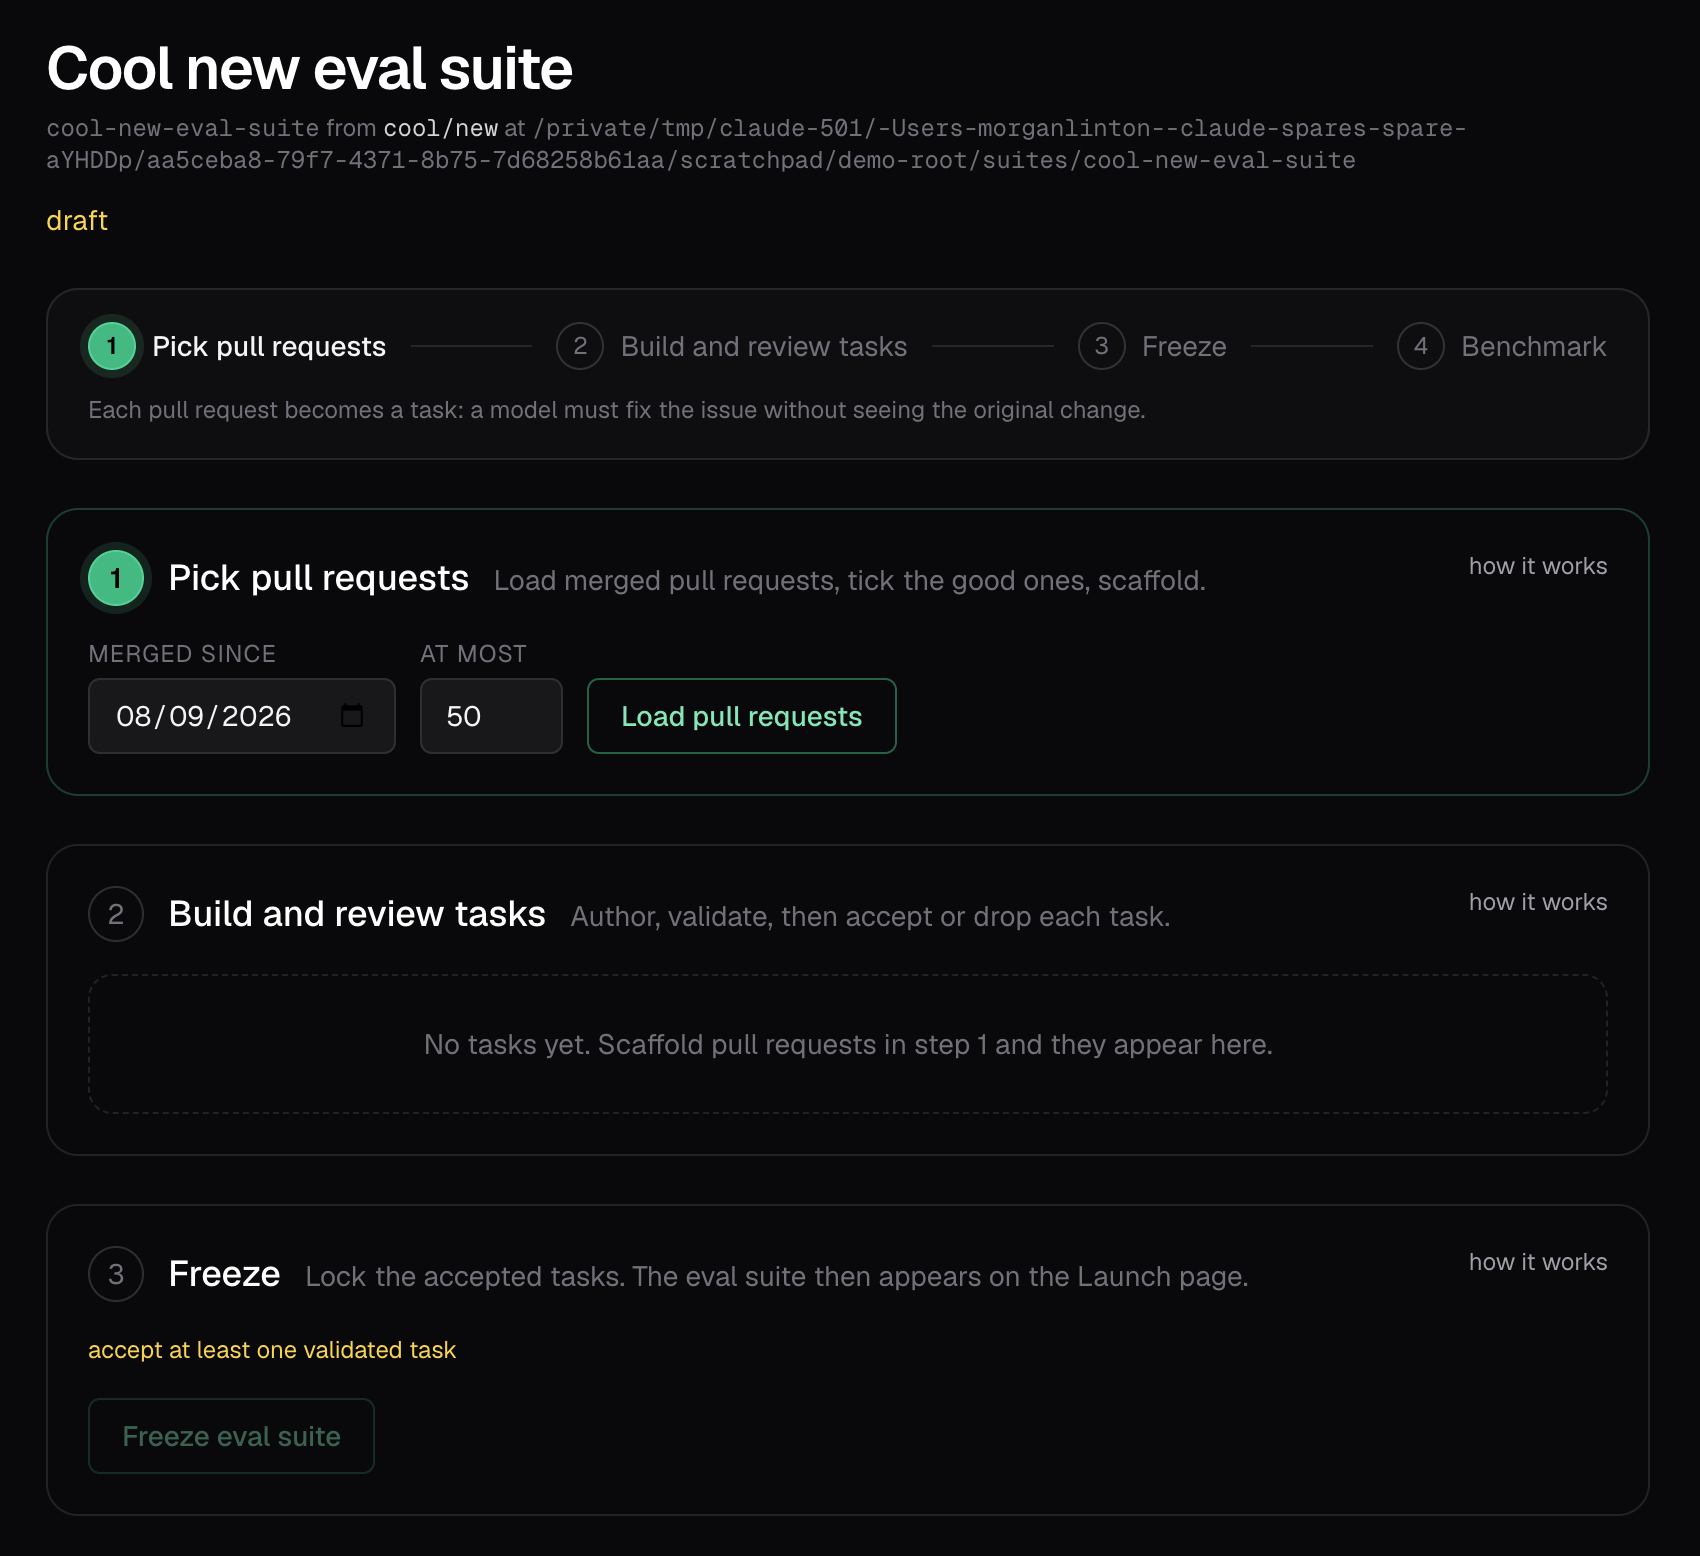
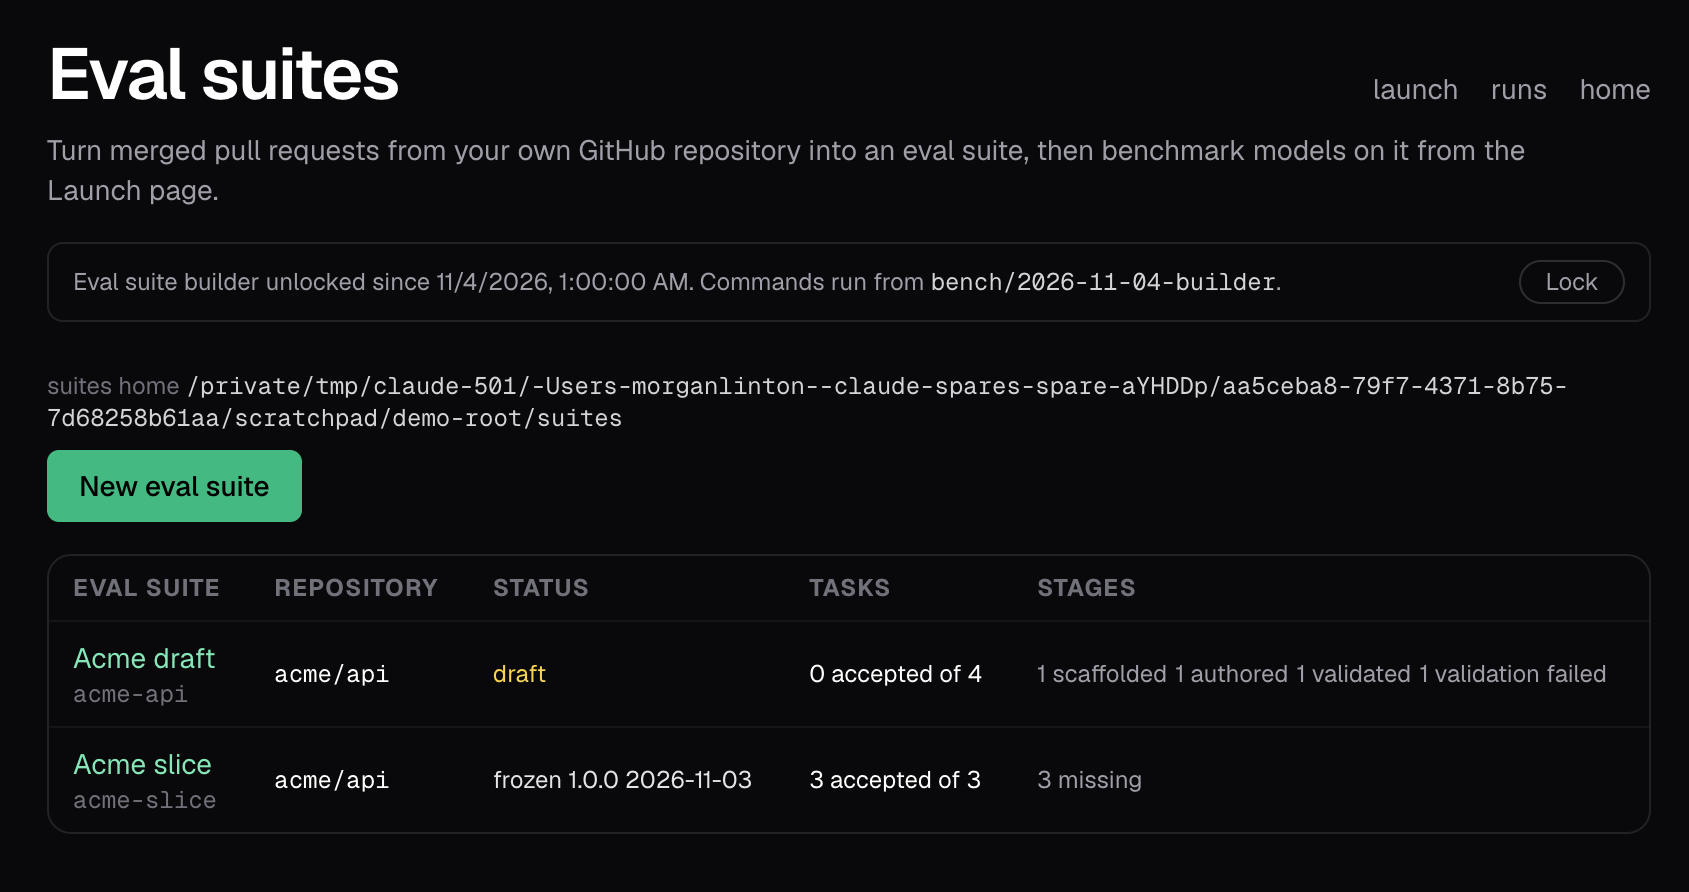
Screenshots of the current build, running against a demo repository. Details will change before it opens.
Your repository, your tasks and your results stay private. Nothing from your suite is published, reused in another suite, or shown on the leaderboard.
The public suites (VulcanBench Frontier v4, Routine v1 and Safety v1) stay free and open. Building a model rather than choosing between them? See benchmark your model.