October 30, 2026 · Morgan Linton · 115 runs · Code quality protocol v3.29
GPT-6.1 Terra across every effort level
115 runs of OpenAI’s GPT-6.1 Terra (gpt-6.1-terra) through the Codex CLI on a ChatGPT subscription, 23 tasks at each of five effort levels, Low to Max, the day after the model’s release. GPT-6.1 Terra is a new model, the second Terra on the board after GPT-5.6 Terra. Code quality carries 33% of the combined score and is judged for a human reader by Muse Spark 1.3 and Grok 4.6, the panel that judged Claude Opus 5.5, GPT-6.1 Sol and GPT-6 Astra, so GPT-6.1 Terra takes its place on the Frontier v4 leaderboard beside them. Every run finished inside the 3-hour task bound, and every cell is judged on all 23 runs, one of them through an escape-spelling recovery described under the results table.
How the test works
A retired program to rebuild
Each of the 23 tasks is a legacy binary with a written specification and an issue. Its real behaviour departs from the specification in documented ways, and hidden tests check the rewrite against the binary.
One attempt per task and level
GPT-6.1 Terra works in Codex with the binary, the specification and the code, once per task at each effort level, inside a flat 3-hour bound, one task at a time.
Tests and two judges score it
Hidden tests give functional correctness. Two calibrated judges from labs other than OpenAI rate the code for a human reader and try to recover the documented departures.
Scores, time and cost per level
Each level gets a combined score, tasks passed, minutes and API-equivalent cost at OpenAI’s list price.
Combined score = 50% functional correctness + 8.5% lint and complexity + 8.5% security + 33% Code quality, averaged over the 23 runs in each level, as on every other board column. Frontier Code quality is the reviewed layer plus intent recovery; it is never compared with Routine v1 Code quality.
Across every effort level
GPT-6.1 Terra ran every task once at each of the five effort levels Codex offers for it (Extra-high is Codex’s xhigh), 23 tasks per cell, through Codex CLI 0.159.0 on a ChatGPT subscription on October 27, 2026, from 15:14 to 23:16 UTC, the day after OpenAI released it, on the owner’s Mac, one task at a time. Combined score weights are 50% functional correctness, 8.5% lint and complexity, 8.5% security and 33% Code quality, judged for a named human reader by Muse Spark 1.3 and Grok 4.6 with a ground-truth intent-recovery probe. No run reached the flat 3-hour task bound; the longest, Extra-high paddockcore, took 19.5 minutes. All 115 runs carry a published Code quality score.
Combined score
74.95 at Low to 90.00 at Max
The score climbs with effort, unevenly: 74.95 at Low, 80.10 at Medium, 79.19 at High, 83.68 at Extra-high and 90.00 at Max. The step from Extra-high to Max, 6.32 points, is the largest, and Max is the only level with a standard error under 2 points (0.39).
Tasks passed
13, 12, 15, 16 and 23 of 23
GPT-6.1 Terra fully solves 12 to 16 tasks from Low to Extra-high and every task at Max. Of the 231 hidden behaviours the tasks test for, it fixes 170, 188, 176, 205 and 231. Six tasks fail at every level from Low to Extra-high and pass only at Max.
Code quality
66.55 to 76.59
The judges rate the code 66.55 at Low, 67.29 at Medium, 69.96 at High, 70.94 at Extra-high and 76.59 at Max, rising with effort, with standard errors of 1.07 to 1.35.
Runtime and cost
2.8 to 6.9 min · $0.11 to $0.36 per task
Max takes about two and a half times as long as Low and costs about three times as much. The whole sweep took 8.0 hours of solver time and prices at $22.49 for 115 runs, $0.20 per task, at GPT-6.1 Terra’s list rates.
| Metric | Low | Medium | High | Extra-high | Max |
|---|---|---|---|---|---|
| Combined score | 74.95 | 80.10 | 79.19 | 83.68 | 90.00 |
| Standard error | 3.90 | 2.61 | 3.38 | 2.09 | 0.39 |
| Judged runs | 23 | 23 | 23 | 23 | 23 |
| Tasks passed | 13/23 | 12/23 | 15/23 | 16/23 | 23/23 |
| Hidden behaviours fixed | 170/231 | 188/231 | 176/231 | 205/231 | 231/231 |
| Code quality | 66.55 | 67.29 | 69.96 | 70.94 | 76.59 |
| Human readability | 57.2 | 57.9 | 61.2 | 63.1 | 70.4 |
| Minutes per task | 2.8 | 3.1 | 3.2 | 4.9 | 6.9 |
| API-equivalent $ per task | $0.11 | $0.14 | $0.13 | $0.24 | $0.36 |
Under the prior 50/15/15/20 profile applied to the same Code quality scores the ladder has the same shape, 78.26 to 91.30. The card and the full per-effort table follow.
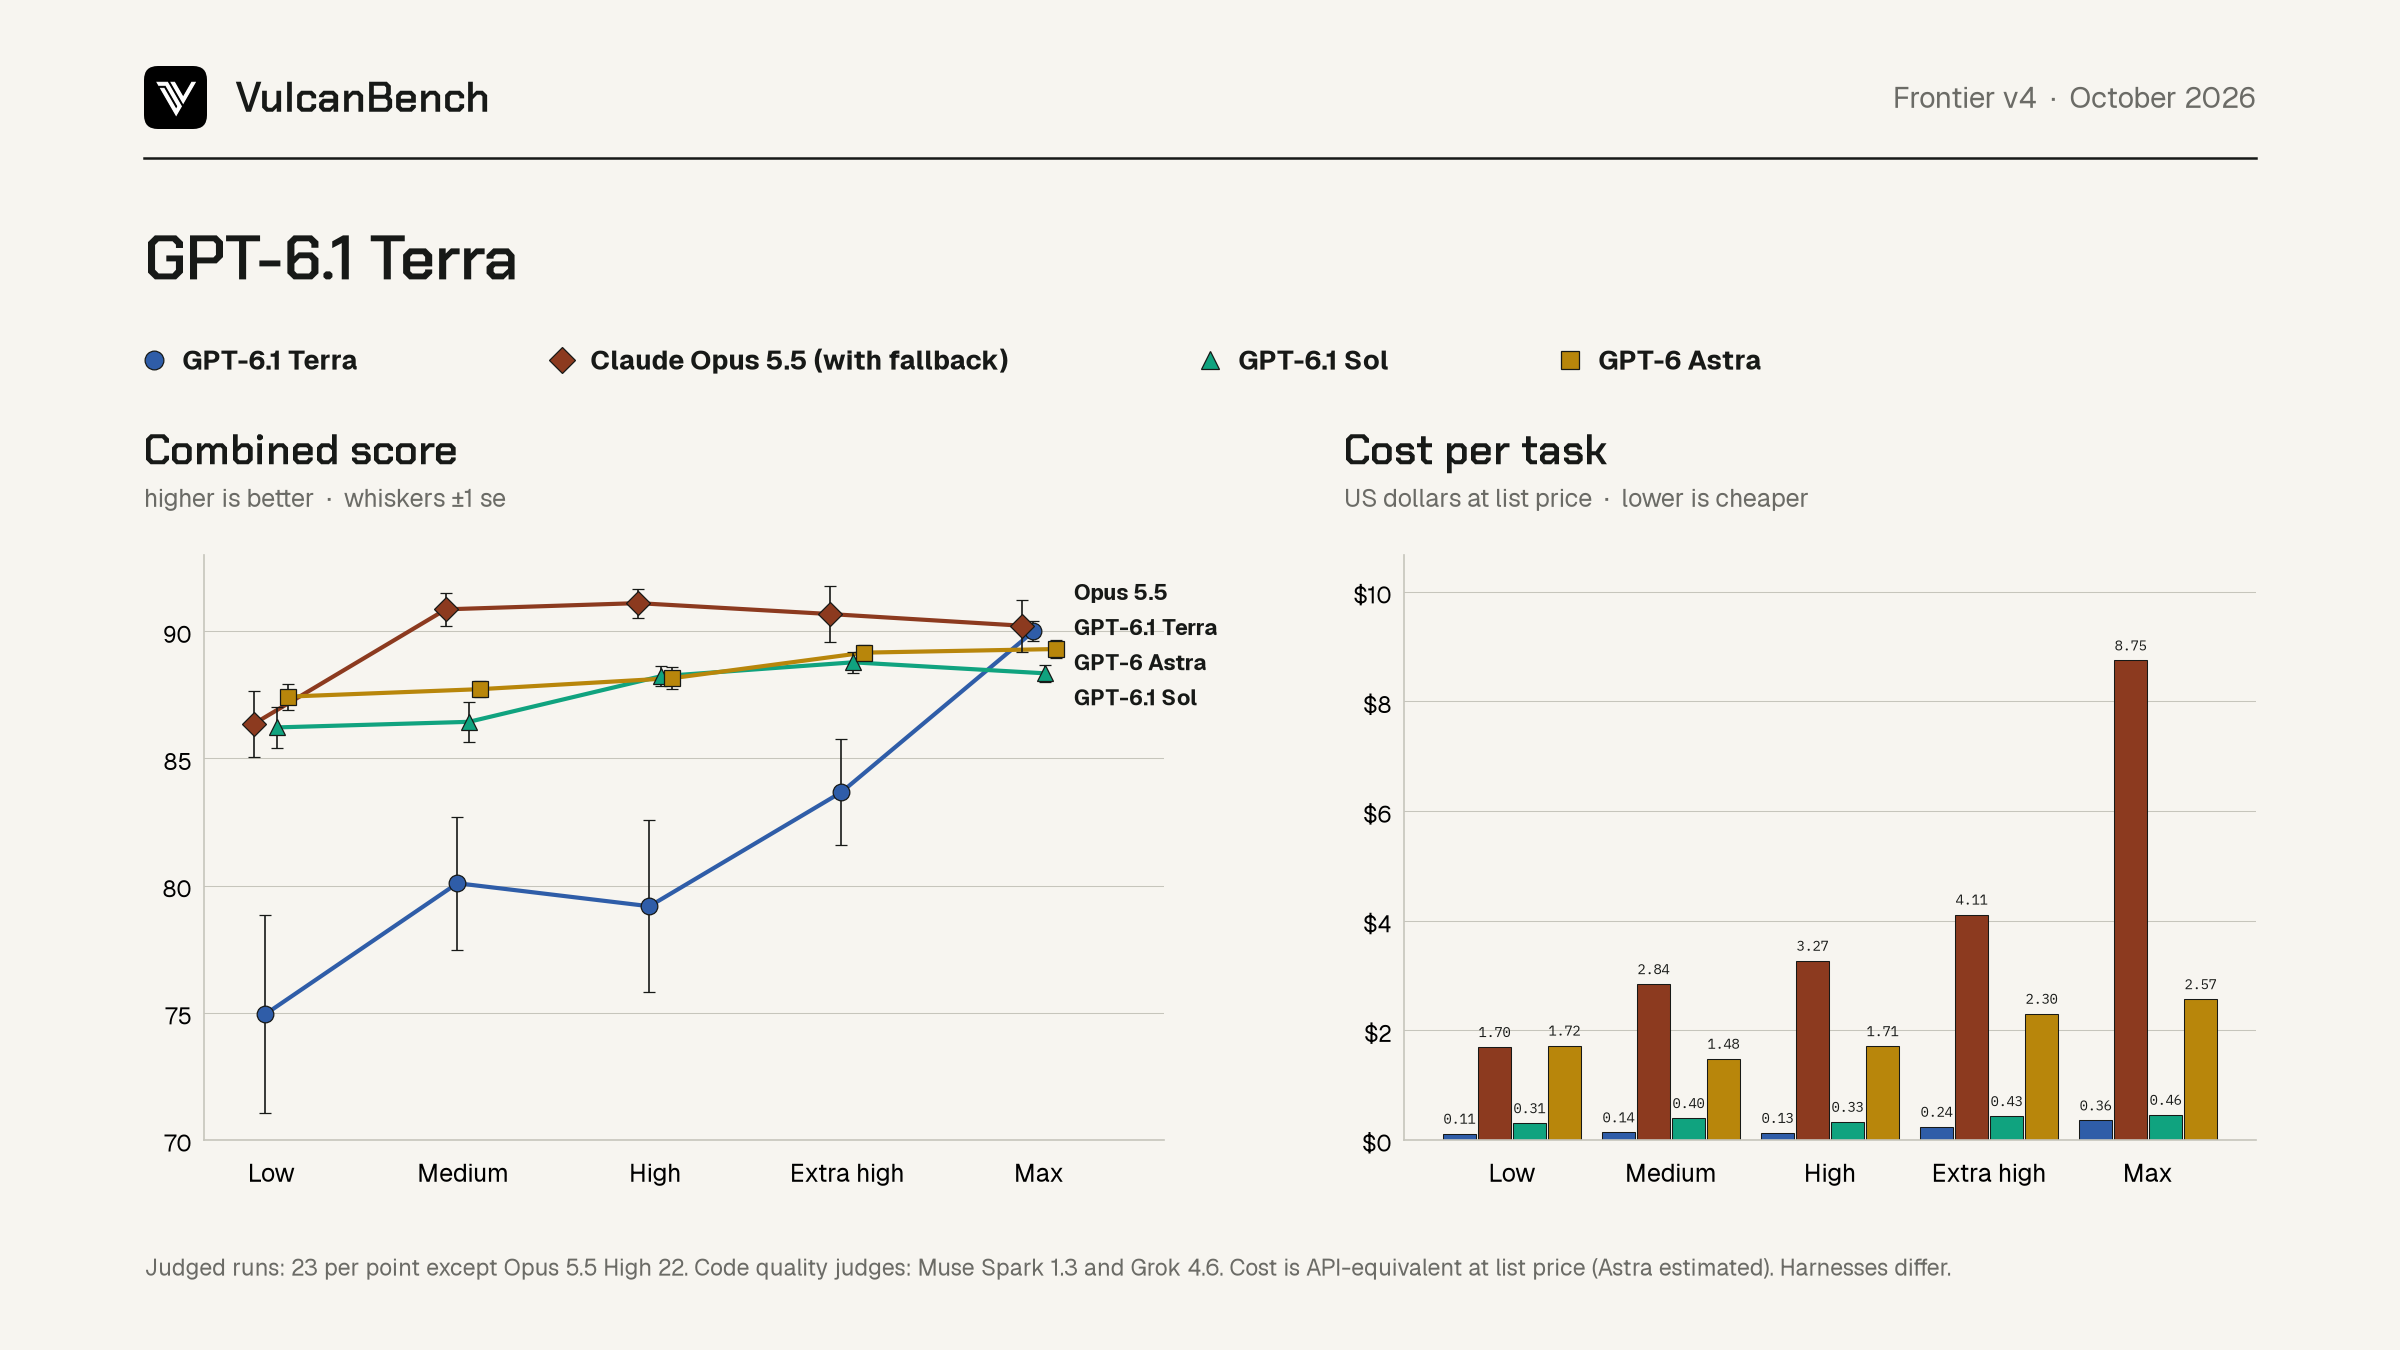
GPT-6.1 Terra is a model to run at Max. There it scores 90.00, between Claude Opus 5.5 (90.22) and GPT-6 Astra (89.30), passes every hidden test on every task, and costs $0.36 a task. Below Max it is about 5 to 12 points behind the other three columns, because it fully solves only 12 to 16 tasks where they solve 17 to 23. These runs compare a model-and-harness combination, not an isolated base model; the Frontier v4 leaderboard places every GPT-6.1 Terra level beside the other models judged under the same protocol.
Combined score and Code quality by effort
n=23 at every level. Combined (33%) is the published score. Combined (20% profile) applies the prior 50/15/15/20 weights to the same Code quality scores for comparison. Code quality, human readability, maintainability and intent recovery are out of 100 and equal means of the two judges. Passed counts all 23 runs. Runtime is solver wall-clock per task over every run in the cell.
| Model / harness | Effort | Combined (33%) | SE | Combined (20% profile) | Code quality | Human readability | Maintainability | Intent recovery | Judged | Passed | Min/task |
|---|---|---|---|---|---|---|---|---|---|---|---|
| GPT-6.1 Terra / Codex | Low | 74.95 | 3.90 | 78.26 | 66.55 | 57.2 | 68.0 | 77.8 | 23/23 | 13/23 | 2.8 |
| GPT-6.1 Terra / Codex | Medium | 80.10 | 2.61 | 83.29 | 67.29 | 57.9 | 69.2 | 77.5 | 23/23 | 12/23 | 3.1 |
| GPT-6.1 Terra / Codex | High | 79.19 | 3.38 | 82.04 | 69.96 | 61.2 | 71.0 | 80.2 | 23/23 | 15/23 | 3.2 |
| GPT-6.1 Terra / Codex | Extra-high | 83.68 | 2.09 | 85.94 | 70.94 | 63.1 | 73.1 | 78.5 | 23/23 | 16/23 | 4.9 |
| GPT-6.1 Terra / Codex | Max | 90.00 | 0.39 | 91.30 | 76.59 | 70.4 | 78.9 | 81.8 | 23/23 | 23/23 | 6.9 |
Max settlecore is published through a recovery. Muse Spark 1.3’s intent probe of Max settlecore quoted a byte-string line from the code with its escapes decoded into control characters, on both of its two attempts, so the quote no longer matched the code. That is the JSON-escaping slip the operator rule recover_escaped_excerpts was written for under v3.18, for Muse’s probe of GPT-6.1 Sol at High codeccore: the rule writes such characters back as the source spells them, after which the excerpt must be verbatim and the attempt must pass every other check. The rule spelled a decoded NUL byte only as \0, and this source writes \x00, so the probe was first marked invalid and the first summary published 114 of the 115 runs, with Max on 22. The owner chose on October 29 to recover it under the rule. The rule now tries both spellings (harness PR #239), the invalid marker is kept beside the recovered call, the one missing answer-key match was made on October 30, and the summary was rebuilt. Max moved from 89.95 on 22 runs to 90.00 on 23; settlecore scores 91.11, with Code quality 80.30. No other call changed.
Four factors by effort. Functional correctness averages 74.67, 84.54, 80.96, 90.48 and 100.00 from Low to Max; lint and complexity 84.12, 84.19, 84.25, 83.28 and 84.93; security 100.00, 99.57, 99.57, 93.48 and 88.26. Security is the one factor that falls with effort: the scan flags more of the Extra-high and Max submissions, which costs Max about 1 point of combined score against a clean scan. Only the Code quality factor depends on the judges.
Intent recovery is scored over the specification departures a submission actually passed tests for. Three runs (Low granarycore and paddockcore, Medium granarycore) passed none, so their 9 intent points move to the reviewed score, as the protocol pre-registers. SE is one sample standard error of the combined score across the cell’s tasks. It describes task sampling, not judge uncertainty, repeated runs or a significance test. No solver fallback occurred, and neither judge produced a reviewer fallback on any of the 115 submissions.
Beside Claude Opus 5.5, GPT-6.1 Sol and GPT-6 Astra
At Max GPT-6.1 Terra catches the three frontier columns: 90.00, against 90.22 for Claude Opus 5.5, 89.30 for GPT-6 Astra and 88.35 for GPT-6.1 Sol. It passes all 23 tasks there, as GPT-6.1 Sol and GPT-6 Astra do and Opus 5.5 (21) does not, and its Code quality at Max, 76.59, is above GPT-6 Astra’s 76.26 and GPT-6.1 Sol’s 73.80 and below Opus 5.5’s 79.77. Below Max it is well behind: 74.95 to 83.68 from Low to Extra-high, against 86.22 or more for every other column at every level.
It is the cheapest and the fastest of the four at every level. At Max it costs $0.36 a task, against $0.46 for GPT-6.1 Sol, $2.57 for GPT-6 Astra and $8.75 for Opus 5.5, and takes 6.9 minutes, against 10.3, 14.5 and 37.5. At Extra-high and Max it uses more tokens than GPT-6.1 Sol and GPT-6 Astra (2.15M and 2.38M a task, against about 1M), but its list price is half of GPT-6.1 Sol’s, so it still costs less.
| Model / harness | Effort | Combined | SE | Judged | Passed | Min/task | Tokens/task | $/task | Code quality |
|---|---|---|---|---|---|---|---|---|---|
| GPT-6.1 Terra / Codex | Low | 74.95 | 3.90 | 23 | 13/23 | 2.8 | 0.77M | $0.11 | 66.55 |
| Claude Opus 5.5 / Claude Code | Low | 86.36 | 1.30 | 23 | 17/23 | 13.7 | 2.77M | $1.70 | 72.53 |
| GPT-6.1 Sol / Codex | Low | 86.22 | 0.82 | 23 | 20/23 | 6.9 | 1.24M | $0.31 | 70.79 |
| GPT-6 Astra / Codex | Low | 87.43 | 0.51 | 23 | 22/23 | 4.2 | 0.89M | $1.72 | 70.31 |
| GPT-6.1 Terra / Codex | Medium | 80.10 | 2.61 | 23 | 12/23 | 3.1 | 0.98M | $0.14 | 67.29 |
| Claude Opus 5.5 / Claude Code | Medium | 90.86 | 0.64 | 23 | 23/23 | 18.6 | 5.01M | $2.84 | 77.32 |
| GPT-6.1 Sol / Codex | Medium | 86.44 | 0.78 | 23 | 22/23 | 10.6 | 1.62M | $0.40 | 70.25 |
| GPT-6 Astra / Codex | Medium | 87.73 | 0.32 | 23 | 23/23 | 3.8 | 0.68M | $1.48 | 71.19 |
| GPT-6.1 Terra / Codex | High | 79.19 | 3.38 | 23 | 15/23 | 3.2 | 0.90M | $0.13 | 69.96 |
| Claude Opus 5.5 / Claude Code | High | 91.11 | 0.57 | 22* | 22/23 | 21.4 | 4.11M | $3.27 | 77.99 |
| GPT-6.1 Sol / Codex | High | 88.23 | 0.40 | 23 | 23/23 | 10.2 | 0.91M | $0.33 | 73.67 |
| GPT-6 Astra / Codex | High | 88.16 | 0.42 | 23 | 23/23 | 4.9 | 0.77M | $1.71 | 73.48 |
| GPT-6.1 Terra / Codex | Extra-high | 83.68 | 2.09 | 23 | 16/23 | 4.9 | 2.15M | $0.24 | 70.94 |
| Claude Opus 5.5 / Claude Code | Extra-high | 90.68 | 1.10 | 23 | 22/23 | 20.7 | 3.90M | $4.11 | 79.98 |
| GPT-6.1 Sol / Codex | Extra-high | 88.78 | 0.40 | 23 | 23/23 | 15.4 | 1.12M | $0.43 | 74.99 |
| GPT-6 Astra / Codex | Extra-high | 89.16 | 0.30 | 23 | 23/23 | 8.1 | 0.93M | $2.30 | 75.47 |
| GPT-6.1 Terra / Codex | Max | 90.00 | 0.39 | 23 | 23/23 | 6.9 | 2.38M | $0.36 | 76.59 |
| Claude Opus 5.5 / Claude Code | Max | 90.22 | 1.02 | 23 | 21/23 | 37.5 | 8.72M | $8.75 | 79.77 |
| GPT-6.1 Sol / Codex | Max | 88.35 | 0.33 | 23 | 23/23 | 14.5 | 1.04M | $0.46 | 73.80 |
| GPT-6 Astra / Codex | Max | 89.30 | 0.37 | 23 | 23/23 | 10.3 | 0.95M | $2.57 | 76.26 |
Read the comparison with its limits. * Opus 5.5 at High is judged on 22 runs, where a safeguard stop left one run with no code to review. All four columns are judged by Muse Spark 1.3 and Grok 4.6 under the same rubric, each in its own protocol run (v3.29, v3.15, v3.18 and v3.4). Harnesses differ: Claude Code for Opus 5.5, Codex for the other three, with GPT-6.1 Terra on the same Codex version as GPT-6.1 Sol. $/task is API-equivalent at list price from each run’s receipts: Opus 5.5 with Claude Code’s refusal fallback turns included, GPT-6 Astra at its report’s central estimate. Their figures are the published rows of their own reports.
Against GPT-5.6 Terra
GPT-5.6 Terra ran the same 23 tasks through Codex in September and was judged by the same two judges under v3.6. GPT-6.1 Terra scores higher at every level, by 15.25 points at Low, 13.75 at Medium, 2.51 at High, 0.22 at Extra-high and 0.95 at Max, and passes more tasks below Max (13, 12, 15 and 16 against 2, 5, 11 and 14); both pass all 23 at Max. It is also cheaper and faster at every level: $0.11 to $0.36 a task against $0.58 to $2.12, and 2.8 to 6.9 minutes against 6.7 to 19.7, using 0.77M to 2.38M tokens a task against 1.21M to 5.86M. Its list price is lower too: $1.00 input and $5.00 output per million tokens, against $2.00 and $12.00. Code quality is the exception: GPT-6.1 Terra’s is 2.19 to 5.76 points lower from Low to Extra-high and 4.07 points higher at Max.
| Metric | Low | Medium | High | Extra-high | Max |
|---|---|---|---|---|---|
| Combined, GPT-6.1 Terra | 74.95 | 80.10 | 79.19 | 83.68 | 90.00 |
| Combined, GPT-5.6 Terra | 59.70 | 66.35 | 76.68 | 83.46 | 89.05 |
| Tasks passed, GPT-6.1 Terra | 13/23 | 12/23 | 15/23 | 16/23 | 23/23 |
| Tasks passed, GPT-5.6 Terra | 2/23 | 5/23 | 11/23 | 14/23 | 23/23 |
| Code quality, GPT-6.1 Terra | 66.55 | 67.29 | 69.96 | 70.94 | 76.59 |
| Code quality, GPT-5.6 Terra | 72.31 | 70.93 | 73.90 | 73.13 | 72.52 |
| $ per task, GPT-6.1 Terra | $0.11 | $0.14 | $0.13 | $0.24 | $0.36 |
| $ per task, GPT-5.6 Terra | $0.58 | $0.69 | $1.18 | $2.12 | $1.88 |
| Minutes per task, GPT-6.1 Terra | 2.8 | 3.1 | 3.2 | 4.9 | 6.9 |
| Minutes per task, GPT-5.6 Terra | 6.7 | 7.9 | 12.6 | 19.2 | 19.7 |
The two sweeps ran on different Codex CLI versions and a month apart, so read the speed figures with that in mind. GPT-5.6 Terra’s report has its full record.
Cost and tokens across effort levels
All 115 runs priced from their Codex receipts at list API rates, cache-aware, with judging excluded. These are API-equivalent estimates, not subscription charges: GPT-6.1 Terra ran on a ChatGPT subscription, and what the plan bills is not observable from the receipts. Cost per task is $0.11 at Low, $0.14 at Medium, $0.13 at High, $0.24 at Extra-high and $0.36 at Max; the whole sweep comes to $22.49. Max’s step in score comes with a step in reasoning: its median run spends 14.5K output tokens on reasoning, against 0.6K to 1.7K at the lower levels, and its mean output is 28.8K tokens a task against 12.9K at Extra-high.
| Effort | Runs | $/task | Level total | Tokens/task | Output/task | Median reasoning | Cached share of input | Min/task | Median min |
|---|---|---|---|---|---|---|---|---|---|
| Low | 23 | $0.11 | $2.62 | 0.77M | 5.5K | 0.6K | 92.6% | 2.8 | 2.3 |
| Medium | 23 | $0.14 | $3.19 | 0.98M | 7.9K | 1.2K | 93.5% | 3.1 | 2.7 |
| High | 23 | $0.13 | $2.95 | 0.90M | 7.2K | 1.2K | 93.8% | 3.2 | 2.5 |
| Extra-high | 23 | $0.24 | $5.53 | 2.15M | 12.9K | 1.7K | 94.9% | 4.9 | 3.8 |
| Max | 23 | $0.36 | $8.20 | 2.38M | 28.8K | 14.5K | 94.8% | 6.9 | 6.1 |
| Full sweep | 115 | $0.20 | $22.49 | 165M | 8.0 h |
Pricing. Rates checked 2026-10-26 from OpenAI: GPT-6.1 Terra at $1.00 input, $0.05 cached input and $5.00 output per million tokens. Codex receipts report input, cached input, output and reasoning tokens per run, so cached input is billed at the cache-read rate and the rest at the standard rate; reasoning tokens are part of output and are not billed twice. Codex keeps each request within its context window, so no long-context premium is modelled. The sweep stamped each run at these rates at run time; the export recomputed every run from its receipt and matched every stamp.
Tokens are Codex’s raw totals, input (cached included) plus output; the full sweep row sums them over all 115 runs (Tokens/task in that row is the sweep total). Per-run estimates, token usage breakdowns and the rate table are in economics.json and runs.csv.
On the Frontier v4 board
GPT-6.1 Terra’s best level, Max at 90.00 ± 0.39 (n=23), ranks 16th of the board’s 80 model and effort columns, just below Claude Fable 5.1 at High (90.07) and just above Grok 4.7 at Low (89.42) and GPT-6 Astra at Max (89.30). By level it ranks Low 62nd, Medium 56th, High 57th, Extra-high 49th, Max 16th. Of the 17 priced columns scoring 89 or more, GPT-6.1 Terra at Max is the cheapest, at $0.36 a task against $0.84 to $14.49 for the rest. Max carries the best tag, and the board’s critical, routine and rough effort suggestions all pick Max, because no other level is within 5 points of it. The leaderboard carries every column; GPT-6.1 Terra’s Extra-high and Max cells carry the ** footnote with the disclosures on this page.
Read these placements with the panel in mind. GPT-6.1 Terra, Claude Opus 5.5, GPT-6.1 Sol, GPT-6 Astra and most other columns are judged by Muse Spark 1.3 and Grok 4.6; Grok 4.7’s, DeepSeek V4.1 Flash’s and Reflection Beam’s by Muse Spark 1.3 and GPT-6.1 Sol; Muse Wonder Full’s by Claude Opus 5.5 and GPT-6.1 Sol. Scores from different panels are not calibrated against each other, so gaps of a point or two between columns judged by different panels are not a reliable order.
What Code quality measures
Every judge receives the same rubric, frozen by hash before any review. It names the reader it scores for: an engineer who has never seen the code, reads it top to bottom without running it, and must make a correct change in one sitting. It tells the judge that its own ease at parsing dense code is not evidence of readability. Six dimensions are scored 0 to 4 in half steps against written anchors: naming, presentation and intent form the human readability sub-score; structure, changeability and verifiability form the maintainability sub-score. Every score must cite an exact excerpt from the code and a concrete consequence for that reader. The host computes the sub-scores; the judge does no arithmetic.
The 33 points have three designed layers. The reviewed panel carries 24 points. An intent-recovery probe carries 9: the judge, given only the specification and the code, lists where the code departs from the specification, and a separate call matches that list against a frozen answer key, over the departures the submission passed tests for. The third layer, measured maintenance, is designed for 12 points but is not yet built, so the pre-registered 24 plus 9 split is in force. Frontier Code quality is therefore the reviewed layer plus intent recovery, and it is never compared with Routine v1 Code quality, which is scored on a different suite and population.
| Component | Low | Medium | High | Extra-high | Max |
|---|---|---|---|---|---|
| Code quality | 66.55 | 67.29 | 69.96 | 70.94 | 76.59 |
| Human readability | 57.2 | 57.9 | 61.2 | 63.1 | 70.4 |
| Maintainability | 68.0 | 69.2 | 71.0 | 73.1 | 78.9 |
| Intent recovery | 77.8 | 77.5 | 80.2 | 78.5 | 81.8 |
| Runs with no intent denominator | 2 | 1 | 0 | 0 | 0 |
| Rated by Muse Spark 1.3 | 61.7 | 62.0 | 65.2 | 66.7 | 73.0 |
| Rated by Grok 4.6 | 63.6 | 65.1 | 67.0 | 69.6 | 76.3 |
| Standard error of Code quality | 1.29 | 1.20 | 1.07 | 1.35 | 1.19 |
Code quality rises with effort, and the step to Max, 5.65 points, is the largest. Human readability is the weaker sub-score at every level, 57.2 to 70.4 against 68.0 to 78.9 for maintainability. Grok 4.6 is the higher rater at every level, by 1.8 to 3.3 points on the reviewed score. Per-run sub-scores from each judge are in runs.csv; the exact rubric, system text, probe and match instructions are in judge-protocols.json.
Judges and calibration
The scored panel is Muse Spark 1.3 (Meta) through the Muse CLI on its Standard tier, and Grok 4.6 (xAI) through the Cursor CLI at medium effort, with equal weight, the same settings and pinned Muse binary as under v3.24. Grok 4.6 ran through the Cursor CLI pinned to version 2026.10.01-e373342, the build v3.23 and v3.24 used, with a digest of its version directory checked before every stage; Cursor had since updated itself to a newer build. Neither lab is OpenAI. Every session is fresh, tools are disabled, the workspace is empty, model identity is checked per call from the CLI’s own records, and solver labels are withheld. Protocol v3.29 changes nothing in the rubric, controls, quirk keys, gates, repeats, seed, weights or judges from v3.24; it applies the protocol to this population.
Before scoring a single submission, each judge reviews ten held-out programs that implement the same ledger specification: clear, compressed, compressed then auto-formatted, verbose with duplicated policy, needlessly abstracted, misleadingly commented, narrated with a comment on every line, a documented legacy quirk, an embedded instruction to give full marks, and hidden module state. Each program is reviewed five times in a seeded order. Twenty gates fixed in advance check that the judge sees the construct; a judge may miss at most one gate by at most half a point. Both judges retook the exam under v3.29 before any counted call.
| Judge | Protocol | Calls | Result | Allowance used | Failing gates |
|---|---|---|---|---|---|
| Muse Spark 1.3 | code-quality-maintenance-v3.29 | 80 | passed | yes | g11 repeatability |
| Grok 4.6 | code-quality-maintenance-v3.29 | 80 | passed | no | none |
Muse Spark 1.3 passed with the one-gate allowance: its repeatability gate (g11) fell 0.26 short, within the half point the protocol allows for one gate, as under v3.23. Grok 4.6 passed every gate. Every gate value and control mean is in calibration.json.
The judges agree closely. Scored by one judge alone, the combined score would be (Muse or Grok) 74.61 or 75.29 at Low; 79.67 or 80.52 at Medium; 78.92 or 79.46 at High; 83.19 or 84.16 at Extra-high; 89.39 or 90.60 at Max. Either way the ladder has the same shape. Each run’s single-judge figures are in runs.csv.
Under v3.29 each judge made 440 counted calls: 80 in calibration, 115 primary reviews, 5 repeats, 10 pairwise checks, 115 intent probes and 115 answer-key matches. Muse needed a second attempt on 12 calls (eight unsupported excerpts, two JSON syntax errors, two answer-key matching errors) and Grok on 4 (three unsupported excerpts, one matching error), under the protocol’s single-retry rule. Muse’s probe of Max settlecore is published through the recovery described under the results table. Every Grok call reported the display label “Grok 4.6 Medium” for the pinned model id, where the frozen settings say “Cursor Grok 4.6 Medium”; the operator wrapper accepts the rename and records it on all 440 selected Grok calls. Neither judge produced a reviewer fallback. Judging ran on October 28, 2026, from 13:57 to 23:26 UTC, and the recovery’s one match call on October 30 at 22:58 UTC. Every operator record is in judge-protocols.json.
How it was run
- The model. GPT-6.1 Terra through the Codex CLI as
gpt-6.1-terra, released by OpenAI on October 26, 2026. Codex does not report the serving model, so model identity is the model requested. - Codex CLI 0.159.0. Pinned by version from its own install, the version GPT-6.1 Sol ran on, signed in with a ChatGPT subscription, in
codex execwith Codex’sworkspace-writesandbox, network access off, user configuration ignored and no saved session. - Five levels. Codex takes low, medium, high, xhigh and max for GPT-6.1 Terra; the board’s Extra-high is xhigh.
- A model metadata notice. In three Extra-high runs (hedgecore, pacecore and tallycore, run back to back), Codex printed its notice that it had no model metadata for
gpt-6.1-terraand used fallback metadata. All three passed every hidden test, and they stay in the population; no other run printed it. - From a tagged run worktree. Every run ran from
bench/2026-10-27-gpt61-terra-frontier-v4, so every run summary carries a clean source block and records the frozen suite lock’s task hash. - No timeouts, no retries. Every run finished inside the flat 3-hour bound; the longest, Extra-high paddockcore, took 19.5 minutes. The sweep log shows each level complete on its first attempt.
- Where and how. The owner’s Mac, one task at a time, on October 27, 2026, from 15:14 to 23:16 UTC. Every integrity audit is clean: no web access, and no benchmark data or answer-key paths.
- The day after release. The Codex CLI is pinned by version, but the sweep cannot pin what OpenAI serves under the model id.
- One attempt per task and level. Runs were not repeated, and effort labels are Codex’s own.
Evidence and reproduction
Public files contain all 115 run measurements, both judges’ six-dimension sub-scores and intent-recovery scores per run, the combined score from each judge alone, hidden behaviours fixed, integrity-audit verdicts, each run’s task hash and Codex notices, raw tokens and API-equivalent cost estimates per run, five aggregates, every calibration gate value, the exact judge protocol text, the operator record for the Max settlecore recovery and source hashes. Each run’s Code quality is (0.24 × reviewed score + 0.09 × intent recovery) / 0.33, where both terms are the equal mean of the two judges, or the reviewed score alone when the run passed no quirk family. The combined score is 100 × (0.50F + 0.085Q + 0.085S + 0.33C / 100). The reproduction guide gives the public arithmetic checks and links the protocol document, the operations log, the decision record, the Codex adapter and the code in the harness repository.
No human rated anything; the scores are model judgment for a human reader, not human validation. Hash checks bind the export to frozen files, including the operator’s superseded marker and the recovered probe; they do not prove that judges were unbiased or that no training overlap exists.
Withheld: raw prompts and responses, submitted patches and reconstructed sources, the quirk answer keys (they describe hidden-test behaviour), reviewer session identifiers and usage receipts, solver event streams (a structure-only redacted trace of every run, every agent message, command and file change with its timing, is public in vulcanbench-gpt61-terra-traces), and host binary paths. Summed solver time is 8.02 hours; judging is excluded.