September 16, 2026 · 114 runs · Code quality protocol v3.6
GPT-5.6 Terra across every effort level
114 runs through the Codex CLI on a ChatGPT subscription, 23 tasks at each of the five effort levels the API offers, with one Max task still waiting for the Codex quota window. Scored with Code quality at 33% of the combined score and judged for a human reader by Muse Spark 1.3 and Grok 4.6 under the same frozen protocol as the other SWE v4 reports, so Terra takes its place on the SWE v4 leaderboard beside GPT-5.5, Luna, Astra and Fable 5.1.
Across every effort level
Terra ran every task once at each of its five effort levels, 23 tasks per cell, through the Codex CLI on a ChatGPT subscription. Combined score weights are 50% functional correctness, 8.5% lint and complexity, 8.5% security and 33% Code quality, judged for a named human reader by Muse Spark 1.3 and Grok 4.6, two judges from labs with no model on this board, with a ground-truth intent-recovery probe. The Max cell holds 22 runs: paddockcore never started because the subscription's quota window closed until September 19, and it will be judged as a top-up.
Combined score
59.70 at Low to 89.46 at Max
The steepest effort curve on the SWE v4 board so far: every step up the ladder adds points, 6.6 from Low to Medium, 10.3 to High, 6.8 to Extra-high and 6.0 to Max.
Tasks passed
2 of 23 at Low to 22 of 22 at Max
Functional correctness drives the curve. Terra passes every judged task at Max and 14 of 23 at Extra-high, but fewer than half below High.
Code quality
70.93 to 73.90
Flat across the ladder: the judges rate Terra's code about the same at every effort, within three points. The effort knob buys correctness, not readability.
Runtime and cost
6.7 to 19.2 min · $0.58 to $2.12 per task
Time and API-equivalent cost climb to Extra-high and ease slightly at Max, which finishes faster (18.6 minutes) and cheaper ($1.72) than Extra-high while passing more tasks.
| Metric | Low | Medium | High | Extra-high | Max |
|---|---|---|---|---|---|
| Combined score | 59.70 | 66.35 | 76.68 | 83.46 | 89.46 |
| Standard error | 3.43 | 3.82 | 3.47 | 2.72 | 0.62 |
| Tasks passed | 2/23 | 5/23 | 11/23 | 14/23 | 22/22 |
| Code quality | 72.31 | 70.93 | 73.90 | 73.13 | 73.58 |
| Human readability | 68.3 | 67.1 | 70.0 | 67.9 | 68.0 |
| Minutes per task | 6.7 | 7.9 | 12.6 | 19.2 | 18.6 |
| API-equivalent $ per task | $0.58 | $0.69 | $1.18 | $2.12 | $1.72 |
Under the prior 50/15/15/20 profile applied to the same Code quality scores the ladder is the same, 62.03 to 91.50. The card and the full per-effort table follow.
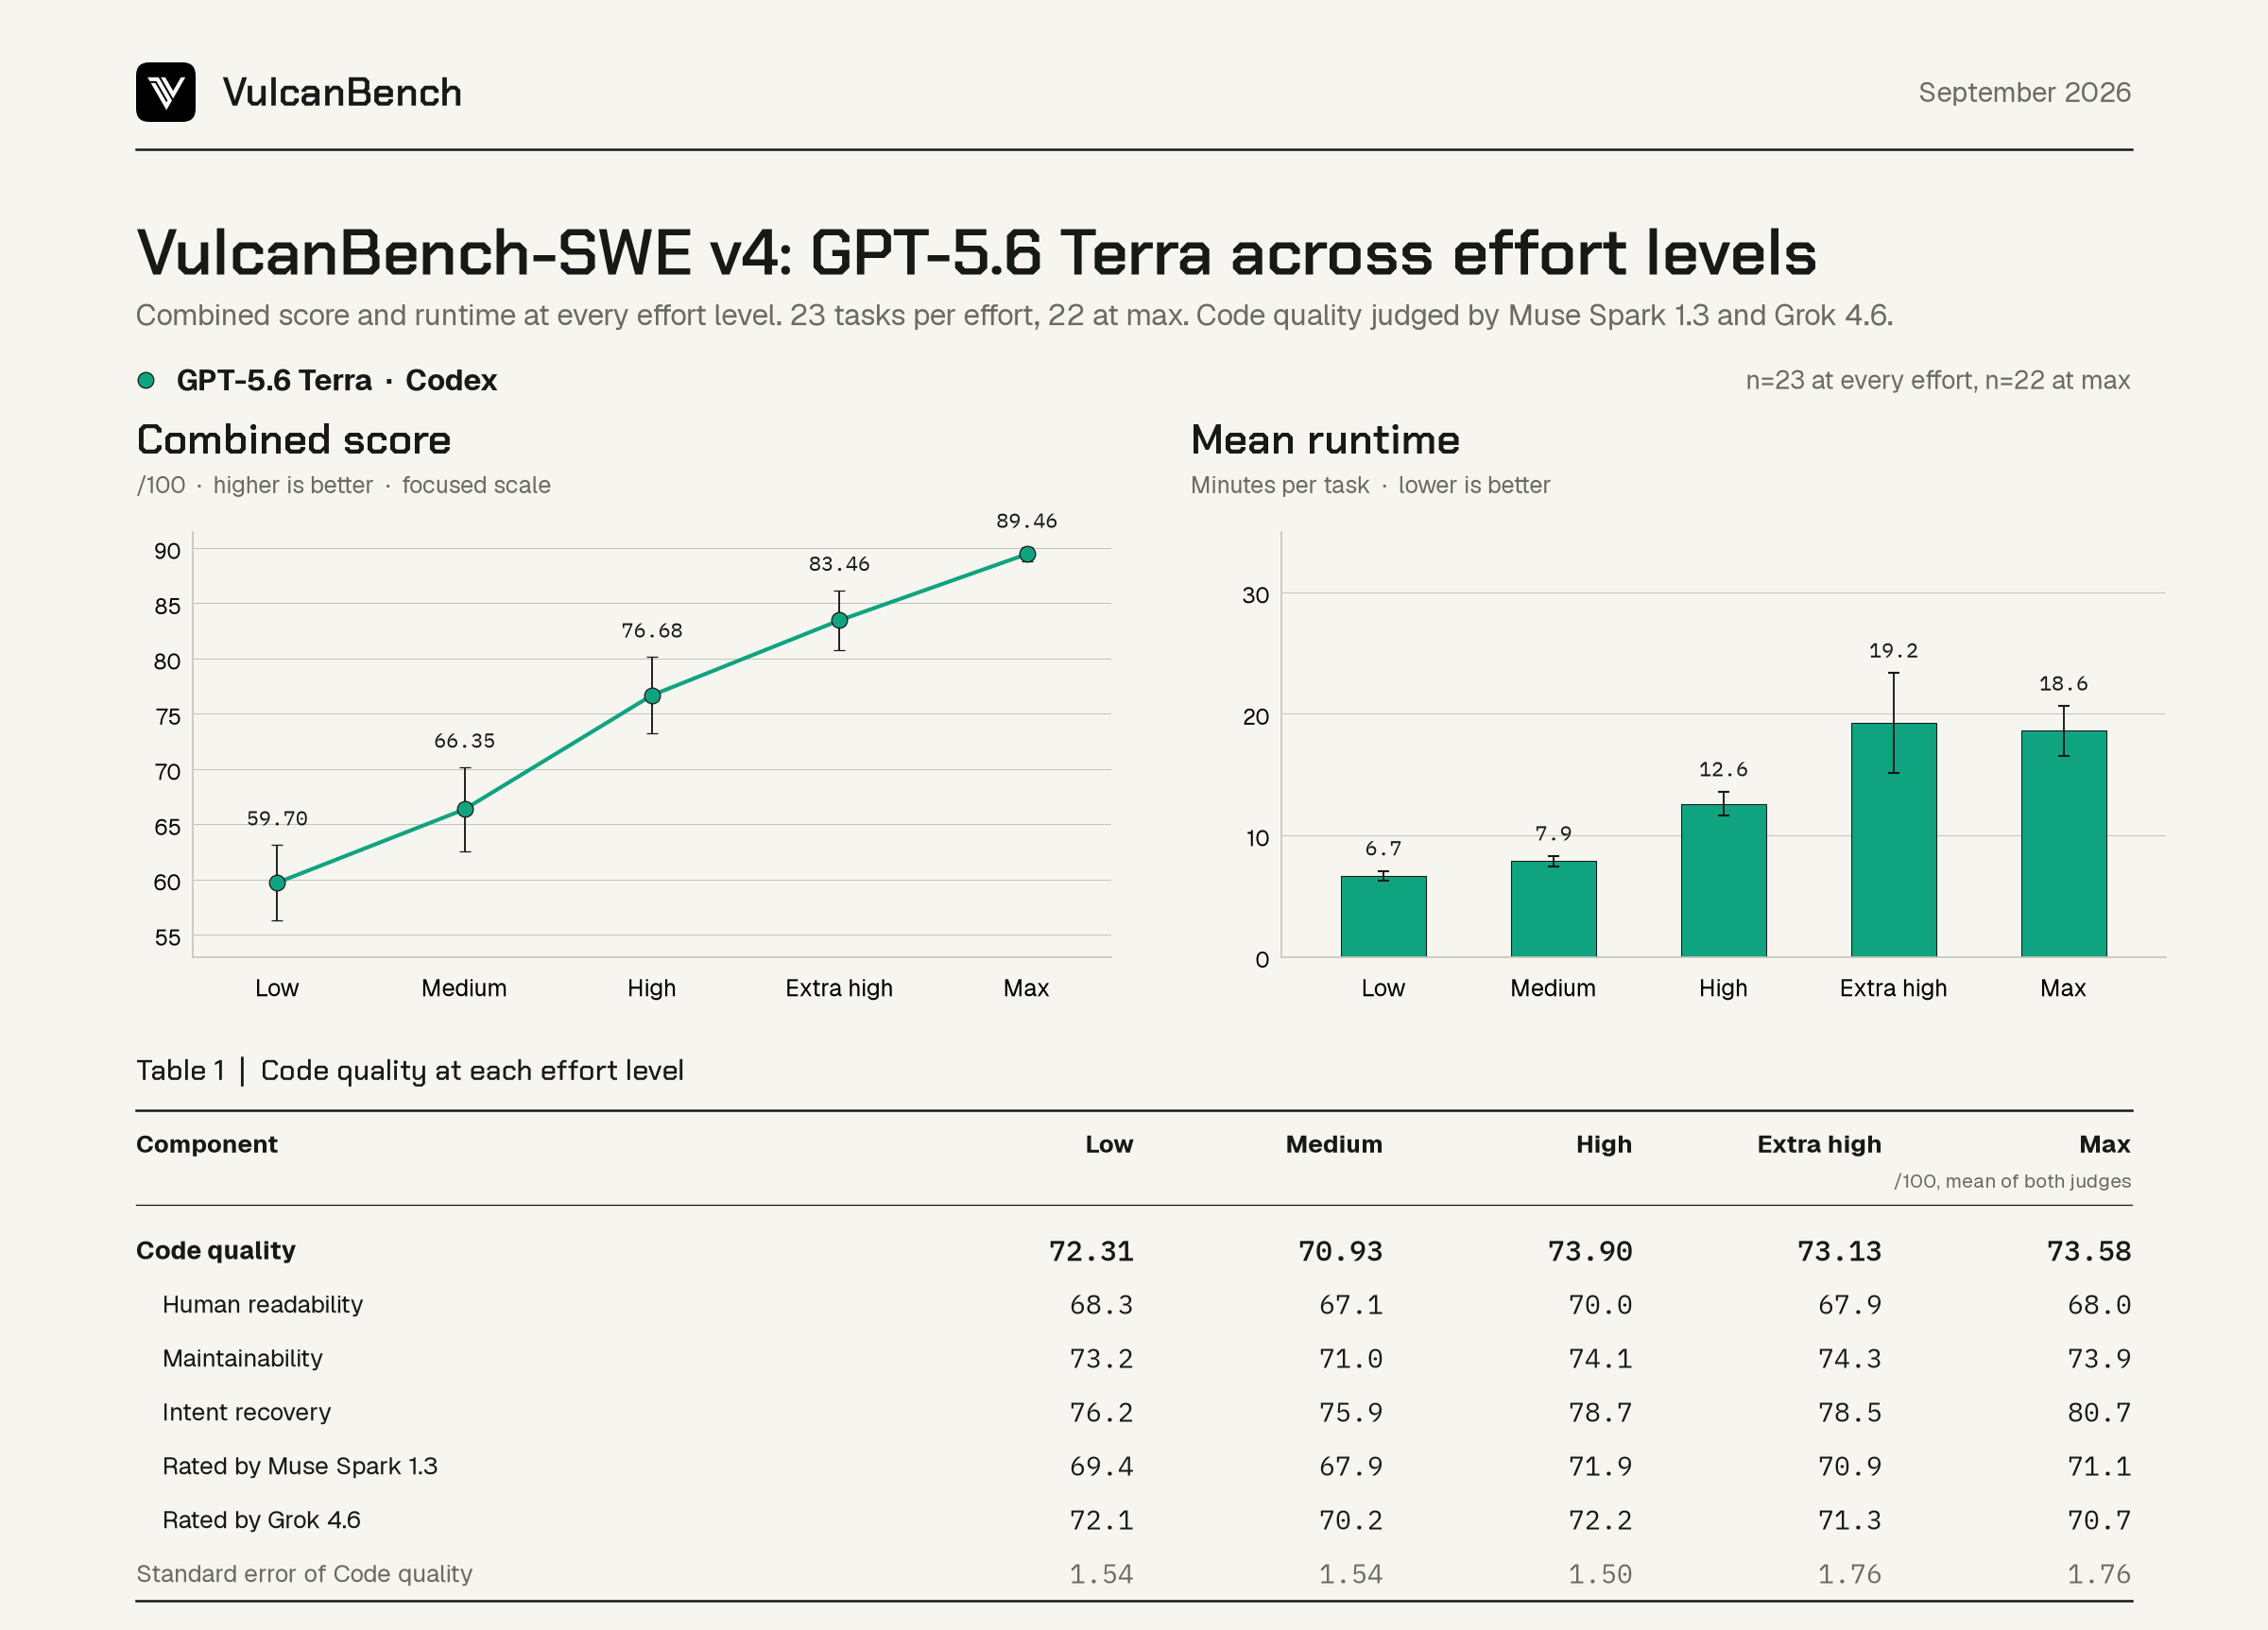
Terra's combined score rises at every step of the effort ladder and its Max level passes every judged task. Code quality does not move with effort. These runs compare a model-and-harness combination, not an isolated base model; the SWE v4 leaderboard places every Terra effort level beside the other models judged under the same protocol.
Combined score and Code quality by effort
n=23 at every effort except Max, which has 22. Combined (33%) is the published score. Combined (20% profile) applies the prior 50/15/15/20 weights to the same Code quality scores for comparison. Code quality, human readability, maintainability and intent recovery are out of 100 and equal means of the two judges. Passed counts tasks with a perfect functional score. Runtime is solver wall-clock per task.
| Model / harness | Effort | Combined (33%) | SE | Combined (20% profile) | Code quality | Human readability | Maintainability | Intent recovery | Passed | Min/task |
|---|---|---|---|---|---|---|---|---|---|---|
| GPT-5.6 Terra / Codex | Low | 59.70 | 3.43 | 62.03 | 72.31 | 68.3 | 73.2 | 76.2* | 2/23 | 6.7 |
| GPT-5.6 Terra / Codex | Medium | 66.35 | 3.82 | 68.89 | 70.93 | 67.1 | 71.0 | 75.9 | 5/23 | 7.9 |
| GPT-5.6 Terra / Codex | High | 76.68 | 3.47 | 78.78 | 73.90 | 70.0 | 74.1 | 78.7* | 11/23 | 12.6 |
| GPT-5.6 Terra / Codex | Extra-high | 83.46 | 2.72 | 85.62 | 73.13 | 67.9 | 74.3 | 78.5 | 14/23 | 19.2 |
| GPT-5.6 Terra / Codex | Max | 89.46 | 0.62 | 91.50 | 73.58 | 68.0 | 73.9 | 80.7 | 22/22 | 18.6 |
*Intent recovery is scored over the specification departures a submission actually passed tests for. One Low run (granarycore) and one High run (schedcore) passed none, so they have no intent-recovery score and their Code quality is the reviewed score alone; the starred means cover the remaining runs.
SE is one sample standard error of the combined score across the cell's tasks. It describes task sampling, not judge uncertainty, repeated runs or a significance test. No solver fallback occurred, and neither judge produced a reviewer fallback on any of the 114 submissions.
Cost and tokens across effort levels
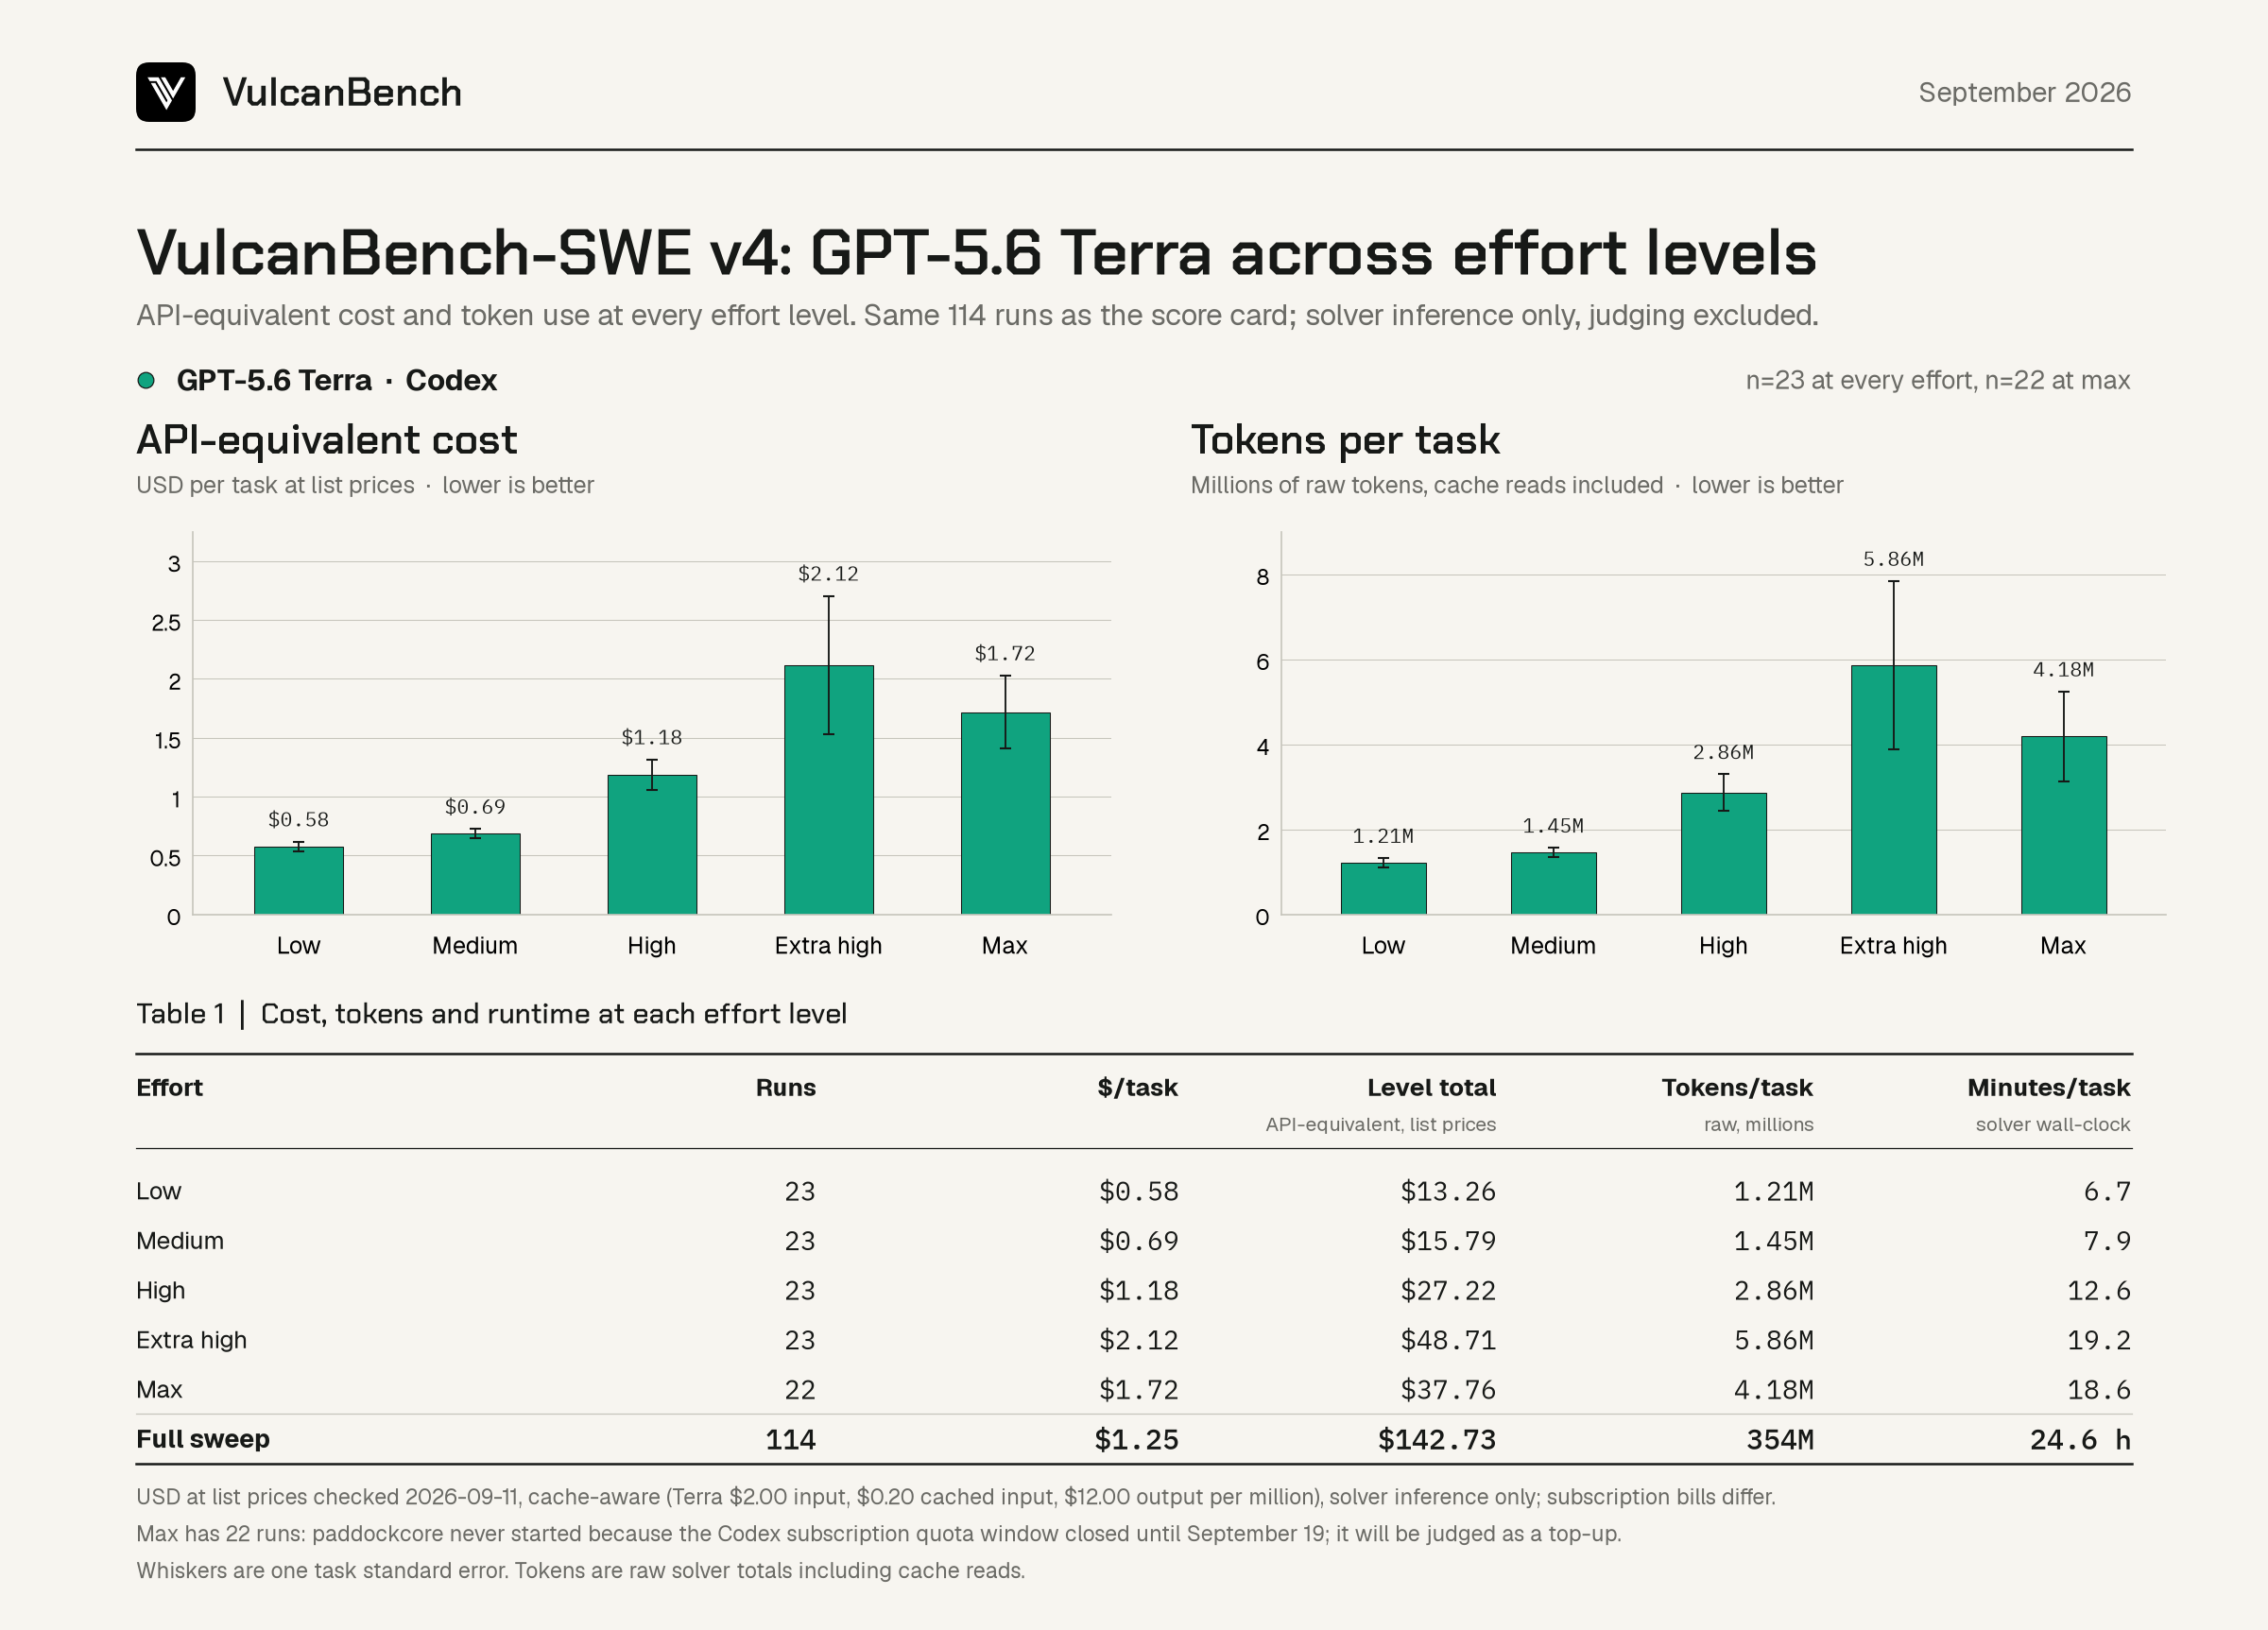
The same 114 runs priced from their Codex receipts at list API rates, cache-aware, with judging excluded. These are API-equivalent estimates, not subscription charges: Terra ran on a ChatGPT subscription, and what the plan actually bills is not observable from the receipts. Cost per task rises from $0.58 at Low to $2.12 at Extra-high, then eases to $1.72 at Max; the whole sweep comes to $142.73 for 114 runs.
| Effort | Runs | $/task | Level total | Tokens/task | Min/task |
|---|---|---|---|---|---|
| Low | 23 | $0.58 | $13.26 | 1.21M | 6.7 |
| Medium | 23 | $0.69 | $15.79 | 1.45M | 7.9 |
| High | 23 | $1.18 | $27.22 | 2.86M | 12.6 |
| Extra-high | 23 | $2.12 | $48.71 | 5.86M | 19.2 |
| Max | 22 | $1.72 | $37.76 | 4.18M | 18.6 |
| Full sweep | 114 | $1.25 | $142.73 | 354M | 24.6 h |
Pricing. Rates checked 2026-09-11 from OpenAI: Terra at $2 input, $0.20 cached input and $12 output per million tokens. Codex receipts report input, cached input, output and reasoning tokens per run, so cached input is billed at the cache-read rate and the rest at the standard rate. Per-request context sizes are not exposed, so no long-context premium is applied. The sweep had stamped each run at a stale list price; every run was re-priced from its receipt and the frozen record's original stamp is kept per run as frozen_record_usd.
Tokens are Codex's raw totals including cache reads. Per-run estimates, token usage breakdowns and the rate table are in economics.json and runs.csv.
What Code quality measures
Every judge receives the same rubric, frozen by hash before any review. It names the reader it scores for: an engineer who has never seen the code, reads it top to bottom without running it, and must make a correct change in one sitting. It tells the judge that its own ease at parsing dense code is not evidence of readability. Six dimensions are scored 0 to 4 in half steps against written anchors: naming, presentation and intent form the human readability sub-score; structure, changeability and verifiability form the maintainability sub-score. Every score must cite an exact excerpt from the code and a concrete consequence for that reader. The host computes the sub-scores; the judge does no arithmetic.
The 33 points have three designed layers. The reviewed panel carries 24 points. An intent-recovery probe carries 9: every task in this suite is a rewrite of a retired binary whose real behaviour departs from its written specification in documented ways, and the judge, given only the specification and the code, must list where the code departs from the specification. A separate call matches that list against a frozen answer key, over the departures the submission passed tests for. The third layer, measured maintenance, is designed for 12 points but is not yet built, so the pre-registered 24 plus 9 split is in force and is stated on the card.
| Component | Low | Medium | High | Extra-high | Max |
|---|---|---|---|---|---|
| Code quality | 72.31 | 70.93 | 73.90 | 73.13 | 73.58 |
| Human readability | 68.3 | 67.1 | 70.0 | 67.9 | 68.0 |
| Maintainability | 73.2 | 71.0 | 74.1 | 74.3 | 73.9 |
| Intent recovery | 76.2 | 75.9 | 78.7 | 78.5 | 80.7 |
| Rated by Muse Spark 1.3 | 69.4 | 67.9 | 71.9 | 70.9 | 71.1 |
| Rated by Grok 4.6 | 72.1 | 70.2 | 72.2 | 71.3 | 70.7 |
| Standard error of Code quality | 1.54 | 1.54 | 1.50 | 1.76 | 1.76 |
Code quality sits between 70.93 and 73.90 at every effort, with the two judges within about three points of each other in every cell. Intent recovery, the ground-truth layer, edges up with effort as more of the hidden contract is implemented; human readability and maintainability do not. Per-run sub-scores from each judge are in runs.csv; the exact rubric, system text, probe and match instructions are in judge-protocols.json.
Judges and calibration
The scored panel is Muse Spark 1.3 (Meta) through the Muse CLI on its Standard tier, and Grok 4.6 (xAI) through the Cursor CLI at medium effort, with equal weight. Neither lab has a model on this board, so neither judge grades a relative. Every session is fresh, tools are disabled, the workspace is empty, model identity is checked per call from the CLI's own records, and solver labels are withheld. Protocol v3.6 changes nothing in the rubric, controls, gates, repeats, seed or judge settings from v3.5; it applies the protocol to this population, and both judges retook the calibration exam under it before any counted call.
Before scoring a single submission, each judge reviews ten held-out programs that implement the same ledger specification: clear, compressed, compressed then auto-formatted, verbose with duplicated policy, needlessly abstracted, misleadingly commented, narrated with a comment on every line, a documented legacy quirk, an embedded instruction to give full marks, and hidden module state. Each program is reviewed five times in a seeded order. Twenty gates fixed in advance check that the judge sees the construct; a judge may miss at most one gate by at most half a point.
| Judge | Protocol | Calls | Result | Allowance used | Failing gates |
|---|---|---|---|---|---|
| Muse Spark 1.3 | code-quality-maintenance-v3.6 | 80 | passed | yes, g11 by 0.02 | g11_repeatability |
| Grok 4.6 | code-quality-maintenance-v3.6 | 80 | passed | no | none |
Muse Spark 1.3 used the pre-registered allowance, as it did under v3.5: its five repeats on one control spread 0.02 of a point more than gate 11 permits, within the half-point allowance, and every other gate passed. Grok 4.6 passed every gate. Both judges separate the clear program from the compressed one by more than two points on naming and by 1.6 to 2.2 points on presentation, credit formatting mainly on presentation, penalise misleading comments on intent, and penalise hidden state on verifiability. Every gate value and control mean is in calibration.json.
Each judge made 437 calls: 80 in calibration, 114 primary reviews, 5 repeats, 10 pairwise checks, 114 intent probes and 114 answer-key matches. Muse needed a second attempt on six calls, all for an unsupported excerpt; on one of them both attempts quoted the same line with its whitespace collapsed, and the first response was selected with the excerpt re-wrapped to the source under the standing recovery rule. Grok needed a second attempt on eight: five unsupported excerpts, one match that cited a departure not on its own list, and two transport faults when the Cursor CLI could not resolve its API host, each retried under the network-fault rule. Every attempt is archived beside its replacement in the harness run directory.
Evidence and reproduction
Public files contain all 114 run measurements, both judges' six-dimension sub-scores and intent-recovery scores per run, raw tokens and API-equivalent cost estimates per run, five aggregates, every calibration gate value, the exact judge protocol text and source hashes. Each run's Code quality is (0.24 × reviewed score + 0.09 × intent recovery) / 0.33, where both terms are the equal mean of the two judges, or the reviewed score alone where intent recovery has no denominator. The combined score is 100 × (0.50F + 0.085Q + 0.085S + 0.33C / 100). The reproduction guide gives the public arithmetic checks and links the protocol documents, controls, runner and operator wrapper.
No human rated anything; the scores are model judgment for a human reader, not human validation. Runs were not repeated, and effort labels are Codex's own. Hash checks bind the export to frozen files; they do not prove that judges were unbiased or that no training overlap exists.
Withheld: raw prompts and responses, submitted patches and reconstructed sources, the quirk answer keys (they describe hidden-test behaviour), and reviewer session identifiers and usage receipts. Summed solver time is 24.60 hours; judging is excluded.