VulcanBench Frontier v4 · October 8, 2026 · 345 runs · three models, five effort levels
Claude Sonnet 5.5 vs Claude Opus 5.5 vs GPT-6.1 Sol
Three current frontier coding models on the same 23 VulcanBench Frontier v4 tasks, once per task at each of five effort levels, Low to Max, 115 runs each. Every number on this page comes from each model’s own published report; nothing was re-run or re-judged. Combined score is 50% functional correctness from hidden tests, 8.5% lint and complexity, 8.5% security and 33% Code quality, judged for a human reader by the same two judges, Muse Spark 1.3 and Grok 4.6, neutral for both labs. Read the methods and caveats before quoting a small gap.
What we found
Highest score
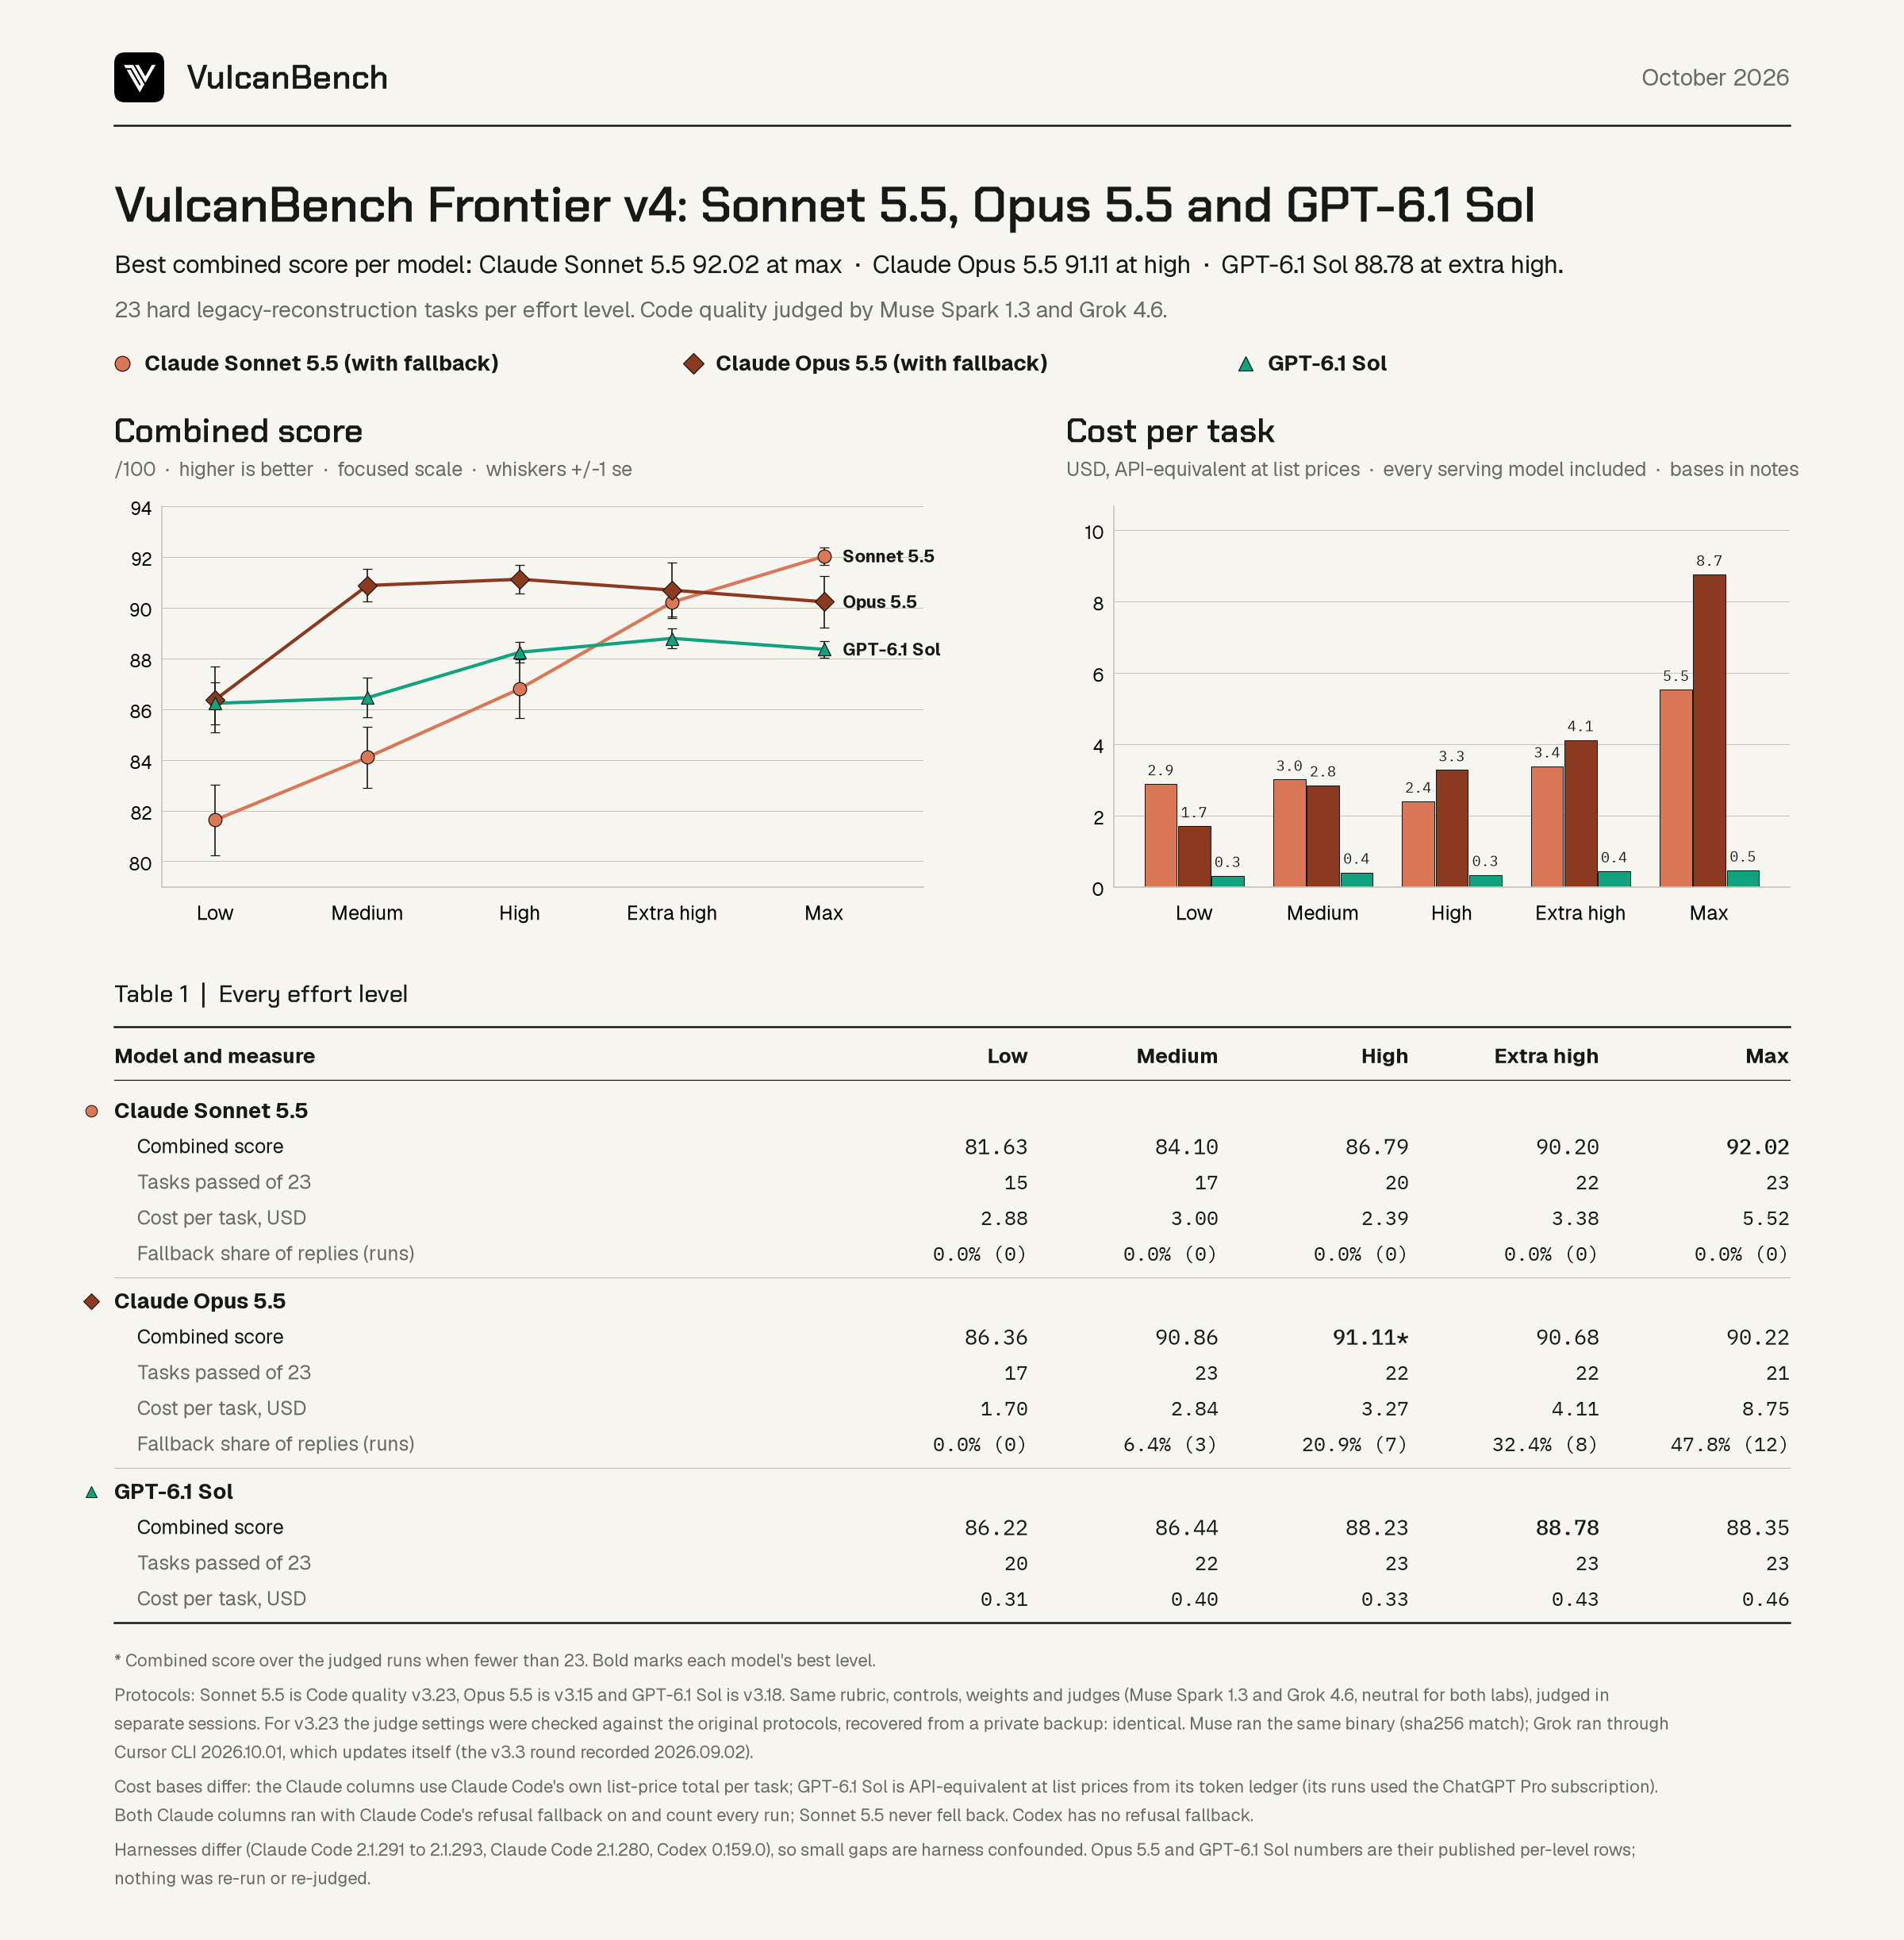
Sonnet 5.5 at Max: 92.02 ± 0.35
Sonnet 5.5’s best edges Opus 5.5’s best (91.11 ± 0.57 at High, judged on 22 runs) by about 0.9 points, roughly 1.4 combined standard errors: ahead on the point estimate, not a clear win. Both are clearly ahead of GPT-6.1 Sol’s best, 88.78 ± 0.40 at Extra-high. Sonnet 5.5 also has the steepest effort curve of the three, 81.63 at Low to 92.02 at Max and 15 to 23 tasks, and is the lowest of the three on combined score at Low, Medium and High.
Tasks solved
Out of 23, Low to Max: Sonnet 5.5 15, 17, 20, 22, 23; Opus 5.5 17, 23, 22, 22, 21; GPT-6.1 Sol 20, 22, 23, 23, 23
GPT-6.1 Sol solves the most tasks at Low, High and Extra-high. Opus 5.5 solves all 23 at Medium. At Max, Sonnet 5.5 and GPT-6.1 Sol both solve all 23 and Opus 5.5 solves 21. Sonnet 5.5 solves the fewest from Low to High and ties Opus 5.5 at Extra-high.
Cost per task
Sonnet 5.5 $2.39 to $5.52 · Opus 5.5 $1.70 to $8.75 · GPT-6.1 Sol $0.31 to $0.46
GPT-6.1 Sol is by far the cheapest: 7 to 12 times less than Sonnet 5.5 at every level, and 5 to 19 times less than Opus 5.5. Sonnet 5.5 costs 70% more than Opus 5.5 at Low and about the same at Medium, then 18% to 37% less from High up. The cost bases differ; see the caveats.
Time per task
GPT-6.1 Sol is the fastest at every level
GPT-6.1 Sol takes 6.9 to 15.4 minutes a task. Sonnet 5.5 is the slowest at every level except High, where it beats Opus 5.5 (14.8 against 21.4 minutes); at Max both Claude models take about 38 minutes.
Code quality follows the same climb: Sonnet 5.5 rates lowest of the three from Low to High (61.67 to 70.84), between the other two at Extra-high (75.78, against 79.98 for Opus 5.5 and 74.99 for GPT-6.1 Sol) and highest at Max (81.72, against 79.77 and 73.80). In short, Sonnet 5.5 at Max ($5.52 a task) and Opus 5.5 at High ($3.27) give the two highest scores here, too close to separate firmly, with Opus 5.5 at Medium next (90.86, $2.84). GPT-6.1 Sol’s best is 2.3 to 3.2 points lower, at $0.43 a task and the shortest runtime. Sonnet 5.5 needs high effort to keep up: below Extra-high it trails both.
The whole sweep of 115 runs cost $394.77 for Sonnet 5.5, $475.33 for Opus 5.5 and $44.33 for GPT-6.1 Sol, and took 44.1, 42.9 and 22.0 hours of solver time.
Every level, side by side
One row per model at each effort level. Combined score is the mean over the judged runs, with ±1 sample standard error across tasks and the number of judged runs (n). Code quality is out of 100. Passed counts all 23 runs. Cost and minutes are means per task over all 23 runs; their standard errors are in each model’s bundle.
| Model / harness | Effort | Combined | ±1 SE | Judged n | Code quality | Passed | $/task | Min/task |
|---|---|---|---|---|---|---|---|---|
| Claude Sonnet 5.5 / Claude Code | Low | 81.63 | ±1.38 | 23 | 61.67 | 15/23 | $2.88 | 20.0 |
| Claude Opus 5.5 / Claude Code | Low | 86.36 | ±1.30 | 23 | 72.53 | 17/23 | $1.70 | 13.7 |
| GPT-6.1 Sol / Codex | Low | 86.22 | ±0.82 | 23 | 70.79 | 20/23 | $0.31 | 6.9 |
| Claude Sonnet 5.5 / Claude Code | Medium | 84.10 | ±1.20 | 23 | 65.35 | 17/23 | $3.00 | 20.8 |
| Claude Opus 5.5 / Claude Code | Medium | 90.86 | ±0.64 | 23 | 77.32 | 23/23 | $2.84 | 18.6 |
| GPT-6.1 Sol / Codex | Medium | 86.44 | ±0.78 | 23 | 70.25 | 22/23 | $0.40 | 10.6 |
| Claude Sonnet 5.5 / Claude Code | High | 86.79 | ±1.15 | 23 | 70.84 | 20/23 | $2.39 | 14.8 |
| Claude Opus 5.5 / Claude Code | High | 91.11 | ±0.57 | 22 | 77.99 | 22/23 | $3.27 | 21.4 |
| GPT-6.1 Sol / Codex | High | 88.23 | ±0.40 | 23 | 73.67 | 23/23 | $0.33 | 10.2 |
| Claude Sonnet 5.5 / Claude Code | Extra-high | 90.20 | ±0.57 | 23 | 75.78 | 22/23 | $3.38 | 21.6 |
| Claude Opus 5.5 / Claude Code | Extra-high | 90.68 | ±1.10 | 23 | 79.98 | 22/23 | $4.11 | 20.7 |
| GPT-6.1 Sol / Codex | Extra-high | 88.78 | ±0.40 | 23 | 74.99 | 23/23 | $0.43 | 15.4 |
| Claude Sonnet 5.5 / Claude Code | Max | 92.02 | ±0.35 | 23 | 81.72 | 23/23 | $5.52 | 38.0 |
| Claude Opus 5.5 / Claude Code | Max | 90.22 | ±1.02 | 23 | 79.77 | 21/23 | $8.75 | 37.5 |
| GPT-6.1 Sol / Codex | Max | 88.35 | ±0.33 | 23 | 73.80 | 23/23 | $0.46 | 14.5 |
Refusal fallback
When a safeguard classifier refuses a turn, Claude Code can finish the session on another model. Both Claude columns ran with that fallback on, following Artificial Analysis’s Default Fallback convention, and every run counts. Codex has no refusal fallback.
| Model | Low | Medium | High | Extra-high | Max |
|---|---|---|---|---|---|
| Claude Sonnet 5.5 | none | none | none | none | none |
| Claude Opus 5.5 (Opus 4.8 replies) | 0 of 23 runs, 0.0% of replies | 3 of 23 runs, 6.4% of replies | 7 of 23 runs, 20.9% of replies | 8 of 23 runs, 32.4% of replies | 12 of 23 runs, 47.8% of replies |
| GPT-6.1 Sol | n/a | n/a | n/a | n/a | n/a |
Sonnet 5.5 never fell back: every reply in every run came from claude-sonnet-5-5. Opus 5.5’s higher levels partly measure Opus 4.8, and at Max nearly half its replies came from it; its cost includes the fallback model’s usage.
Methods and caveats
- Same tasks, same rubric, same judges. All three ran the same 23 Frontier v4 tasks, one attempt per task and level, inside a flat 3-hour bound, and none timed out. Code quality was judged under one rubric by Muse Spark 1.3 (Meta) and Grok 4.6 (xAI), neutral for both Anthropic and OpenAI.
- Separate judging sessions. Sonnet 5.5 was judged under protocol v3.23, Opus 5.5 under v3.15 and GPT-6.1 Sol under v3.18. Each applies the same rubric, controls, gates and weights to its own population, and each judge retook the calibration exam every time.
- Cost bases differ. The two Claude columns use Claude Code’s own list-price total per run. GPT-6.1 Sol is API-equivalent at list prices, recomputed from its token ledger, while its runs used a ChatGPT Pro subscription. None of these is a bill.
- Harnesses differ. Sonnet 5.5 ran on Claude Code 2.1.291 to 2.1.293, Opus 5.5 on Claude Code 2.1.280 and GPT-6.1 Sol on Codex 0.159.0, so small gaps between columns are harness confounded. These runs measure a model-and-harness pair, not a bare model.
- Refusal fallback. Opus 5.5 ran with Claude Code’s refusal fallback on, and its fallback share per level is shown above. Sonnet 5.5 had it on and never used it. Codex has no fallback.
- Short cells. Opus 5.5 at High is judged on 22 of 23 runs: on depotcore a safeguard stop left an empty patch, so there was no code to review; the run counts as failed and is priced. GPT-6.1 Sol at Medium includes one run, paddockcore, scored from Muse Spark 1.3 alone because Grok 4.6’s review of it had no valid response.
- Sonnet 5.5 disclosures. The Sonnet sweep predates the harness’s tagged-worktree rule and was admitted to judging through a committed task hash bridge, with task content verified identical to the frozen suite. Its judge settings are identical to the original v3.3 and v3.4 protocols, Muse Spark 1.3 ran the same binary, and Grok 4.6 ran through a newer Cursor CLI (2026.10.01) than the v3.3 round (2026.09.02), with the same model id; Cursor now labels it “Grok 4.6 Medium” rather than the frozen “Cursor Grok 4.6 Medium”, a rename the judging wrapper accepts. Details are in the Sonnet 5.5 report.
- Standard errors describe task sampling across 23 tasks, not judge uncertainty or repeated runs, and are not a significance test. No human rated anything; Code quality is model judgment for a human reader. Frontier Code quality is never compared with Routine v1 Code quality.
Every column also sits on the Frontier v4 leaderboard beside the other models judged under the same rubric.
Get the data
Every number above can be recomputed from public files. Each bundle holds every run’s scores, both judges’ sub-scores, tokens and cost, the per-level aggregates, the calibration record and the exact judge protocol text.
- Claude Sonnet 5.5: evidence bundle (runs.csv, scores by level), harness results folder, redacted agent traces.
- Claude Opus 5.5: evidence bundle (runs.csv), harness results folder, redacted agent traces.
- GPT-6.1 Sol: evidence bundle (runs.csv, scores by level), harness results folder.
- All Frontier v4 columns: the leaderboard as CSV.
Withheld for every model: raw prompts and responses, submitted patches, and the quirk answer keys, which describe hidden-test behaviour.