October 8, 2026 · 115 runs · Code quality protocol v3.23
Claude Sonnet 5.5 across every effort level
115 runs of Claude Sonnet 5.5 through Claude Code on a Claude Max subscription, 23 tasks at each of five effort levels, Low to Max. Code quality carries 33% of the combined score and is judged for a human reader by Muse Spark 1.3 and Grok 4.6 under the same rubric, controls and gates as the other Frontier v4 reports, so Sonnet 5.5 takes its place on the Frontier v4 leaderboard beside Claude Opus 5.5 and Claude Fable 5.1. Every run finished inside the 3-hour task bound and none was excluded. Two things about how this column was produced differ from earlier ones and are disclosed below: the sweep predates the harness’s tagged-worktree rule, and Grok 4.6 judged through a newer Cursor CLI than in earlier rounds.
How the test works
A retired program to rebuild
Each of the 23 tasks is a legacy binary with a written specification and an issue. Its real behaviour departs from the specification in documented ways, and hidden tests check the rewrite against the binary.
One attempt per task and level
Claude Sonnet 5.5 works in Claude Code with the binary, the specification and the code, once per task at each effort level, inside a flat 3-hour bound, one task at a time.
Tests and two judges score it
Hidden tests give functional correctness. Two calibrated judges from labs other than Anthropic rate the code for a human reader and try to recover the documented departures.
Scores, time and cost per level
Each level gets a combined score, tasks passed, minutes and cost. Cost is Claude Code’s own list-price total for each run.
Combined score = 50% functional correctness + 8.5% lint and complexity + 8.5% security + 33% Code quality, averaged over the judged runs in each level, as on every other board column. Frontier Code quality is the reviewed layer plus intent recovery; it is never compared with Routine v1 Code quality.
Across every effort level
Claude Sonnet 5.5 (claude-sonnet-5-5) ran every task once at each of its five effort levels, 23 tasks per cell, through Claude Code 2.1.291 to 2.1.293 on a Claude Max subscription, from October 6, 06:49 PDT, to October 8, 03:38 PDT, 2026, on the owner’s Mac in the local sandbox, one task at a time. Combined score weights are 50% functional correctness, 8.5% lint and complexity, 8.5% security and 33% Code quality, judged for a named human reader by Muse Spark 1.3 and Grok 4.6 with a ground-truth intent-recovery probe. No run reached the flat 3-hour task bound; the longest, Medium lodgecore, took 137 minutes. Anthropic’s default effort for Sonnet 5.5 on the Claude API is High; the vendor does not state a Claude Code default.
Combined score
81.63 to 92.02
It rises at every step: 81.63 at Low, 84.10 at Medium, 86.79 at High, 90.20 at Extra-high and 92.02 at Max, a gain of 10.39 points, while the standard error narrows from 1.38 at Low to 0.35 at Max.
Tasks passed
15 of 23 at Low, 23 of 23 at Max
pass@1 rises at every step: 0.652 (±0.102) at Low, 0.739 (±0.094) at Medium, 0.870 (±0.072) at High, 0.957 (±0.043) at Extra-high and 1.000 at Max. Of the 231 hidden behaviours the tasks test for, it fixes 214, 219, 223, 230 and all 231.
Code quality
61.67 to 81.72
Code quality also rises at every step, from 61.67 at Low to 81.72 at Max, with standard errors of 0.99 to 2.08.
Runtime and cost
14.8 to 38.0 min · $2.39 to $5.52 per task
High is the fastest and cheapest level (14.8 minutes, $2.39 a task); Max is the slowest and dearest (38.0 minutes, $5.52). The whole sweep comes to $394.77, $3.43 per task, at about 9.7M raw tokens per task.
| Metric | Low | Medium | High | Extra-high | Max |
|---|---|---|---|---|---|
| Combined score | 81.63 | 84.10 | 86.79 | 90.20 | 92.02 |
| Standard error | 1.38 | 1.20 | 1.15 | 0.57 | 0.35 |
| Judged runs | 23 | 23 | 23 | 23 | 23 |
| Tasks passed | 15/23 | 17/23 | 20/23 | 22/23 | 23/23 |
| Hidden behaviours fixed | 214/231 | 219/231 | 223/231 | 230/231 | 231/231 |
| Code quality | 61.67 | 65.35 | 70.84 | 75.78 | 81.72 |
| Human readability | 53.4 | 54.4 | 65.9 | 72.2 | 79.5 |
| Minutes per task | 20.0 | 20.8 | 14.8 | 21.6 | 38.0 |
| Standard error of minutes | 6.0 | 6.9 | 3.1 | 4.2 | 3.6 |
| $ per task (Claude Code) | $2.88 | $3.00 | $2.39 | $3.38 | $5.52 |
| Standard error of $ per task | $0.97 | $1.02 | $0.71 | $0.79 | $0.84 |
Under the prior 50/15/15/20 profile applied to the same Code quality scores the ladder runs 85.24 to 92.91. Low and Medium have long runtime tails (Low granarycore took 101 minutes and Medium lodgecore 137), which is why their standard errors of minutes and cost are wide. The card and the full per-effort table follow.
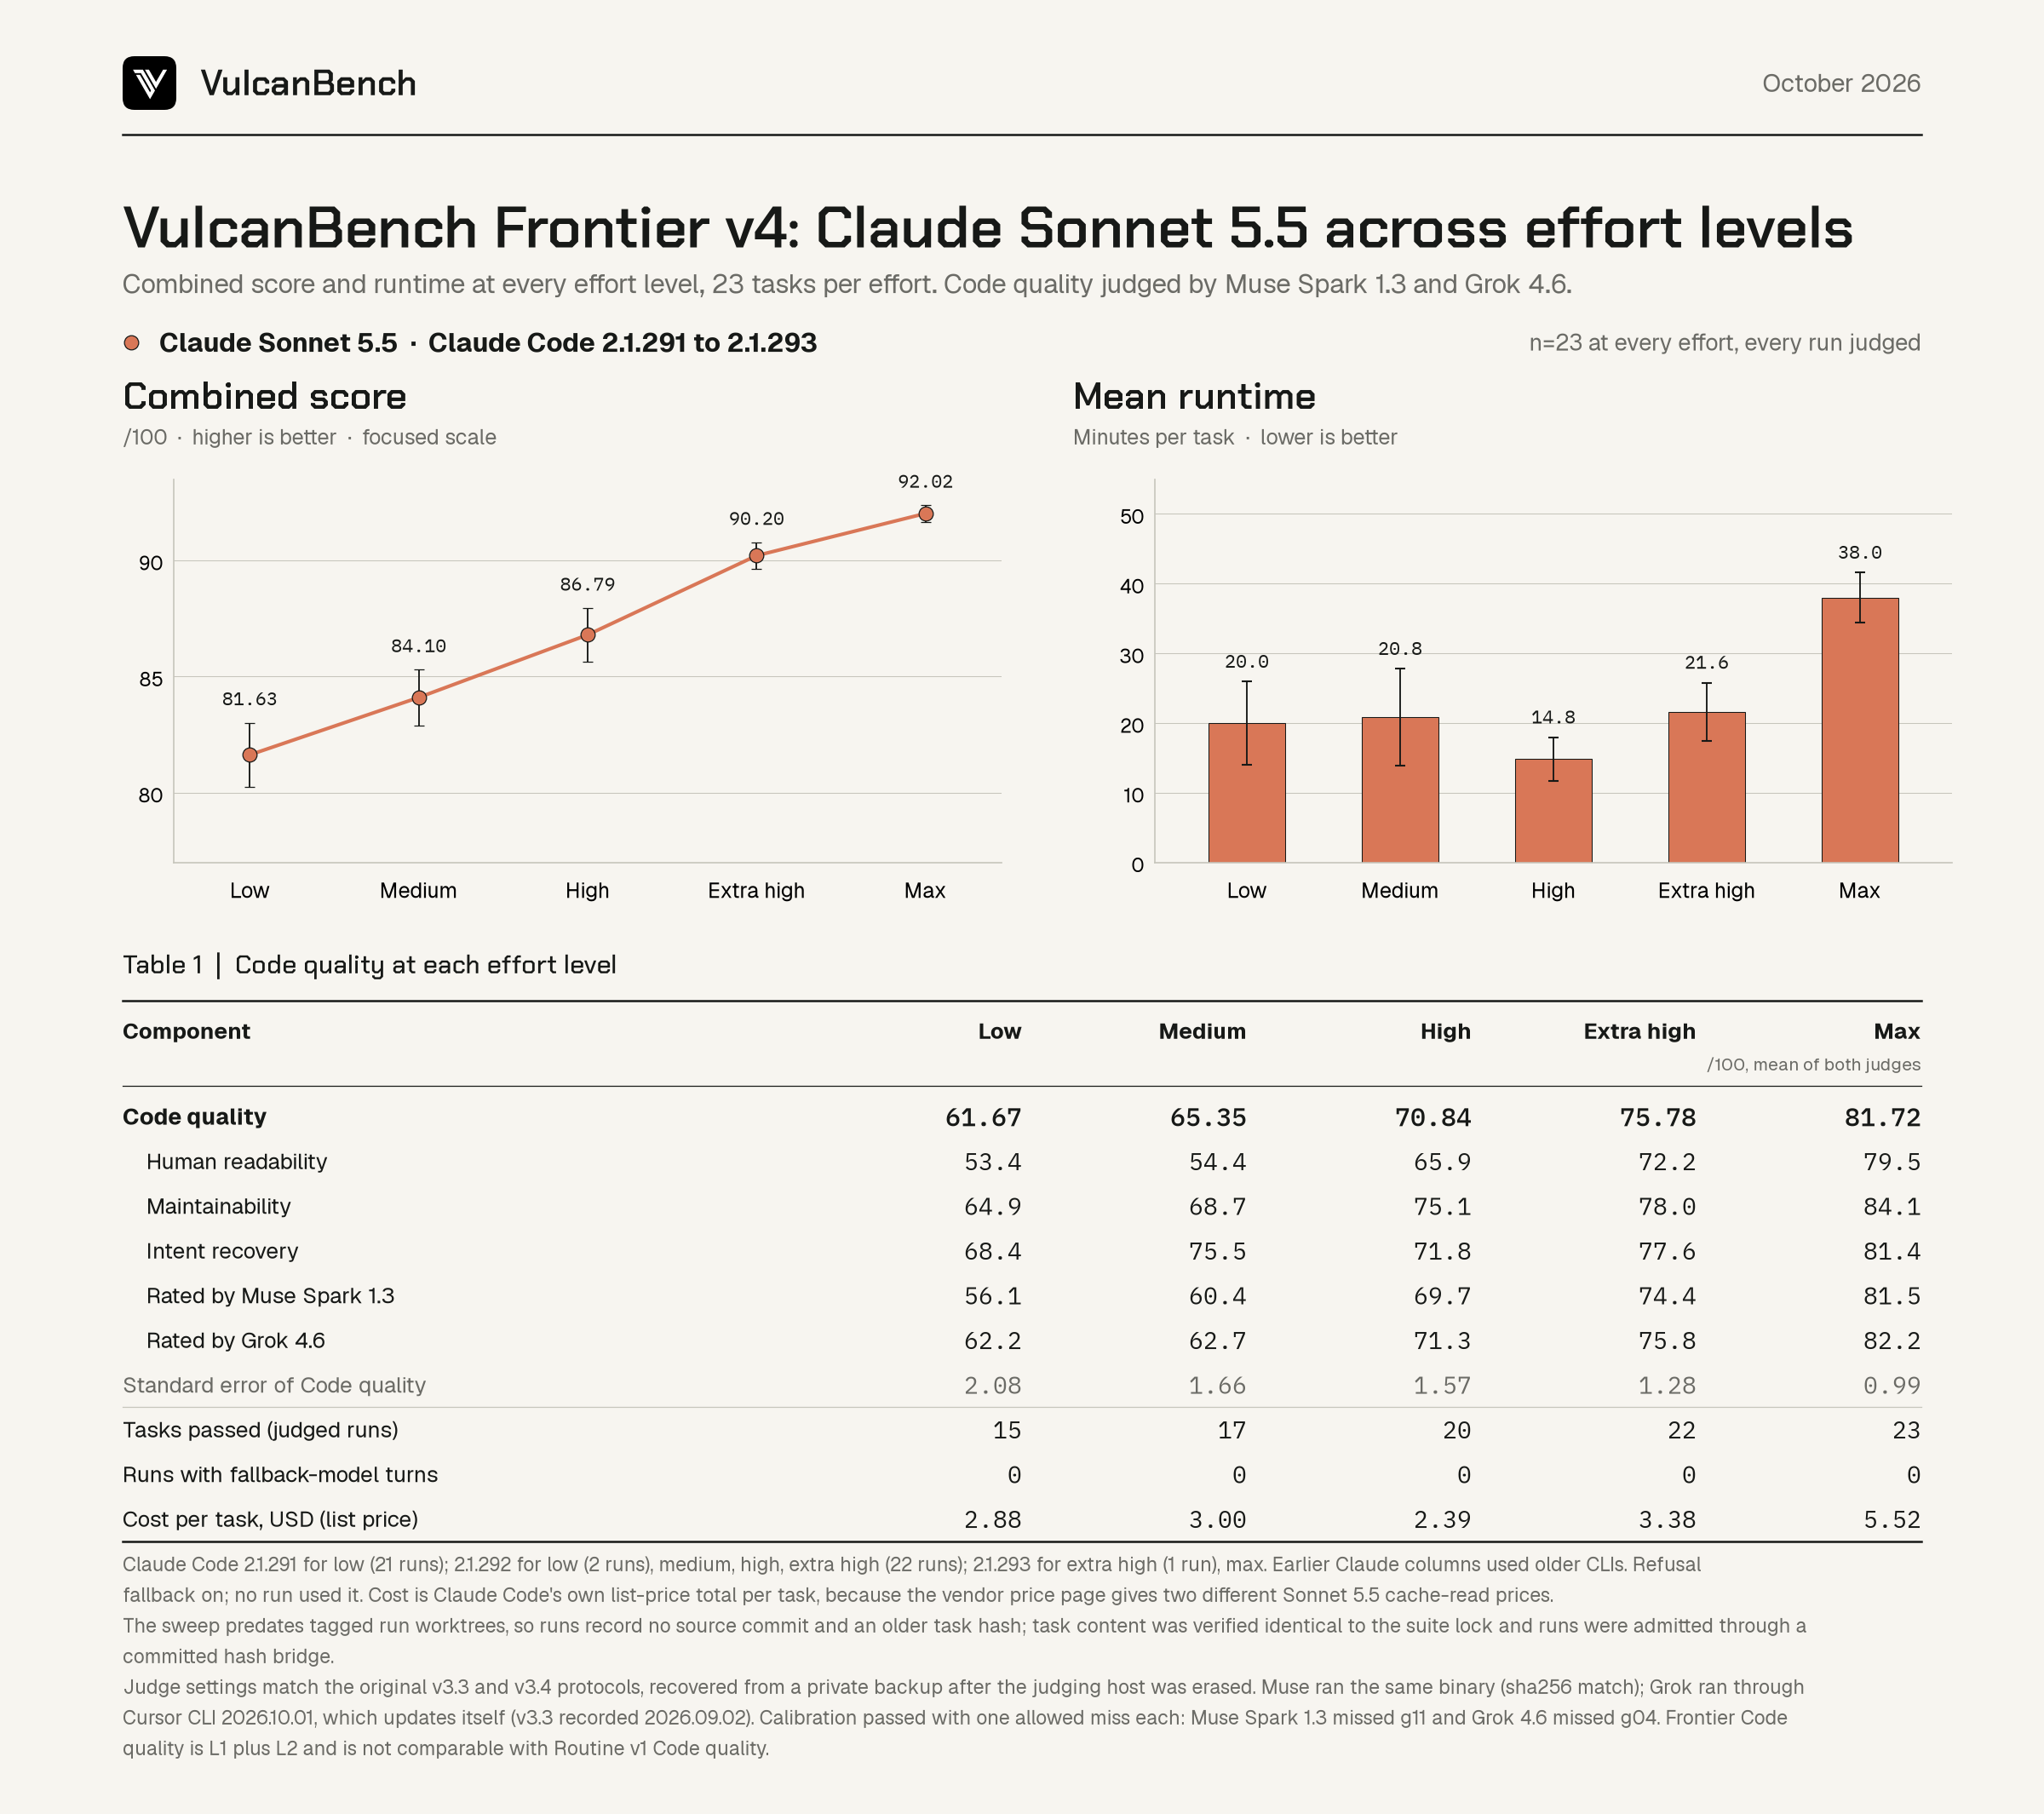
Sonnet 5.5 gains more from effort than Opus 5.5 or Fable 5.1: Low passes 15 of 23 tasks at 81.63, Max passes all 23 at 92.02, and Code quality climbs 20 points over the same range. At Max it has the highest combined point estimate of any column judged by Muse Spark 1.3 and Grok 4.6, level with Fable 5.1 at Max (91.84 ± 0.47) within one standard error. These runs compare a model-and-harness combination, not an isolated base model; the Frontier v4 leaderboard places every Sonnet 5.5 effort level beside the other models judged under the same rubric.
Combined score and Code quality by effort
n=23 at every level unless the Judged column says otherwise. Combined (33%) is the published score. Combined (20% profile) applies the prior 50/15/15/20 weights to the same Code quality scores for comparison. Code quality, human readability, maintainability and intent recovery are out of 100 and equal means of the two judges. Passed counts all 23 runs. Runtime is solver wall-clock per task over every run in the cell.
| Model / harness | Effort | Combined (33%) | SE | Combined (20% profile) | Code quality | Human readability | Maintainability | Intent recovery | Judged | Passed | Min/task |
|---|---|---|---|---|---|---|---|---|---|---|---|
| Claude Sonnet 5.5 / Claude Code | Low | 81.63 | 1.38 | 85.24 | 61.67 | 53.4 | 64.9 | 68.4 | 23/23 | 15/23 | 20.0 |
| Claude Sonnet 5.5 / Claude Code | Medium | 84.10 | 1.20 | 87.25 | 65.35 | 54.4 | 68.7 | 75.5 | 23/23 | 17/23 | 20.8 |
| Claude Sonnet 5.5 / Claude Code | High | 86.79 | 1.15 | 89.29 | 70.84 | 65.9 | 75.1 | 71.8 | 23/23 | 20/23 | 14.8 |
| Claude Sonnet 5.5 / Claude Code | Extra-high | 90.20 | 0.57 | 92.08 | 75.78 | 72.2 | 78.0 | 77.6 | 23/23 | 22/23 | 21.6 |
| Claude Sonnet 5.5 / Claude Code | Max | 92.02 | 0.35 | 92.91 | 81.72 | 79.5 | 84.1 | 81.4 | 23/23 | 23/23 | 38.0 |
Four factors by effort. Functional correctness averages 92.13 at Low, 94.59 at Medium, 96.21 at High, 99.71 at Extra-high and 100.00 at Max; lint and complexity 78.97, 79.22, 80.14, 81.99 and 83.17; security 100.00 at Low, Medium and High, 98.48 at Extra-high and 93.91 at Max. Only the Code quality factor depends on the judges.
Intent recovery is scored over the specification departures a submission actually passed tests for. Every Sonnet 5.5 run passed at least one, so no run fell back to the reviewed score alone. SE is one sample standard error across the cell’s tasks. It describes task sampling, not judge uncertainty, repeated runs or a significance test. Every run is the equal mean of both judges. Neither judge produced a reviewer fallback.
Cost and tokens across effort levels
Cost is Claude Code’s own list-price total for each run, as for the Opus 5.5 column. Anthropic’s pricing page lists Sonnet 5.5 at $2 input and $10 output per million tokens, with cache writes at $2.50 (5 minutes) and $4 (1 hour), but gives two cache-read prices: $0.20 per million in its table and 0.05× input ($0.10) in its prompt caching section. Rather than pick one, every figure here is the cost Claude Code reports per run (cli_reported_cost_usd), checked against the session’s final total. Sonnet 5.5 ran on a Claude Max subscription, so these are API-equivalent estimates, not bills; judging is excluded.
| Effort | Runs | $/task | ±SE | Level total | Tokens/task | Min/task |
|---|---|---|---|---|---|---|
| Low | 23 | $2.88 | $0.97 | $66.15 | 9.02M | 20.0 |
| Medium | 23 | $3.00 | $1.02 | $69.05 | 9.49M | 20.8 |
| High | 23 | $2.39 | $0.71 | $54.98 | 6.77M | 14.8 |
| Extra-high | 23 | $3.38 | $0.79 | $77.63 | 8.94M | 21.6 |
| Max | 23 | $5.52 | $0.84 | $126.95 | 14.11M | 38.0 |
| Full sweep | 115 | $3.43 | $394.77 | 1,112M | 44.1 h |
Tokens are Claude Code’s usage for the session from its final record: input, cache reads, cache writes and output, with cache reads the bulk. Median completion tokens per task (the model’s own output, reasoning included) are about 30K at Low, 35K at Medium, 37K at High, 67K at Extra-high and 157K at Max. Every reply in every run came from claude-sonnet-5-5, so no other model’s usage is in these totals. Per-run figures are in economics.json and runs.csv.
Beside Claude Opus 5.5 and Claude Fable 5.1
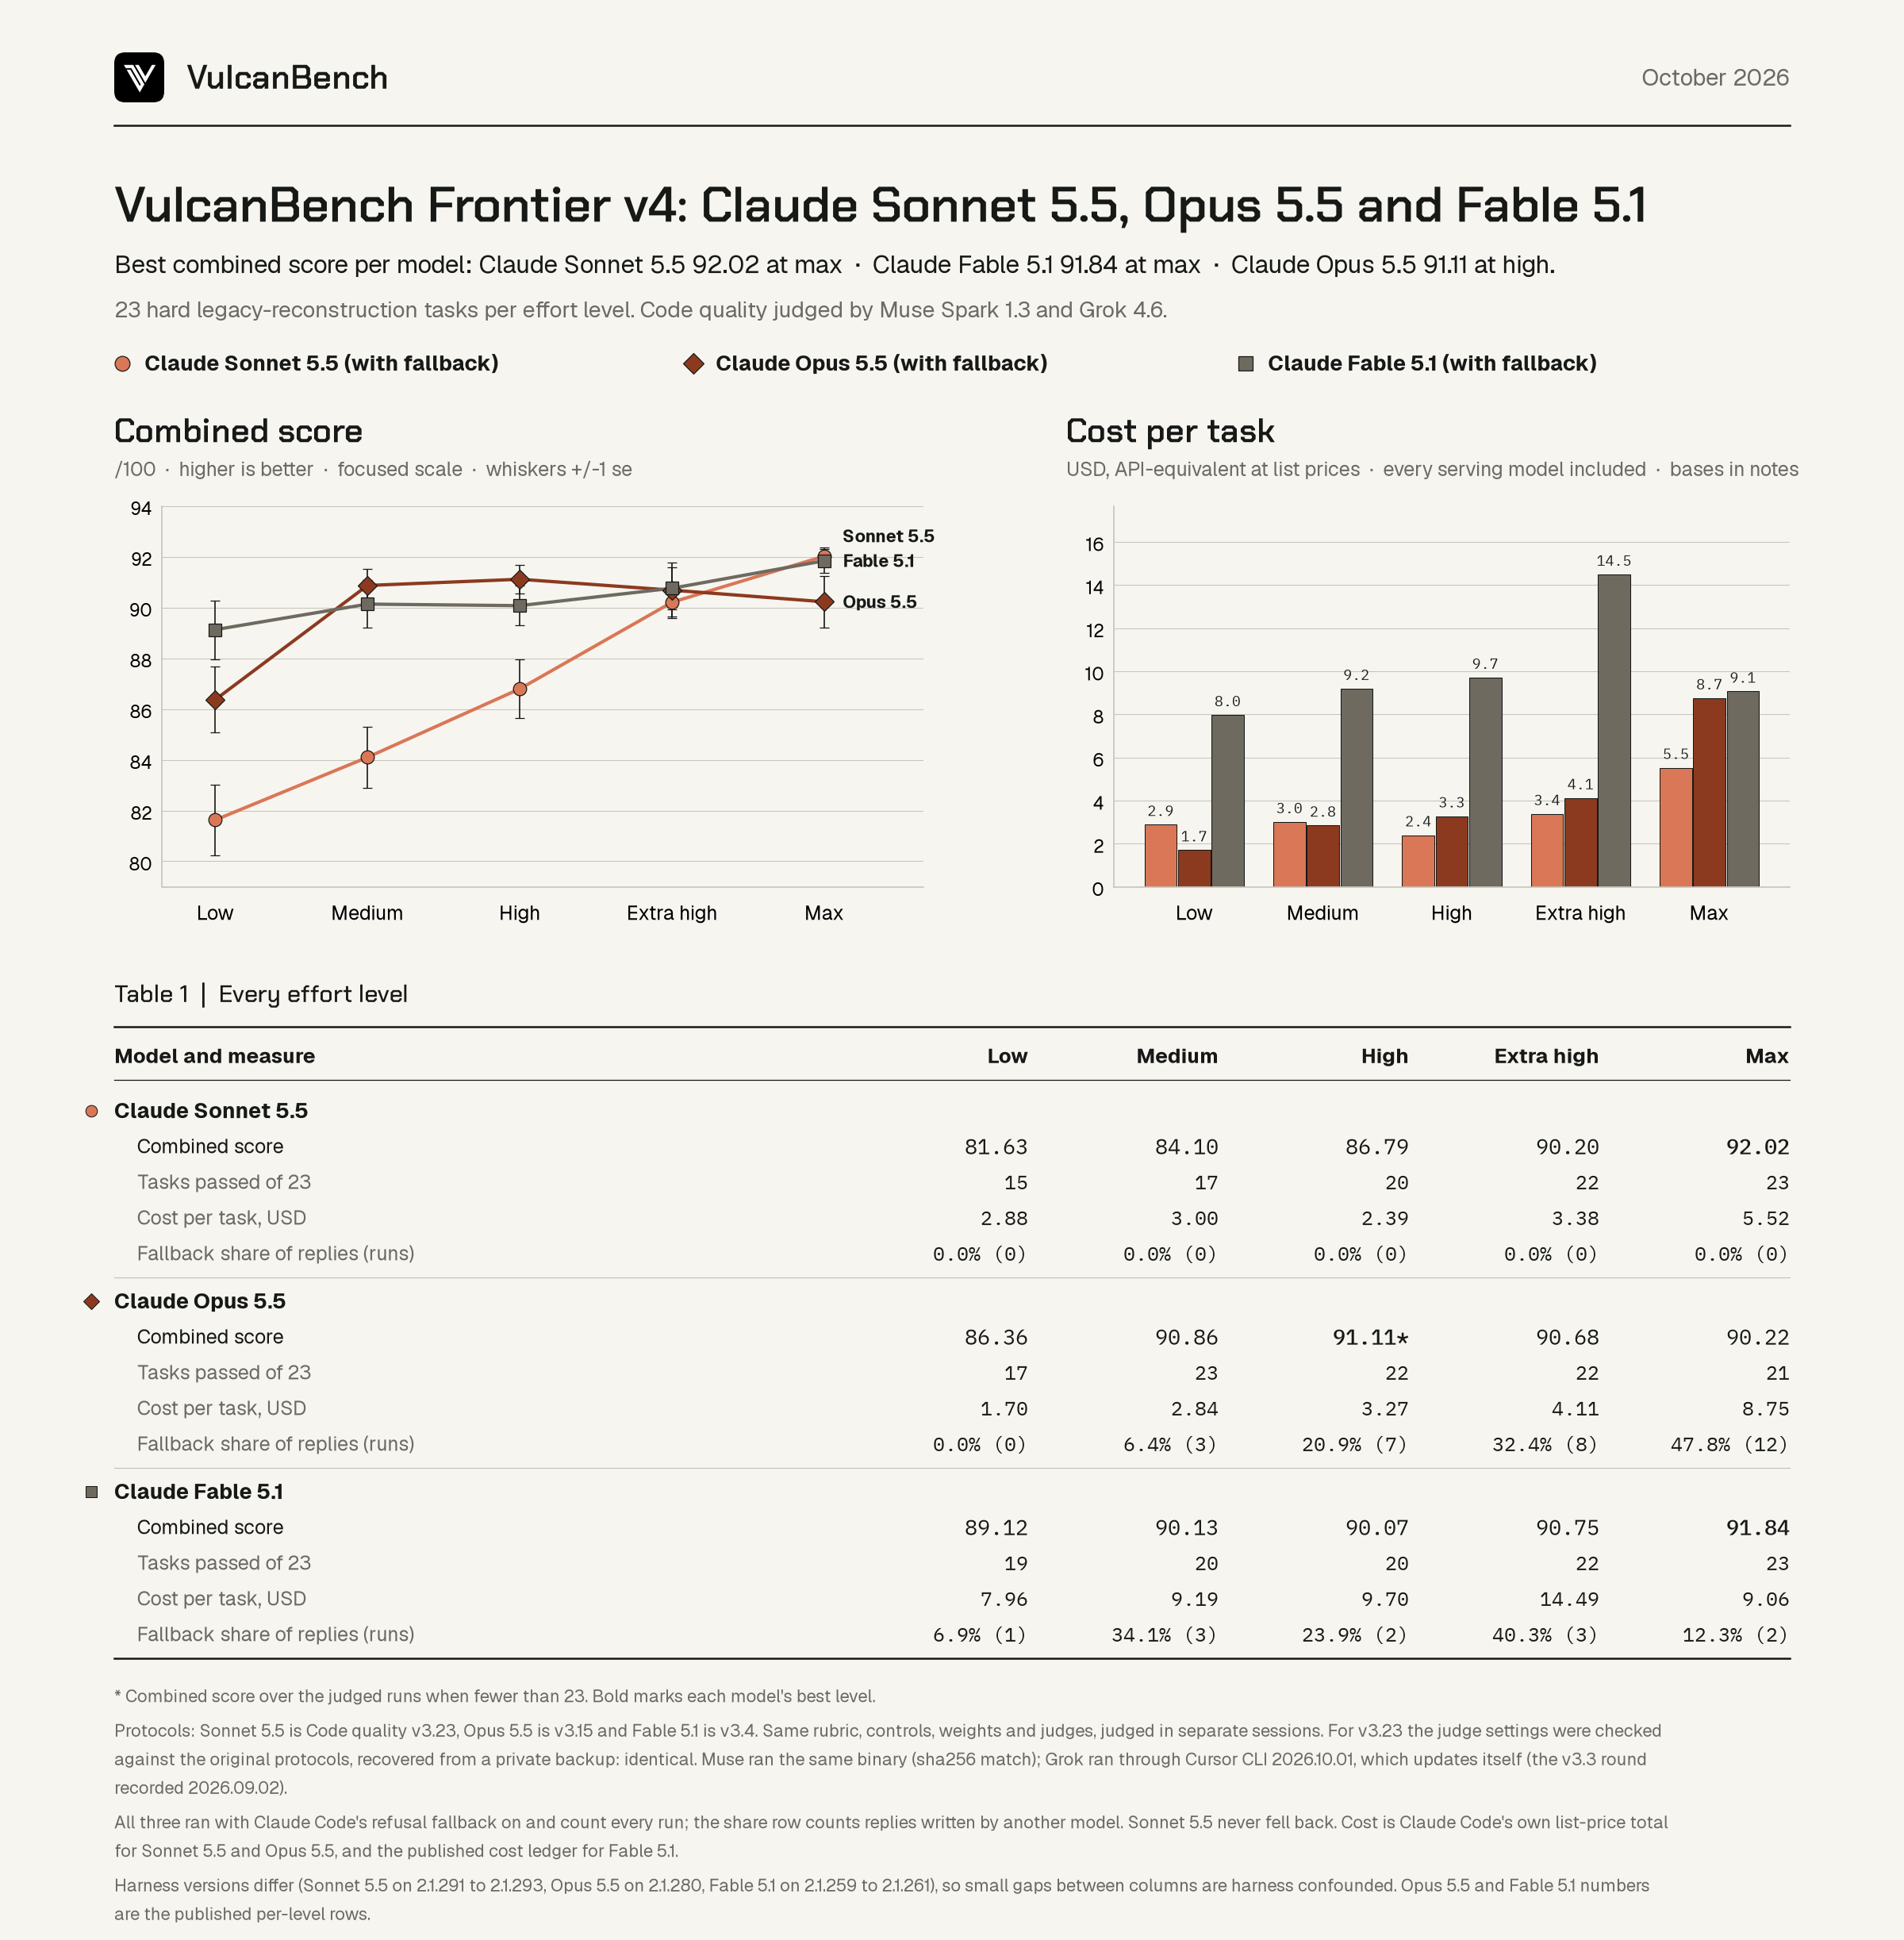
Opus 5.5 and Fable 5.1 ran the same 23 tasks through Claude Code in September, judged by the same two judges under v3.15 and v3.4. Their numbers are the published rows; nothing was re-judged. Sonnet 5.5 scores below both from Low to High (81.63, 84.10 and 86.79, against 86.36 to 91.11 for Opus 5.5 and 89.12 to 90.13 for Fable 5.1), within about half a point of both at Extra-high (90.20), and highest of the three at Max: 92.02 ± 0.35, against 90.22 ± 1.02 for Opus 5.5 and 91.84 ± 0.47 for Fable 5.1, the last within one standard error. Its Code quality climbs from 61.67 at Low, below both, to 81.72 at Max, between Opus 5.5 (79.77) and Fable 5.1 (82.43). On correctness Sonnet 5.5 passes fewer tasks than Opus 5.5 from Low to High (15, 17 and 20 against 17, 23 and 22), the same at Extra-high (22) and more at Max (23 against 21). It costs 23% to 61% of Fable 5.1’s price per task and is faster than Fable 5.1 from Low to Extra-high, though slower at Max (38.0 against 27.1 minutes). Against Opus 5.5 it costs more per task at Low and Medium and less from High up.
| Metric | Low | Medium | High | Extra-high | Max |
|---|---|---|---|---|---|
| Combined, Sonnet 5.5 | 81.63 | 84.10 | 86.79 | 90.20 | 92.02 |
| Combined, Opus 5.5 | 86.36 | 90.86 | 91.11 | 90.68 | 90.22 |
| Combined, Fable 5.1 | 89.12 | 90.13 | 90.07 | 90.75 | 91.84 |
| Tasks passed, Sonnet 5.5 | 15/23 | 17/23 | 20/23 | 22/23 | 23/23 |
| Tasks passed, Opus 5.5 | 17/23 | 23/23 | 22/23 | 22/23 | 21/23 |
| Tasks passed, Fable 5.1 | 19/23 | 20/23 | 20/23 | 22/23 | 23/23 |
| Code quality, Sonnet 5.5 | 61.67 | 65.35 | 70.84 | 75.78 | 81.72 |
| Code quality, Opus 5.5 | 72.53 | 77.32 | 77.99 | 79.98 | 79.77 |
| Code quality, Fable 5.1 | 78.36 | 80.14 | 80.86 | 81.93 | 82.43 |
| $ per task, Sonnet 5.5 | $2.88 | $3.00 | $2.39 | $3.38 | $5.52 |
| $ per task, Opus 5.5 | $1.70 | $2.84 | $3.27 | $4.11 | $8.75 |
| $ per task, Fable 5.1 | $7.96 | $9.19 | $9.70 | $14.49 | $9.06 |
| Minutes per task, Sonnet 5.5 | 20.0 | 20.8 | 14.8 | 21.6 | 38.0 |
| Minutes per task, Opus 5.5 | 13.7 | 18.6 | 21.4 | 20.7 | 37.5 |
| Minutes per task, Fable 5.1 | 26.9 | 31.7 | 28.8 | 38.8 | 27.1 |
For Sonnet 5.5 beside Opus 5.5 and GPT-6.1 Sol, the comparison most readers want, see Claude Sonnet 5.5 vs Claude Opus 5.5 vs GPT-6.1 Sol.
Opus 5.5’s tasks passed and minutes cover all 23 runs at every level, as in its report; its High combined score and Code quality cover 22 judged runs. Fable 5.1’s cost is its published v3.4 figure.
On the Frontier v4 board
Sonnet 5.5’s best level, Max at 92.02, ranks 4th of the board’s 58 model and effort columns, behind only Grok 4.7’s three top levels, which are judged by a different panel (Muse Spark 1.3 and GPT-6.1 Sol). Among columns judged by Muse Spark 1.3 and Grok 4.6 it is the highest point estimate: 0.18 points above Fable 5.1 at Max (91.84 ± 0.47), well within one standard error, and 0.91 above Opus 5.5 at High (91.11 ± 0.57, judged on 22 runs), about 1.4 combined standard errors: an edge, not a clear win. Extra-high ranks 11th, High 27th, Medium 35th and Low 39th. The leaderboard carries every column; Sonnet 5.5’s cells carry the †† footnote with the disclosures below.
Max passes every hidden test on every task, 23 of 23 tasks and all 231 tested behaviours, so Frontier v4 no longer separates Sonnet 5.5 at Max on correctness; Code quality, the lint and security scans, and cost still do. The harness’s integrity audit is clean on all 115 runs: no web access, and no reads of benchmark data or answer-key paths.
What Code quality measures
Every judge receives the same rubric, frozen by hash before any review. It names the reader it scores for: an engineer who has never seen the code, reads it top to bottom without running it, and must make a correct change in one sitting. It tells the judge that its own ease at parsing dense code is not evidence of readability. Six dimensions are scored 0 to 4 in half steps against written anchors: naming, presentation and intent form the human readability sub-score; structure, changeability and verifiability form the maintainability sub-score. Every score must cite an exact excerpt from the code and a concrete consequence for that reader. The host computes the sub-scores; the judge does no arithmetic.
The 33 points have three designed layers. The reviewed panel carries 24 points. An intent-recovery probe carries 9: the judge, given only the specification and the code, lists where the code departs from the specification, and a separate call matches that list against a frozen answer key, over the departures the submission passed tests for. The third layer, measured maintenance, is designed for 12 points but is not yet built, so the pre-registered 24 plus 9 split is in force. Frontier Code quality is therefore the reviewed layer plus intent recovery, and it is never compared with Routine v1 Code quality, which is scored on a different suite and population.
| Component | Low | Medium | High | Extra-high | Max |
|---|---|---|---|---|---|
| Code quality | 61.67 | 65.35 | 70.84 | 75.78 | 81.72 |
| Human readability | 53.4 | 54.4 | 65.9 | 72.2 | 79.5 |
| Maintainability | 64.9 | 68.7 | 75.1 | 78.0 | 84.1 |
| Intent recovery | 68.4 | 75.5 | 71.8 | 77.6 | 81.4 |
| Rated by Muse Spark 1.3 | 56.1 | 60.4 | 69.7 | 74.4 | 81.5 |
| Rated by Grok 4.6 | 62.2 | 62.7 | 71.3 | 75.8 | 82.2 |
| Standard error of Code quality | 2.08 | 1.66 | 1.57 | 1.28 | 0.99 |
Both sub-scores rise with effort, human readability from 53.4 to 79.5 and maintainability from 64.9 to 84.1, and readability is the weaker of the two at every level. Grok 4.6 rates higher than Muse Spark 1.3 at every level, by 6.2 points at Low narrowing to 0.6 at Max. Per-run sub-scores from each judge are in runs.csv; the exact rubric, system text, probe and match instructions are in judge-protocols.json.
Judges and calibration
The scored panel is Muse Spark 1.3 (Meta) through the Muse CLI on its Standard tier, and Grok 4.6 (xAI) through the Cursor CLI at medium effort, with equal weight. Neither lab has a model on this board, so neither judge grades a relative, and both are neutral for an Anthropic submission. Every session is fresh, tools are disabled, the workspace is empty, model identity is checked per call from the CLI’s own records, and solver labels are withheld. Protocol v3.23 changes nothing in the rubric, controls, quirk keys, gates, repeats, seed, weights or judge settings from v3.15; it applies the protocol to this population, and both judges retook the calibration exam under it before any counted call.
Judge settings and versions. The original v3.3 and v3.4 judge protocol files were recovered from the owner’s private backup, and their sha256 equal the published values (v3.3 b82da598, v3.4 1d80e097). The judge settings used in v3.23 are identical to them. Muse Spark 1.3 ran the same binary as every earlier round (sha256 match). Grok 4.6 ran on a newer Cursor CLI: the Cursor “pin” hashes only Cursor’s launcher script, which is the same in every Cursor release, so it never fixed the version. Cursor updated itself on October 7 at 14:43 PDT, and every v3.23 Grok call ran on Cursor CLI 2026.10.01-e373342, while the v3.3 round recorded 2026.09.02-c22c1a3. The Grok model id (cursor-grok-4.6-medium) is the same. Its display name changed: since September 21 Cursor reports “Grok 4.6 Medium” where the frozen settings say “Cursor Grok 4.6 Medium”, a rename the judging wrapper accepts and records (439 times in this round). Grok 4.6 passed calibration under v3.23, below.
Before scoring a single submission, each judge reviews ten held-out programs that implement the same ledger specification: clear, compressed, compressed then auto-formatted, verbose with duplicated policy, needlessly abstracted, misleadingly commented, narrated with a comment on every line, a documented legacy quirk, an embedded instruction to give full marks, and hidden module state. Each program is reviewed five times in a seeded order. Twenty gates fixed in advance check that the judge sees the construct; a judge may miss at most one gate by at most half a point.
| Judge | Protocol | Calls | Result | Allowance used | Failing gates |
|---|---|---|---|---|---|
| Muse Spark 1.3 | code-quality-maintenance-v3.23 | 80 | passed | yes | g11_repeatability, short by 0.02 |
| Grok 4.6 | code-quality-maintenance-v3.23 | 80 | passed | yes | g04_formatting_is_presentation, short by 0.10 |
Both judges passed, each using the protocol’s one-gate allowance: Muse Spark 1.3 missed only the repeatability gate and Grok 4.6 only the formatting-is-presentation gate, both well inside the half-point limit. Under v3.15, for Opus 5.5, both passed every gate with no allowance used. Every gate value and control mean is in calibration.json.
Under v3.23 each judge made 440 (80 in calibration, 115 primary reviews, 5 repeats, 10 pairwise checks, 115 intent probes and 115 answer-key matches) counted calls. Muse needed a second attempt on ten calls and Grok on two, under the protocol’s single-retry rule, and no call was marked invalid. One Grok review was recovered by a standing operator rule: on Medium lodgecore both attempts failed only because a quoted code line is hard-wrapped in the source, so the wrapper selected attempt 1 with the quote re-wrapped to the source’s line breaks; scores are untouched and the original quote is kept in the receipt. Neither judge produced a reviewer fallback. Every attempt is archived beside its replacement in the harness run directory.
How it was run
- Before the tagged-worktree rule. The Sonnet 5.5 sweep was launched on October 6 from a checkout that predates the harness’s October 5 rule that every sweep runs from a tagged worktree. Its run summaries therefore carry no source block, and their recorded task hashes use an older format that counted
__pycache__files. Task content was verified identical to the frozen suite lock. Judging admitted the runs through a committed hash bridge (harness repodocs/judging/task-hash-bridge-sonnet55.json), which pairs each task’s recorded hash with its lock hash, both computed on the same unchanged directories. All 107 cached.pycfiles an agent could see were byte-identical to compiling the starting source, so the extra files revealed nothing. The owner chose to publish with this disclosure rather than rerun. - Claude Code versions. Claude Code updated itself during the sweep. From each run’s own start-up record: Low ran 21 tasks on 2.1.291 and 2 on 2.1.292; Medium and High ran on 2.1.292; Extra-high ran 22 tasks on 2.1.292 and its last, paddockcore, on 2.1.293; Max ran on 2.1.293. Earlier Claude columns used older Claude Code releases (Opus 5.5 on 2.1.280, Fable 5.1 on 2.1.259 to 2.1.261).
- Refusal fallback on, never used. Claude Code’s refusal fallback stayed at its default (on), as for Opus 5.5, following Artificial Analysis’s Default Fallback convention. No run used it: every reply in every run came from
claude-sonnet-5-5. - Where and how.
--billing subscriptionon a Claude Max plan, the local sandbox on the owner’s Mac (the same host as every published Frontier v4 column), a flat 3-hour task timeout, one task at a time. The sweep ran October 6, 06:49 PDT, to October 8, 03:38 PDT. - Judging window. Judging under v3.23 began October 8 at 05:02 PDT and finished at 18:02 PDT the same day, in one window with no stops. The Claude Haiku 5.5 solver sweep, queued behind this one, started at 03:40 PDT on October 8, after the last Sonnet 5.5 run had finished, and ran on the same machine during judging; it does not touch Sonnet 5.5’s runtime figures, and judge timing is not scored.
- One attempt per task and level. Runs were not repeated, no run was retried, and effort labels are Claude Code’s own.
Evidence and reproduction
Public files contain all 115 run measurements, both judges’ six-dimension sub-scores and intent-recovery scores per run, hidden behaviours fixed, integrity-audit verdicts, each run’s task hash bridge pair, Claude Code version, replies by serving model, raw tokens and cost, five aggregates, every calibration gate value, the exact judge protocol text, the judge settings and version record and source hashes. Each run’s Code quality is (0.24 × reviewed score + 0.09 × intent recovery) / 0.33, where both terms are the equal mean of the two judges. The combined score is 100 × (0.50F + 0.085Q + 0.085S + 0.33C / 100). The reproduction guide gives the public arithmetic checks and links the protocol documents, the hash bridge, the judge settings file and the decision record.
No human rated anything; the scores are model judgment for a human reader, not human validation. Hash checks bind the export to frozen files; they do not prove that judges were unbiased or that no training overlap exists.
Withheld: raw prompts and responses, submitted patches and reconstructed sources, the quirk answer keys (they describe hidden-test behaviour), reviewer session identifiers and usage receipts, and host binary paths. Summed solver time is 44.15 hours; judging is excluded.