November 19, 2026 · Morgan Linton · 115 runs · Code quality protocol v3.31
GPT-6.2 Sol across every effort level
115 runs of OpenAI’s GPT-6.2 Sol (gpt-6.2-sol) through the Codex CLI on a ChatGPT subscription, 23 tasks at each of five effort levels, Low to Max, on the model’s release day and the day after. GPT-6.2 Sol is the fourth Sol on the board, after GPT-5.6 Sol, GPT-6 Sol and GPT-6.1 Sol. Code quality carries 33% of the combined score and is judged for a human reader by Muse Spark 1.3 and Grok 4.6, the panel that judged GPT-6.1 Sol, GPT-6.1 Terra and Claude Opus 5.5, so GPT-6.2 Sol takes its place on the Frontier v4 leaderboard beside them. Every run passed every hidden test and finished inside the 3-hour task bound, and every cell is judged on all 23 runs, one of them by one judge, as described under the results table.
How the test works
A retired program to rebuild
Each of the 23 tasks is a legacy binary with a written specification and an issue. Its real behaviour departs from the specification in documented ways, and hidden tests check the rewrite against the binary.
One attempt per task and level
GPT-6.2 Sol works in Codex with the binary, the specification and the code, once per task at each effort level, inside a flat 3-hour bound, one task at a time.
Tests and two judges score it
Hidden tests give functional correctness. Two calibrated judges from labs other than OpenAI rate the code for a human reader and try to recover the documented departures.
Scores, time and cost per level
Each level gets a combined score, tasks passed, minutes and API-equivalent cost at OpenAI’s list price.
Combined score = 50% functional correctness + 8.5% lint and complexity + 8.5% security + 33% Code quality, averaged over the 23 runs in each level, as on every other board column. Frontier Code quality is the reviewed layer plus intent recovery; it is never compared with Routine v1 Code quality.
Across every effort level
GPT-6.2 Sol ran every task once at each of the five effort levels Codex offers for it (Extra-high is Codex’s xhigh), 23 tasks per cell, through Codex CLI 0.166.0 on a ChatGPT subscription from November 18, 2026, 00:34 UTC, to 12:44 UTC the same day, starting on the evening of OpenAI’s November 17 release in Pacific time, on the owner’s Mac, one task at a time. Combined score weights are 50% functional correctness, 8.5% lint and complexity, 8.5% security and 33% Code quality, judged for a named human reader by Muse Spark 1.3 and Grok 4.6 with a ground-truth intent-recovery probe. No run reached the flat 3-hour task bound; the longest, Extra-high lodgecore, took 23.6 minutes. All 115 runs carry a published Code quality score.
Combined score
88.44 at Low to 89.01 at Extra-high
The score is nearly flat: 88.44 at Low, 88.94 at Medium, 88.86 at High, 89.01 at Extra-high and 88.74 at Max. The whole spread, 0.57 points, is about one standard error, so effort barely moves the score.
Tasks passed
23 of 23 at every level
GPT-6.2 Sol fully solves every task at every level and fixes all 231 hidden behaviours the tasks test for, in all 115 runs. With functional correctness at 100 everywhere, the differences between levels come from Code quality, lint and security.
Code quality
70.31 to 71.91
The judges rate the code 70.31 at Low, 71.78 at Medium, 71.43 at High, 71.91 at Extra-high and 71.06 at Max, with standard errors of 0.89 to 1.21: also flat, within about one and a half points.
Runtime and cost
2.8 to 11.3 min · $0.23 to $0.55 per task
Effort buys time and tokens, not score. Max takes four times as long as Low and costs about two and a half times as much. The whole sweep took 12.2 hours of solver time and prices at $45.38 for 115 runs, $0.39 per task, at GPT-6.2 Sol’s list rates.
| Metric | Low | Medium | High | Extra-high | Max |
|---|---|---|---|---|---|
| Combined score | 88.44 | 88.94 | 88.86 | 89.01 | 88.74 |
| Standard error | 0.35 | 0.47 | 0.33 | 0.43 | 0.40 |
| Judged runs | 23 | 23 | 23 | 23 | 23 |
| Tasks passed | 23/23 | 23/23 | 23/23 | 23/23 | 23/23 |
| Hidden behaviours fixed | 231/231 | 231/231 | 231/231 | 231/231 | 231/231 |
| Code quality | 70.31 | 71.78 | 71.43 | 71.91 | 71.06 |
| Human readability | 60.5 | 63.4 | 63.0 | 64.8 | 63.4 |
| Minutes per task | 2.8 | 4.4 | 5.1 | 8.2 | 11.3 |
| API-equivalent $ per task | $0.23 | $0.33 | $0.41 | $0.46 | $0.55 |
Under the prior 50/15/15/20 profile applied to the same Code quality scores the ladder is just as flat, 90.95 to 91.34. The card and the full per-effort table follow.
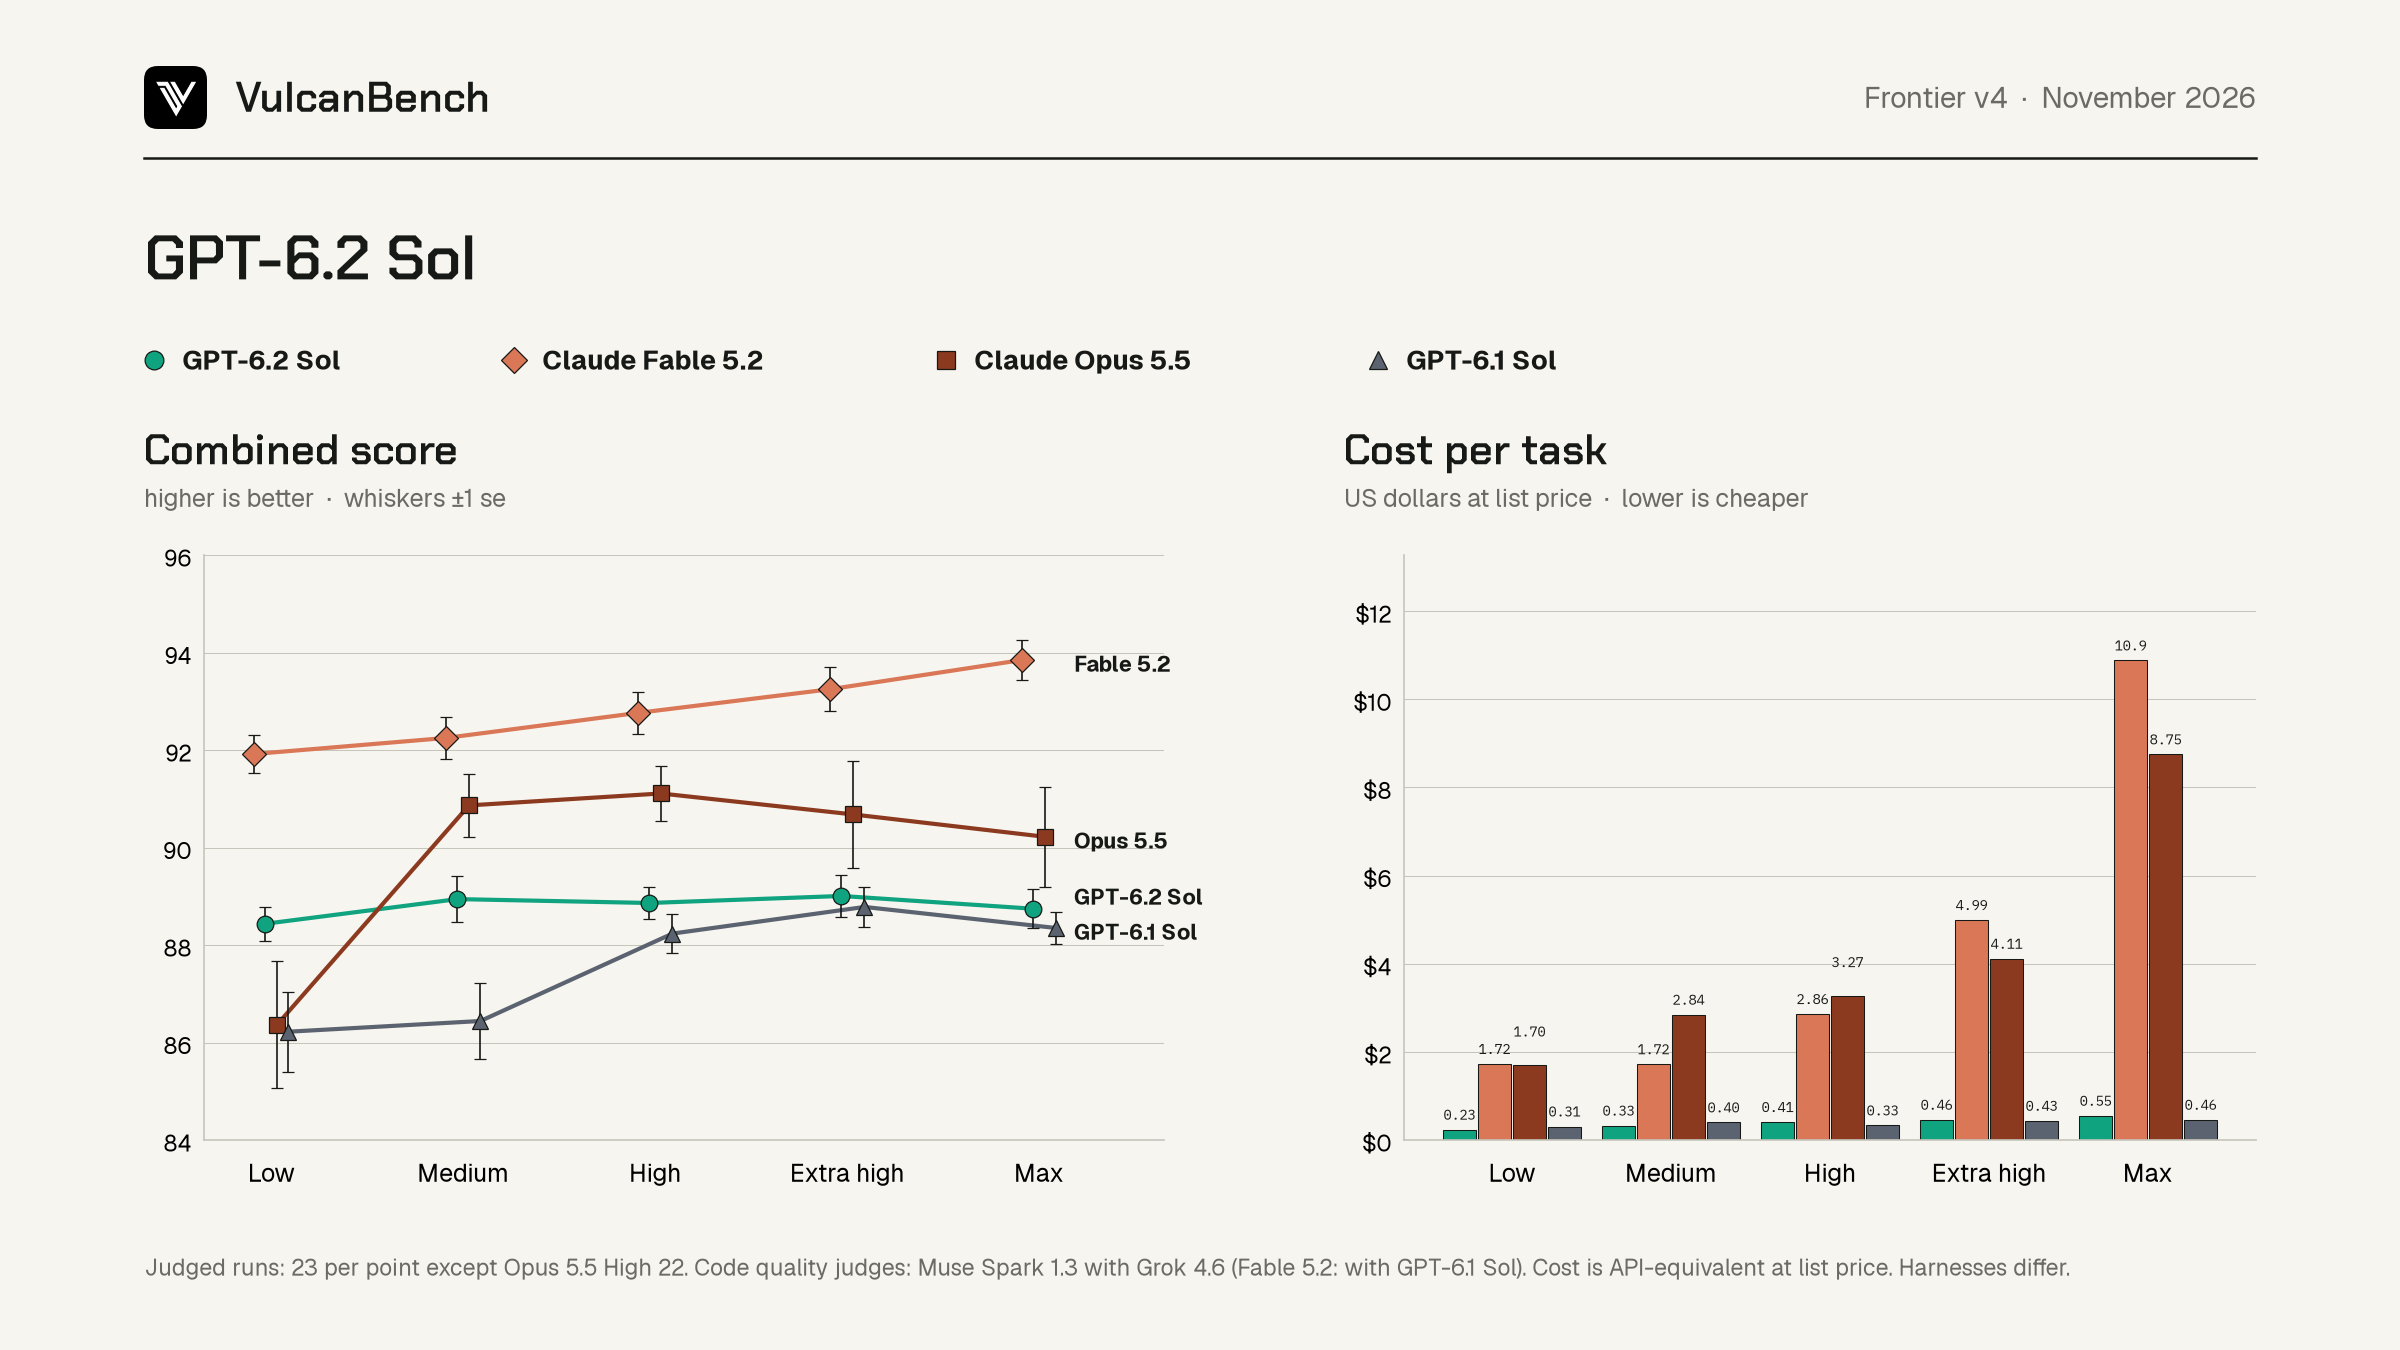
GPT-6.2 Sol is a model to run at Low. It solves every task at every level, so effort changes almost nothing but the bill: Low scores 88.44 against a best of 89.01 at Extra-high, at $0.23 a task and 2.8 minutes against $0.46 and 8.2 minutes. Against GPT-6.1 Sol it is better where GPT-6.1 Sol was weakest, Low and Medium, and level with it above. It stays about 3 to 5 points behind Claude Fable 5.2 and 2 points behind Claude Opus 5.5 from Medium up, at a fraction of their cost. These runs compare a model-and-harness combination, not an isolated base model; the Frontier v4 leaderboard places every GPT-6.2 Sol level beside the other models.
Combined score and Code quality by effort
n=23 at every level. Combined (33%) is the published score. Combined (20% profile) applies the prior 50/15/15/20 weights to the same Code quality scores for comparison. Code quality, human readability, maintainability and intent recovery are out of 100 and equal means of the two judges (Muse alone for Low granarycore). Passed counts all 23 runs. Runtime is solver wall-clock per task over every run in the cell.
| Model / harness | Effort | Combined (33%) | SE | Combined (20% profile) | Code quality | Human readability | Maintainability | Intent recovery | Judged | Passed | Min/task |
|---|---|---|---|---|---|---|---|---|---|---|---|
| GPT-6.2 Sol / Codex | Low | 88.44 | 0.35 | 90.95 | 70.31 | 60.5 | 73.0 | 79.8 | 23/23 | 23/23 | 2.8 |
| GPT-6.2 Sol / Codex | Medium | 88.94 | 0.47 | 91.27 | 71.78 | 63.4 | 73.5 | 80.7 | 23/23 | 23/23 | 4.4 |
| GPT-6.2 Sol / Codex | High | 88.86 | 0.33 | 91.27 | 71.43 | 63.0 | 72.5 | 81.4 | 23/23 | 23/23 | 5.1 |
| GPT-6.2 Sol / Codex | Extra-high | 89.01 | 0.43 | 91.34 | 71.91 | 64.8 | 73.6 | 79.1 | 23/23 | 23/23 | 8.2 |
| GPT-6.2 Sol / Codex | Max | 88.74 | 0.40 | 91.20 | 71.06 | 63.4 | 72.6 | 79.3 | 23/23 | 23/23 | 11.3 |
Low granarycore is scored by one judge. Grok 4.6’s primary review of Low granarycore quoted code the submission does not contain, on both of its two attempts (one quote with a bracket in the wrong place, one with a variable renamed). The operator rule invalidate_unrecoverable_primary, the owner’s precedent from September 23, marks such a review invalid, and the frozen summary then scores the run’s reviewed layer and intent recovery from Muse Spark 1.3 alone, as it does for any submission without two valid reviews; GPT-6.1 Sol’s Medium paddockcore was published the same way. Granarycore scores 85.62, with Code quality 65.50. Every other run is the equal mean of both judges.
Four factors by effort. Functional correctness is 100.00 at every level; lint and complexity average 79.45, 79.67, 79.86, 80.37 and 79.91 from Low to Max; security 99.78, 99.78, 100.00, 99.35 and 100.00. Only the Code quality factor depends on the judges, and it moves by less than two points.
Intent recovery is scored over the specification departures a submission actually passed tests for. Every run passed at least one quirk family, so no run needed its intent points moved to the reviewed score. SE is one sample standard error of the combined score across the cell’s tasks. It describes task sampling, not judge uncertainty, repeated runs or a significance test. No solver fallback occurred, and neither judge produced a reviewer fallback on any of the 115 submissions.
Beside Claude Fable 5.2, Claude Opus 5.5 and GPT-6.1 Sol
Claude Fable 5.2, first on the board, is ahead at every level: 91.92 to 93.85 against GPT-6.2 Sol’s 88.44 to 89.01, a gap of 3.3 to 5.1 points that widens with effort. Claude Opus 5.5 is ahead by about 2 points from Medium to Max (90.22 to 91.11) and behind at Low (86.36), where it passes 17 tasks. GPT-6.2 Sol passes all 23 at every level, as Fable 5.2 does; Opus 5.5 passes 17 to 23, and GPT-6.1 Sol 20 to 23.
The Claude models cost far more. GPT-6.2 Sol costs $0.23 to $0.55 a task, against $1.72 to $10.88 for Fable 5.2 and $1.70 to $8.75 for Opus 5.5, so Fable 5.2’s lead costs 5 to 20 times as much per task. GPT-6.2 Sol is also the fastest of the four at every level but Medium, where Fable 5.2 is a tenth of a minute quicker (4.3 against 4.4).
| Model / harness | Effort | Combined | SE | Judged | Passed | Min/task | Tokens/task | $/task | Code quality |
|---|---|---|---|---|---|---|---|---|---|
| GPT-6.2 Sol / Codex | Low | 88.44 | 0.35 | 23 | 23/23 | 2.8 | 0.77M | $0.23 | 70.31 |
| Claude Fable 5.2 / Claude Code | Low | 91.92 | 0.39 | 23 | 23/23 | 4.6 | 0.65M | $1.72 | 80.63† |
| Claude Opus 5.5 / Claude Code | Low | 86.36 | 1.30 | 23 | 17/23 | 13.7 | 2.77M | $1.70 | 72.53 |
| GPT-6.1 Sol / Codex | Low | 86.22 | 0.82 | 23 | 20/23 | 6.9 | 1.24M | $0.31 | 70.79 |
| GPT-6.2 Sol / Codex | Medium | 88.94 | 0.47 | 23 | 23/23 | 4.4 | 1.05M | $0.33 | 71.78 |
| Claude Fable 5.2 / Claude Code | Medium | 92.25 | 0.44 | 23 | 23/23 | 4.3 | 0.59M | $1.72 | 81.49† |
| Claude Opus 5.5 / Claude Code | Medium | 90.86 | 0.64 | 23 | 23/23 | 18.6 | 5.01M | $2.84 | 77.32 |
| GPT-6.1 Sol / Codex | Medium | 86.44 | 0.78 | 23 | 22/23 | 10.6 | 1.62M | $0.40 | 70.25 |
| GPT-6.2 Sol / Codex | High | 88.86 | 0.33 | 23 | 23/23 | 5.1 | 1.30M | $0.41 | 71.43 |
| Claude Fable 5.2 / Claude Code | High | 92.76 | 0.43 | 23 | 23/23 | 7.8 | 1.19M | $2.86 | 82.95† |
| Claude Opus 5.5 / Claude Code | High | 91.11 | 0.57 | 22* | 22/23 | 21.4 | 4.11M | $3.27 | 77.99 |
| GPT-6.1 Sol / Codex | High | 88.23 | 0.40 | 23 | 23/23 | 10.2 | 0.91M | $0.33 | 73.67 |
| GPT-6.2 Sol / Codex | Extra-high | 89.01 | 0.43 | 23 | 23/23 | 8.2 | 1.31M | $0.46 | 71.91 |
| Claude Fable 5.2 / Claude Code | Extra-high | 93.25 | 0.45 | 23 | 23/23 | 14.2 | 2.51M | $4.99 | 84.25† |
| Claude Opus 5.5 / Claude Code | Extra-high | 90.68 | 1.10 | 23 | 22/23 | 20.7 | 3.90M | $4.11 | 79.98 |
| GPT-6.1 Sol / Codex | Extra-high | 88.78 | 0.40 | 23 | 23/23 | 15.4 | 1.12M | $0.43 | 74.99 |
| GPT-6.2 Sol / Codex | Max | 88.74 | 0.40 | 23 | 23/23 | 11.3 | 1.31M | $0.55 | 71.06 |
| Claude Fable 5.2 / Claude Code | Max | 93.85 | 0.42 | 23 | 23/23 | 37.1 | 7.91M | $10.88 | 86.02† |
| Claude Opus 5.5 / Claude Code | Max | 90.22 | 1.02 | 23 | 21/23 | 37.5 | 8.72M | $8.75 | 79.77 |
| GPT-6.1 Sol / Codex | Max | 88.35 | 0.33 | 23 | 23/23 | 14.5 | 1.04M | $0.46 | 73.80 |
Read the comparison with its limits. † Claude Fable 5.2 is judged by Muse Spark 1.3 and GPT-6.1 Sol (v3.30.2 and v3.30.3), because Grok 4.6 failed its exam in that round; GPT-6.1 Sol rates reviewed Code quality several points above Muse, so Fable 5.2’s Code quality and combined score are not strictly comparable with the Muse and Grok columns. By Muse Spark 1.3 alone, the one judge all four columns share, Fable 5.2 scores 91.09 to 92.78 and GPT-6.2 Sol 87.75 to 88.65, so Fable 5.2 stays ahead. * Opus 5.5 at High is judged on 22 runs, where a safeguard stop left one run with no code to review. GPT-6.2 Sol, Opus 5.5 and GPT-6.1 Sol are judged by Muse Spark 1.3 and Grok 4.6 under the same rubric, each in its own protocol run (v3.31, v3.15 and v3.18). Harnesses differ: Claude Code for the Claude models, Codex for the two Sols. $/task is API-equivalent at list price from each run’s receipts; for the Claude models it is Claude Code’s own list-price total.
Against GPT-6.1 Sol
GPT-6.1 Sol ran the same 23 tasks through Codex in September and was judged by the same two judges under v3.18, at the same list price ($2.00 input, $0.10 cached input and $10.00 output per million tokens). GPT-6.2 Sol scores higher at every level, by 2.21 points at Low, 2.50 at Medium, 0.63 at High, 0.23 at Extra-high and 0.40 at Max: the gain is at the low levels, where GPT-6.1 Sol missed tasks (it passed 20 and 22 at Low and Medium) and GPT-6.2 Sol passes all 23. From High up the two are level within a standard error. GPT-6.2 Sol is faster at every level, 2.8 to 11.3 minutes a task against 6.9 to 15.4, and cheaper at Low and Medium ($0.23 and $0.33 against $0.31 and $0.40) but a little dearer from High up ($0.41 to $0.55 against $0.33 to $0.46), where it uses more tokens. Code quality is the one place it does not gain: 0.48 points lower at Low, 1.53 higher at Medium and 2.23 to 3.08 lower from High to Max.
| Metric | Low | Medium | High | Extra-high | Max |
|---|---|---|---|---|---|
| Combined, GPT-6.2 Sol | 88.44 | 88.94 | 88.86 | 89.01 | 88.74 |
| Combined, GPT-6.1 Sol | 86.22 | 86.44 | 88.23 | 88.78 | 88.35 |
| Tasks passed, GPT-6.2 Sol | 23/23 | 23/23 | 23/23 | 23/23 | 23/23 |
| Tasks passed, GPT-6.1 Sol | 20/23 | 22/23 | 23/23 | 23/23 | 23/23 |
| Code quality, GPT-6.2 Sol | 70.31 | 71.78 | 71.43 | 71.91 | 71.06 |
| Code quality, GPT-6.1 Sol | 70.79 | 70.25 | 73.67 | 74.99 | 73.80 |
| $ per task, GPT-6.2 Sol | $0.23 | $0.33 | $0.41 | $0.46 | $0.55 |
| $ per task, GPT-6.1 Sol | $0.31 | $0.40 | $0.33 | $0.43 | $0.46 |
| Minutes per task, GPT-6.2 Sol | 2.8 | 4.4 | 5.1 | 8.2 | 11.3 |
| Minutes per task, GPT-6.1 Sol | 6.9 | 10.6 | 10.2 | 15.4 | 14.5 |
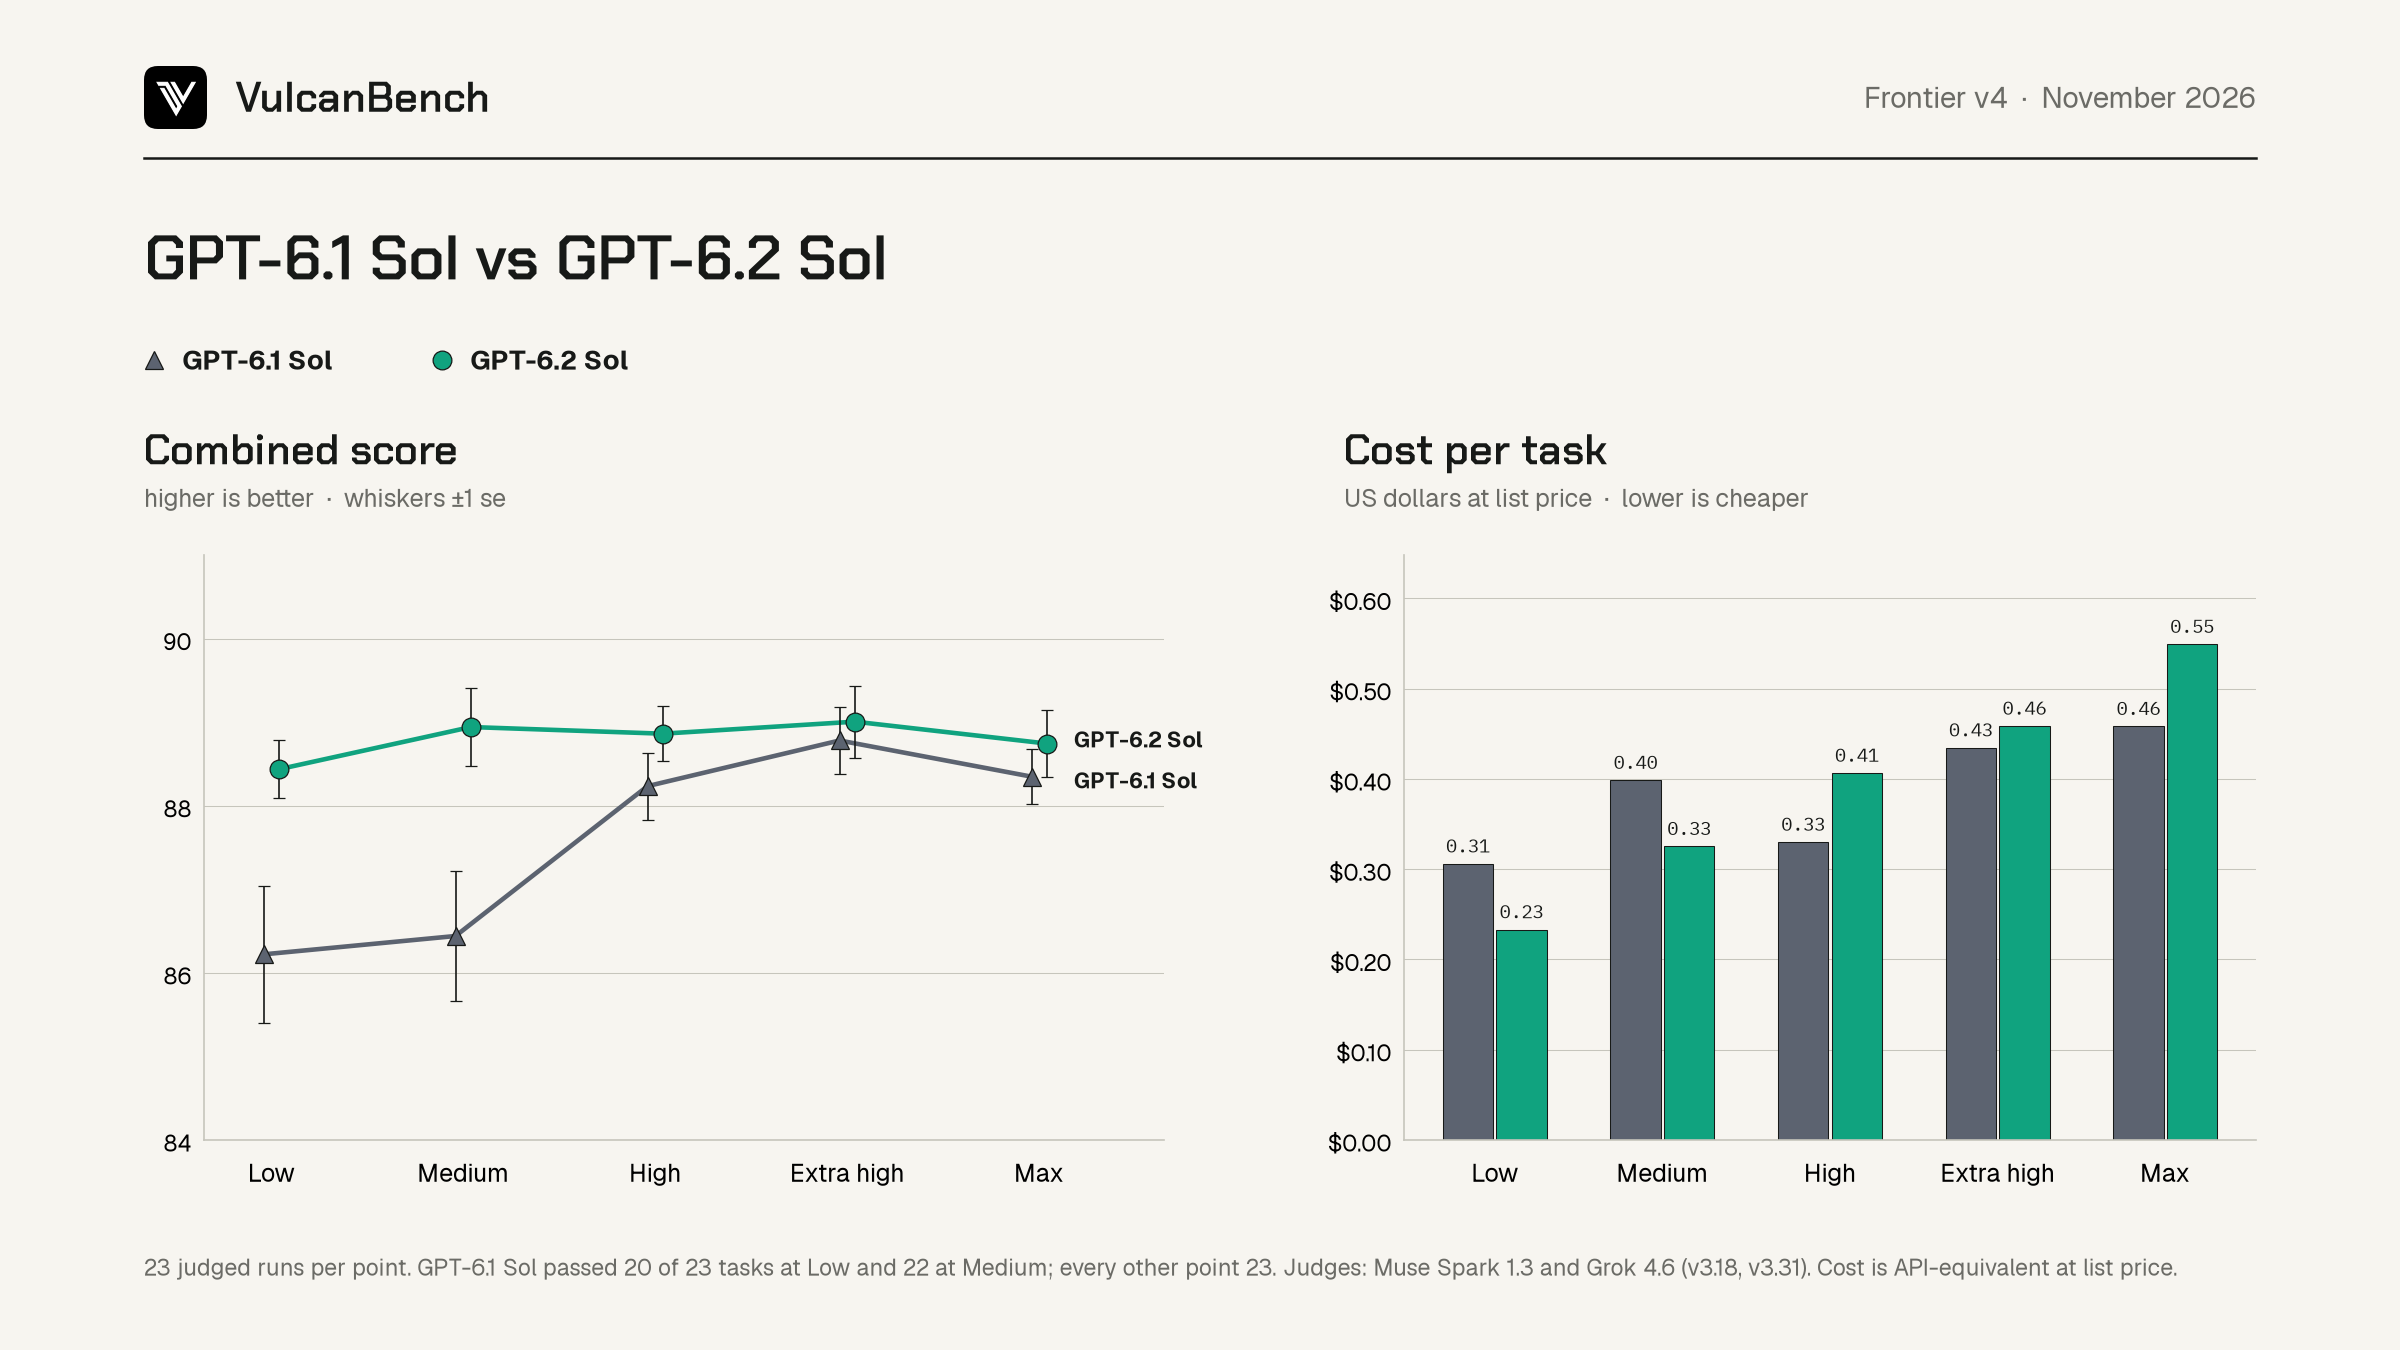
The two sweeps ran on different Codex CLI versions (0.166.0 and 0.159.0) two months apart, so read the speed figures with that in mind. GPT-6.1 Sol’s report has its full record.
Cost and tokens across effort levels
All 115 runs priced from their Codex receipts at list API rates, cache-aware, with judging excluded. These are API-equivalent estimates, not subscription charges: GPT-6.2 Sol ran on a ChatGPT subscription, and what the plan bills is not observable from the receipts. Cost per task is $0.23 at Low, $0.33 at Medium, $0.41 at High, $0.46 at Extra-high and $0.55 at Max; the whole sweep comes to $45.38. Effort shows up in reasoning: the median run spends 0.5K output tokens on reasoning at Low and 12.8K at Max, and mean output rises from 4.9K to 22.1K tokens a task, while total tokens level off at about 1.3M a task from High up.
| Effort | Runs | $/task | Level total | Tokens/task | Output/task | Median reasoning | Cached share of input | Min/task | Median min |
|---|---|---|---|---|---|---|---|---|---|
| Low | 23 | $0.23 | $5.36 | 0.77M | 4.9K | 0.5K | 90.8% | 2.8 | 2.3 |
| Medium | 23 | $0.33 | $7.48 | 1.05M | 7.8K | 1.7K | 91.8% | 4.4 | 4.0 |
| High | 23 | $0.41 | $9.35 | 1.30M | 11.1K | 3.8K | 92.1% | 5.1 | 5.2 |
| Extra-high | 23 | $0.46 | $10.55 | 1.31M | 13.9K | 5.7K | 91.4% | 8.2 | 7.4 |
| Max | 23 | $0.55 | $12.63 | 1.31M | 22.1K | 12.8K | 91.0% | 11.3 | 11.5 |
| Full sweep | 115 | $0.39 | $45.38 | 132M | 12.2 h |
Pricing. Rates checked 2026-11-17 from OpenAI: GPT-6.2 Sol at $2.00 input, $0.10 cached input and $10.00 output per million tokens, the same as GPT-6.1 Sol. Codex receipts report input, cached input, output and reasoning tokens per run, so cached input is billed at the cache-read rate and the rest at the standard rate; reasoning tokens are part of output and are not billed twice. Codex keeps each request within its context window, so no long-context premium is modelled. The sweep stamped each run at these rates at run time; the export recomputed every run from its receipt and matched every stamp.
Tokens are Codex’s raw totals, input (cached included) plus output; the full sweep row sums them over all 115 runs (Tokens/task in that row is the sweep total). Per-run estimates, token usage breakdowns and the rate table are in economics.json and runs.csv.
On the Frontier v4 board
GPT-6.2 Sol’s best level, Extra-high at 89.01 ± 0.43 (n=23), ranks 27th of the board’s 91 model and effort columns, just below GPT-5.6 Terra at Max (89.05) and three places above GPT-6.1 Sol’s best, Extra-high at 88.78. By level it ranks Low 34th, Medium 28th, High 29th, Extra-high 27th, Max 31st: all five levels sit within 0.6 points of each other. Of the 23 priced columns scoring 89 or more, GPT-6.2 Sol at Extra-high is the second cheapest, at $0.46 a task, after GPT-6.1 Terra at Max ($0.36). Extra-high carries the best tag, and the board’s critical, routine and rough effort suggestions all pick Low, because Low is within 0.6 points of the best for half the cost and a third of the time. The leaderboard carries every column; GPT-6.2 Sol’s Low cell carries the *** footnote with the one-judge disclosure on this page.
Read these placements with the panel in mind. GPT-6.2 Sol, Claude Opus 5.5, GPT-6.1 Sol and most other columns are judged by Muse Spark 1.3 and Grok 4.6; Claude Fable 5.2’s, Grok 4.7’s, DeepSeek V4.1 Flash’s and Reflection Beam’s by Muse Spark 1.3 and GPT-6.1 Sol; Muse Wonder Full’s by Claude Opus 5.5 and GPT-6.1 Sol. Scores from different panels are not calibrated against each other, so gaps of a point or two between columns judged by different panels are not a reliable order.
What Code quality measures
Every judge receives the same rubric, frozen by hash before any review. It names the reader it scores for: an engineer who has never seen the code, reads it top to bottom without running it, and must make a correct change in one sitting. It tells the judge that its own ease at parsing dense code is not evidence of readability. Six dimensions are scored 0 to 4 in half steps against written anchors: naming, presentation and intent form the human readability sub-score; structure, changeability and verifiability form the maintainability sub-score. Every score must cite an exact excerpt from the code and a concrete consequence for that reader. The host computes the sub-scores; the judge does no arithmetic.
The 33 points have three designed layers. The reviewed panel carries 24 points. An intent-recovery probe carries 9: the judge, given only the specification and the code, lists where the code departs from the specification, and a separate call matches that list against a frozen answer key, over the departures the submission passed tests for. The third layer, measured maintenance, is designed for 12 points but is not yet built, so the pre-registered 24 plus 9 split is in force. Frontier Code quality is therefore the reviewed layer plus intent recovery, and it is never compared with Routine v1 Code quality, which is scored on a different suite and population.
| Component | Low | Medium | High | Extra-high | Max |
|---|---|---|---|---|---|
| Code quality | 70.31 | 71.78 | 71.43 | 71.91 | 71.06 |
| Human readability | 60.5 | 63.4 | 63.0 | 64.8 | 63.4 |
| Maintainability | 73.0 | 73.5 | 72.5 | 73.6 | 72.6 |
| Intent recovery | 79.8 | 80.7 | 81.4 | 79.1 | 79.3 |
| Runs with no intent denominator | 0 | 0 | 0 | 0 | 0 |
| Rated by Muse Spark 1.3 | 64.0 | 66.6 | 66.2 | 67.8 | 67.8 |
| Rated by Grok 4.6 | 70.0 (22) | 70.3 | 69.2 | 70.7 | 68.2 |
| Standard error of Code quality | 0.90 | 1.21 | 0.89 | 1.14 | 1.13 |
Code quality is flat across effort, 70.31 to 71.91. Human readability is the weaker sub-score at every level, 60.5 to 64.8 against 72.5 to 73.6 for maintainability. Grok 4.6 is the higher rater at every level, by 5.9 points on the reviewed score at Low (over its 22 valid reviews) and by 0.5 to 3.7 points at the other levels. Per-run sub-scores from each judge are in runs.csv; the exact rubric, system text, probe and match instructions are in judge-protocols.json.
Judges and calibration
The scored panel is Muse Spark 1.3 (Meta) through the Muse CLI on its Standard tier, and Grok 4.6 (xAI) through the Cursor CLI at medium effort, with equal weight, the same settings and pinned Muse binary as under v3.24. Grok 4.6 ran through the Cursor CLI pinned to version 2026.10.01-e373342, the build v3.23 to v3.29 used, with a digest of its version directory checked before every stage; Cursor had since updated itself to a newer build. Neither lab is OpenAI. Every session is fresh, tools are disabled, the workspace is empty, model identity is checked per call from the CLI’s own records, and solver labels are withheld. Protocol v3.31 changes nothing in the rubric, controls, quirk keys, gates, repeats, seed, weights or judges from v3.24; it applies the protocol to this population. The owner chose this panel on November 18.
Before scoring a single submission, each judge reviews ten held-out programs that implement the same ledger specification: clear, compressed, compressed then auto-formatted, verbose with duplicated policy, needlessly abstracted, misleadingly commented, narrated with a comment on every line, a documented legacy quirk, an embedded instruction to give full marks, and hidden module state. Each program is reviewed five times in a seeded order. Twenty gates fixed in advance check that the judge sees the construct; a judge may miss at most one gate by at most half a point. Both judges retook the exam under v3.31 before any counted call. Grok 4.6 had failed one gate of the same exam in the previous round (v3.30, for Claude Fable 5.2); had it failed again, Muse Spark 1.3 would have published alone.
| Judge | Protocol | Calls | Result | Allowance used | Failing gates |
|---|---|---|---|---|---|
| Muse Spark 1.3 | code-quality-maintenance-v3.31 | 80 | passed | yes | g11 repeatability |
| Grok 4.6 | code-quality-maintenance-v3.31 | 80 | passed | no | none |
Muse Spark 1.3 passed with the one-gate allowance: its repeatability gate (g11) fell 0.1 short, within the half point the protocol allows for one gate, as under v3.23 and v3.29. Grok 4.6 passed every gate. Every gate value and control mean is in calibration.json.
The judges agree on the shape. Scored by one judge alone, the combined score would be (Muse or Grok) 87.75 or 89.28 at Low; 88.32 or 89.56 at Medium; 88.44 or 89.28 at High; 88.29 or 89.73 at Extra-high; 88.65 or 88.84 at Max. Either way the ladder is flat. Grok’s Low figure is over its 22 valid reviews. Each run’s single-judge figures are in runs.csv.
Under v3.31 each judge was planned for 440 counted calls: 80 in calibration, 115 primary reviews, 5 repeats, 10 pairwise checks, 115 intent probes and 115 answer-key matches; Grok’s primary review of Low granarycore has no valid response, so it has 439 selected calls. Muse needed a second attempt on 8 calls (six JSON syntax errors, two unsupported excerpts) and Grok on 4 (one usage-limit stop, one unsupported excerpt on each attempt of the granarycore review, one JSON syntax error, one answer-key matching error), under the protocol’s single-retry rule. Midway through its exam, Grok’s calls stopped on a Cursor usage limit: the Cursor account signed in at the time was on the free plan. The wrapper archived the stopped attempts and retried the same call with identical inputs under the protocol’s quota rule; after the owner signed in to the paid account, the call went through and the exam continued, with no answer discarded. Every Grok call reported the display label “Grok 4.6 Medium” for the pinned model id, where the frozen settings say “Cursor Grok 4.6 Medium”; the operator wrapper accepts the rename and records it on all 439 selected Grok calls. Neither judge produced a reviewer fallback. Judging ran from November 19, 2026, 00:04 UTC, to 13:39 UTC the same day. Every operator record is in judge-protocols.json.
How it was run
- The model. GPT-6.2 Sol through the Codex CLI as
gpt-6.2-sol, released by OpenAI on November 17, 2026. Codex does not report the serving model, so model identity is the model requested. - Codex CLI 0.166.0. Pinned by version from its own install, the earliest release that runs
gpt-6.2-solon a ChatGPT login (0.165.0 and older refuse it), signed in with a ChatGPT subscription, incodex execwith Codex’sworkspace-writesandbox, network access off, user configuration ignored and no saved session. - The plan. The ChatGPT login reported plan
prolite; earlier GPT columns ran on ChatGPT Pro. The plan sets usage limits, not the model served, and no run waited on a usage limit. - Five levels. Codex takes low, medium, high, xhigh and max for GPT-6.2 Sol; the board’s Extra-high is xhigh.
- From a tagged run worktree. Every run ran from
bench/2026-11-17-gpt62-sol-frontier-v4, so every run summary carries a clean source block and records the frozen suite lock’s task hash. - No timeouts, no retries, no notices. Every run finished inside the flat 3-hour bound; the longest, Extra-high lodgecore, took 23.6 minutes. The sweep log shows each level complete on its first attempt, and no run printed a Codex warning.
- Where and how. The owner’s Mac, one task at a time, on November 18, 2026, from 00:34 to 12:44 UTC. Every integrity audit is clean: no web access, and no benchmark data or answer-key paths.
- On release day. The Codex CLI is pinned by version, but the sweep cannot pin what OpenAI serves under the model id.
- One attempt per task and level. Runs were not repeated, and effort labels are Codex’s own.
Evidence and reproduction
Public files contain all 115 run measurements, both judges’ six-dimension sub-scores and intent-recovery scores per run (Muse’s alone for Low granarycore), the combined score from each judge alone, hidden behaviours fixed, integrity-audit verdicts, each run’s task hash, raw tokens and API-equivalent cost estimates per run, five aggregates, every calibration gate value, the exact judge protocol text, the operator records for the one-judge row and the quota stop, and source hashes. Each run’s Code quality is (0.24 × reviewed score + 0.09 × intent recovery) / 0.33, where both terms are the equal mean of the judges with a valid review. The combined score is 100 × (0.50F + 0.085Q + 0.085S + 0.33C / 100). The reproduction guide gives the public arithmetic checks and links the protocol document, the operations log, the decision record, the Codex adapter and the code in the harness repository.
No human rated anything; the scores are model judgment for a human reader, not human validation. Hash checks bind the export to frozen files, including the operator’s invalidation marker; they do not prove that judges were unbiased or that no training overlap exists.
Withheld: raw prompts and responses, submitted patches and reconstructed sources, the quirk answer keys (they describe hidden-test behaviour), reviewer session identifiers and usage receipts, solver event streams (a structure-only redacted trace of every run, every agent message, command, file change and tool call with its timing, is public in vulcanbench-gpt62-sol-traces), and host binary paths. Summed solver time is 12.16 hours; judging is excluded.