October 17, 2026 · Morgan Linton · 92 runs · Code quality protocol v3.26
Muse Wonder Full across every effort level
92 runs of Meta’s Muse Wonder Full through Muse Code on a Muse Code subscription, 23 tasks at each of the four effort levels Muse Code offers in Contributor mode, Low to Extra-high. Code quality carries 33% of the combined score and is judged for a human reader under the same rubric, controls and gates as the other Frontier v4 reports, but by a different panel: Claude Opus 5.5 and GPT-6.1 Sol, because Muse Spark 1.3, a judge for every other column, is a Meta model and not neutral for a Meta submission. Muse Wonder Full takes its place on the Frontier v4 leaderboard with that caveat attached. Two runs, one at High and one at Extra-high, hit the 3-hour task bound; they count in tasks passed, time and cost, and each level is shown both over its judged runs and with the timeout counted as 0. Cost is an estimate, because Meta lists no API price for Muse Wonder Full. For time and cost beside Claude Opus 5.5, GPT-6.1 Sol and GPT-6 Astra, see Analysis No. 02.
How the test works
A retired program to rebuild
Each of the 23 tasks is a legacy binary with a written specification and an issue. Its real behaviour departs from the specification in documented ways, and hidden tests check the rewrite against the binary.
One attempt per task and level
Muse Wonder Full works in Muse Code with the binary, the specification and the code, once per task at each effort level, inside a flat 3-hour bound, one task at a time.
Tests and two judges score it
Hidden tests give functional correctness. Two calibrated judges from labs other than Meta rate the code for a human reader and try to recover the documented departures.
Scores, time and cost per level
Each level gets a combined score, tasks passed, minutes and cost. Cost is an estimate from Muse Code’s token receipts at the Muse Wonder 1.0 list price.
Combined score = 50% functional correctness + 8.5% lint and complexity + 8.5% security + 33% Code quality, averaged over the judged runs in each level, as on every other board column. Frontier Code quality is the reviewed layer plus intent recovery; it is never compared with Routine v1 Code quality.
Across every effort level
Muse Wonder Full (muse-wonder-full-1.0) ran every task once at each of the four effort levels Muse Code offers in Contributor mode, 23 tasks per cell, through Muse Code 1.4.6 and then 1.4.9 on the owner’s Muse Code subscription, from October 13, 20:31 UTC, to October 17, 16:11 UTC, 2026, on the owner’s Mac in the local sandbox, one task at a time, with a pause for the subscription quota. Muse Code does not offer Max in Contributor mode, so these are all the levels. Combined score weights are 50% functional correctness, 8.5% lint and complexity, 8.5% security and 33% Code quality, judged for a named human reader by Claude Opus 5.5 and GPT-6.1 Sol with a ground-truth intent-recovery probe.
Combined score
86.95 to 88.27
Combined score is 86.95 at Low and peaks at 88.27 at Medium, then holds at 88.19 at High and slips to 87.59 at Extra-high, all within about one standard error (0.95 to 1.16) of each other. With the one timeout at each of the top two levels counted as 0, High is 84.36 and Extra-high 83.78.
Tasks passed
18, 21, 19 and 19 of 23
pass@1 is 0.783 (±0.088) at Low, 0.913 (±0.060) at Medium and 0.826 (±0.081) at High and Extra-high, where one task each ran out the 3-hour bound. Of the 231 hidden behaviours the tasks test for, it fixes 221, 227, 210 and 211.
Code quality
71.84 to 73.58
Code quality is flat across levels, 72.25, 72.29, 73.58 and 71.84, with standard errors of 1.56 to 1.86. The two judges disagree by about 17 points on the reviewed layer; see Judges and calibration.
Runtime and cost
27.3 to 36.2 min · ~$3.93 to ~$5.08 per task
Cost rises at every level, from an estimated $3.93 a task at Low to $5.08 at Extra-high. Time is 27.3 minutes at Low and Medium, 36.2 at High and 33.3 at Extra-high, the top two raised by a few long runs and their timeouts (medians 24.0 and 24.1). The whole sweep comes to an estimated $409.79.
| Metric | Low | Medium | High | Extra-high |
|---|---|---|---|---|
| Combined score | 86.95 | 88.27 | 88.19 | 87.59 |
| Standard error | 1.16 | 0.95 | 1.04 | 0.96 |
| Timeouts counted as 0 | 86.95 | 88.27 | 84.36 | 83.78 |
| Judged runs | 23 | 23 | 22 | 22 |
| Tasks passed | 18/23 | 21/23 | 19/23 | 19/23 |
| Hidden behaviours fixed | 221/231 | 227/231 | 210/231 | 211/231 |
| Code quality | 72.25 | 72.29 | 73.58 | 71.84 |
| Human readability | 64.8 | 64.6 | 66.3 | 63.4 |
| Minutes per task | 27.3 | 27.3 | 36.2 | 33.3 |
| Standard error of minutes | 6.2 | 4.0 | 7.9 | 7.0 |
| $ per task (estimate) | $3.93 | $4.09 | $4.72 | $5.08 |
| Standard error of $ per task | $0.82 | $0.61 | $0.82 | $0.95 |
Under the prior 50/15/15/20 profile applied to the same Code quality scores the ladder runs 89.18 to 90.45. Runtime and cost cover every run, the two timeouts included, as on the card. Medium mixes Muse Code versions: 21 tasks on 1.4.6 and 2 on 1.4.9.
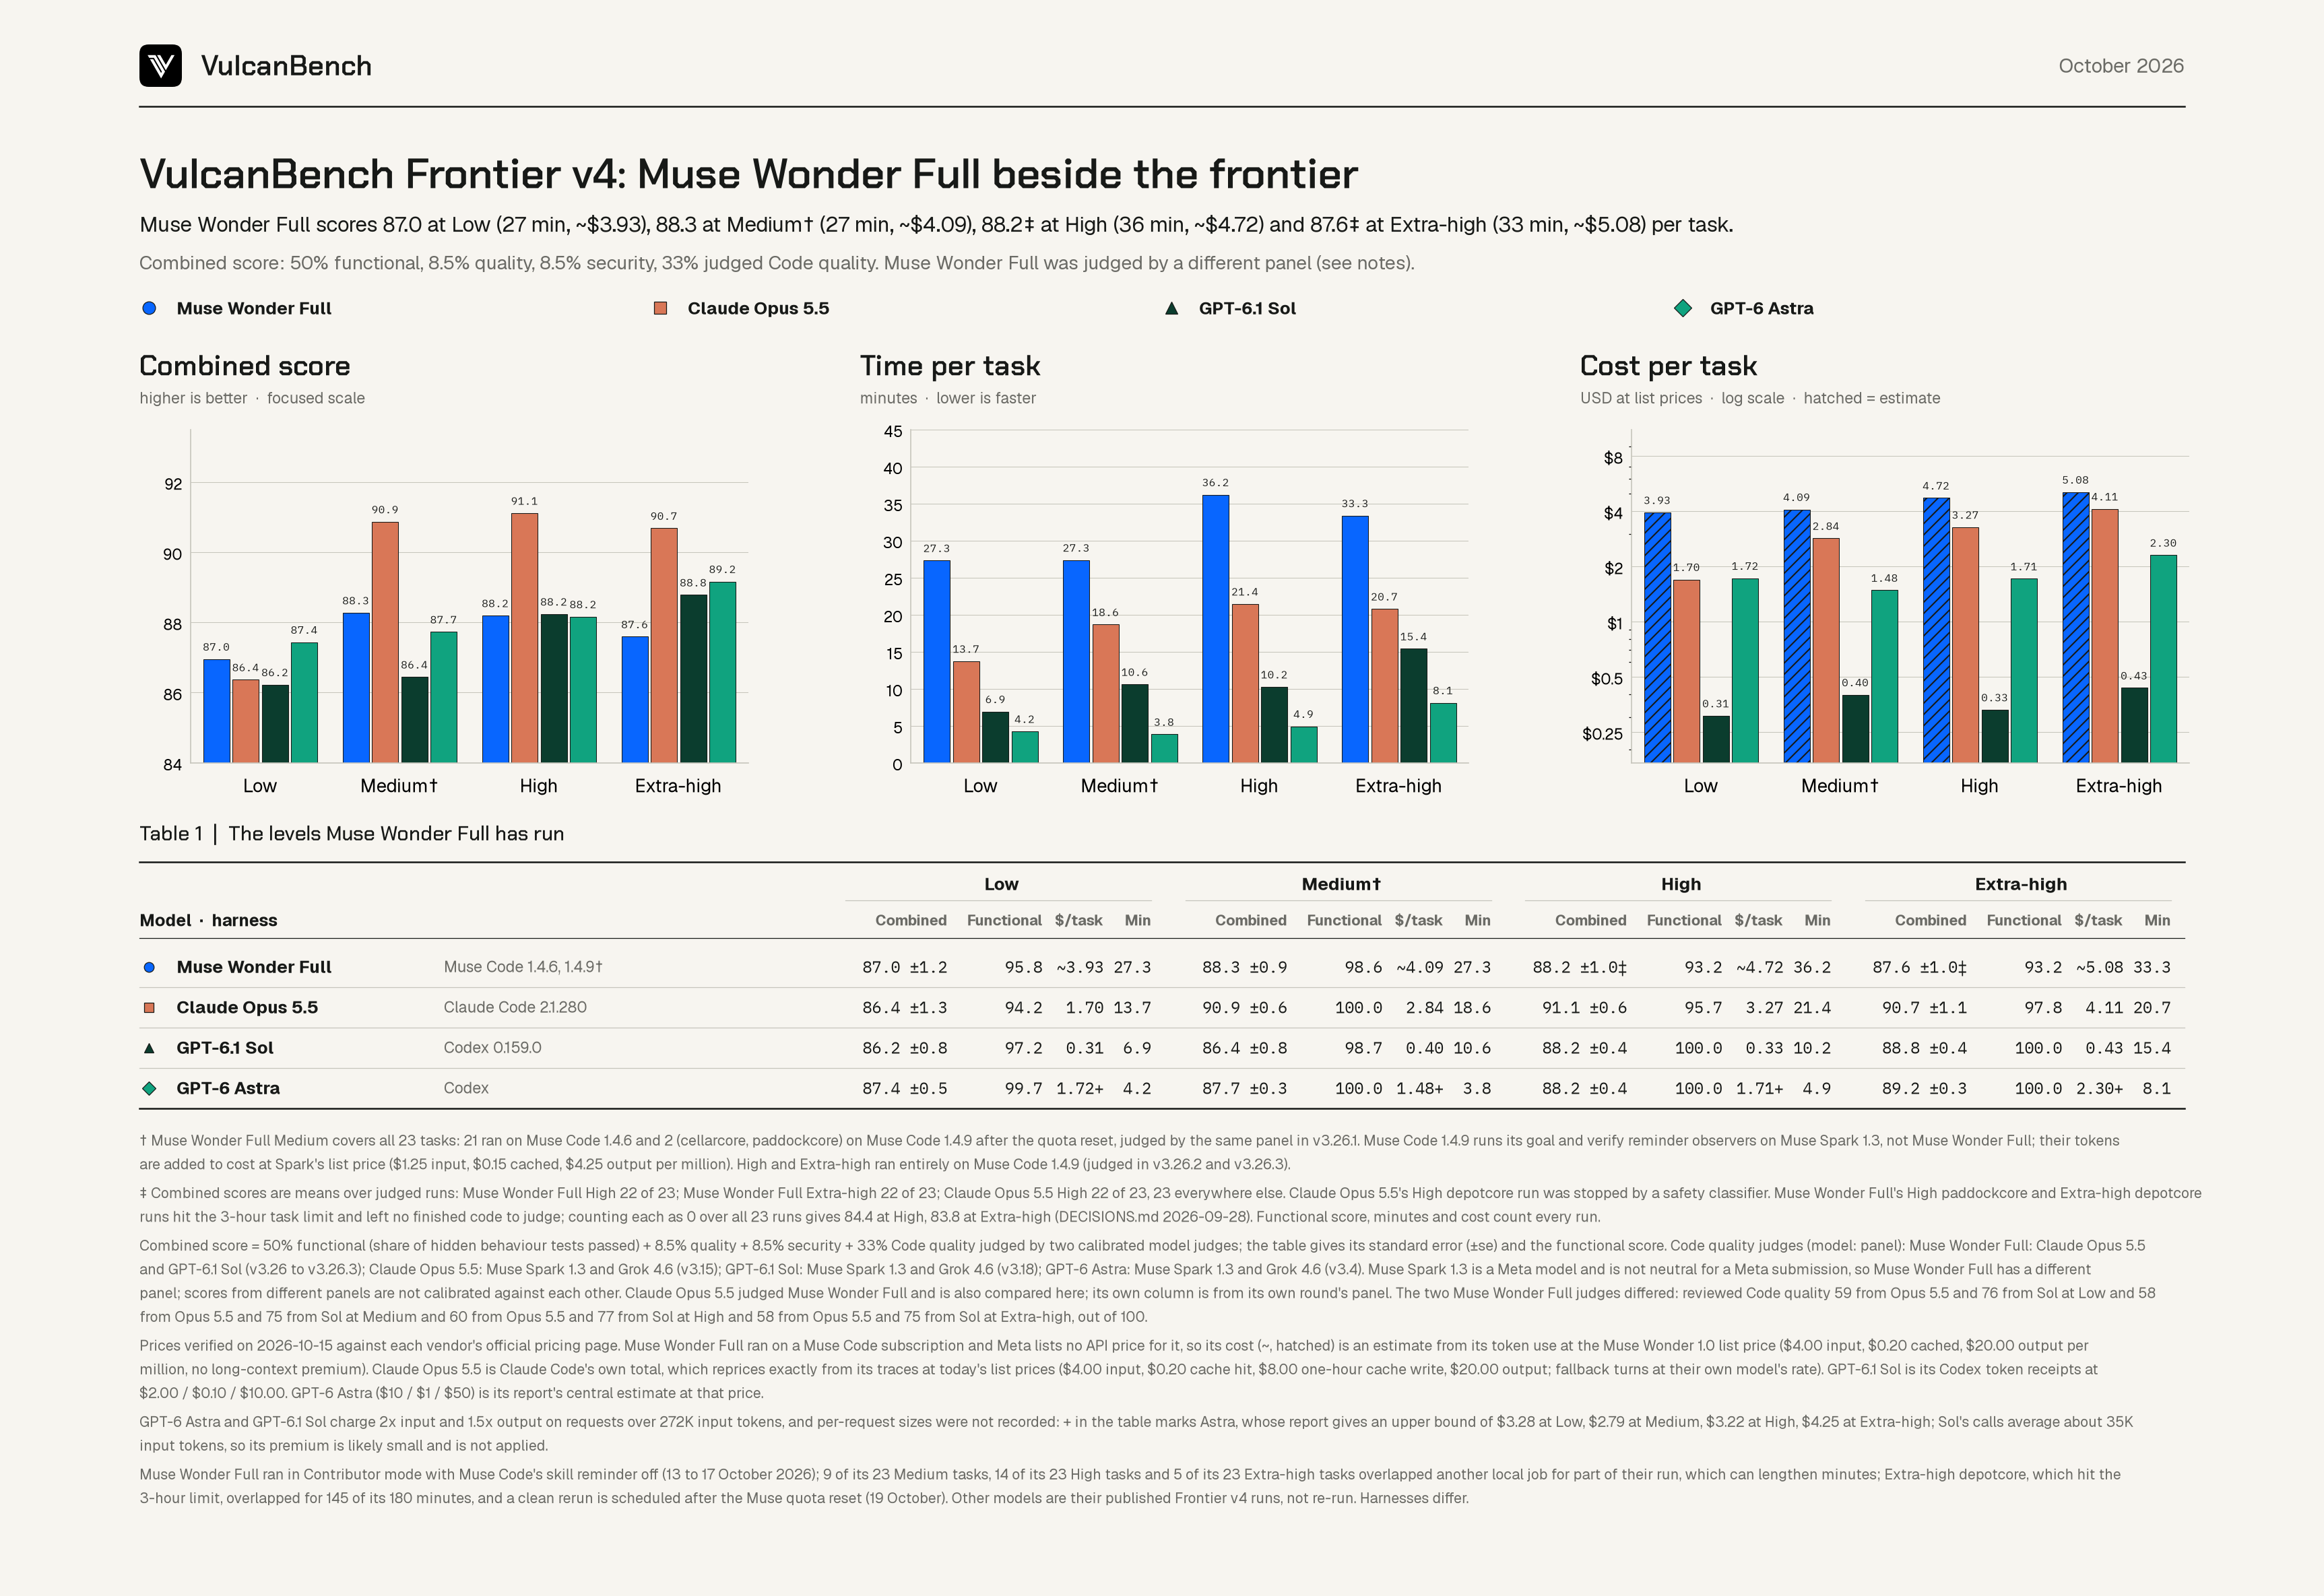
Muse Wonder Full gains little from effort: its combined score moves within 1.3 points from Low to Extra-high, peaking at Medium, while time and cost per task rise. Medium is its best level on both readings, over judged runs and with timeouts counted as 0, and it passes the most tasks there (21 of 23). These runs compare a model-and-harness combination, not an isolated base model, and its judges differ from the other columns’; the Frontier v4 leaderboard places every Muse Wonder Full level beside the other models with that caveat.
Combined score and Code quality by effort
n=23 runs at every level; the Judged column gives the runs with a published Code quality score (* fewer than 23, see the next section). Combined (33%) is the published score over the judged runs; Timeouts as 0 counts each timed-out run as 0 over all 23. Combined (20% profile) applies the prior 50/15/15/20 weights to the same Code quality scores for comparison. Code quality, human readability, maintainability and intent recovery are out of 100 and equal means of the two judges. Passed counts all 23 runs. Runtime is solver wall-clock per task over every run in the cell.
| Model / harness | Effort | Combined (33%) | SE | Timeouts as 0 | Combined (20% profile) | Code quality | Human readability | Maintainability | Intent recovery | Judged | Passed | Min/task |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Muse Wonder Full / Muse Code | Low | 86.95 | 1.16 | 86.95 | 89.18 | 72.25 | 64.8 | 70.1 | 85.1 | 23/23 | 18/23 | 27.3 |
| Muse Wonder Full / Muse Code | Medium | 88.27 | 0.95 | 88.27 | 90.45 | 72.29 | 64.6 | 68.9 | 87.0 | 23/23 | 21/23 | 27.3 |
| Muse Wonder Full / Muse Code | High | 88.19 | 1.04 | 84.36 | 90.24 | 73.58 | 66.3 | 70.4 | 87.6 | 22/23* | 19/23 | 36.2 |
| Muse Wonder Full / Muse Code | Extra-high | 87.59 | 0.96 | 83.78 | 89.86 | 71.84 | 63.4 | 69.3 | 86.5 | 22/23* | 19/23 | 33.3 |
Four factors by effort, over the judged runs. Functional correctness averages 95.82, 98.55, 97.43 and 97.40 from Low to Extra-high (95.82, 98.55, 93.20 and 93.17 over all 23 runs, the timeouts as 0); lint and complexity 78.77, 78.32, 78.96 and 78.60; security 100.00, 99.78, 99.77 and 100.00. Only the Code quality factor depends on the judges.
Intent recovery is scored over the specification departures a submission actually passed tests for. Every judged Muse Wonder Full run passed at least one, so no run fell back to the reviewed score alone. SE is one sample standard error across the cell’s judged tasks. It describes task sampling, not judge uncertainty, repeated runs or a significance test. Every published run is the equal mean of both judges, and neither judge produced a reviewer fallback.
Two runs without a Code quality score
- High paddockcore and Extra-high depotcore were still working when the flat 3-hour task bound stopped them, so neither left a finished submission to judge. Both count as failed tasks, are timed at 180 minutes, and are priced from the usage Muse Code reported before the bound ($13.51 and $23.64). Both tasks are solvable for the model: paddockcore passed at Extra-high and scored 0.93 and 0.87 of its hidden tests at Low and Medium, and depotcore passed at Low, Medium and High.
High and Extra-high are therefore judged on 22 of 23 runs. Following the rule the board applies to every column with timeouts (decided September 28, 2026), each level is published two ways: the combined score over its judged runs (88.19 and 87.59), and with the timeout counted as 0 over all 23 (84.36 and 83.78). The board’s best tag and effort suggestions use the second figure.
Cost, tokens and the reminder observers
Meta lists no API price for Muse Wonder Full: it is not served on the Model API and is available only through the Muse Code subscription. Cost here is therefore an estimate. Muse Code’s token receipts are priced at the Muse Wonder 1.0 list price, checked October 15, 2026 on Meta’s pricing page: $4.00 uncached input, $0.20 cached input and $20.00 output per million tokens, the same at any context length. The runs used the owner’s Muse Code subscription, so these are API-equivalent estimates, not bills; judging is excluded.
Reminder observers on Muse Spark 1.3. Muse Code 1.4.9 runs its end-of-run goal and verify reminder observers on Muse Spark 1.3, whatever the main model, where 1.4.6 ran them on the main model. Those calls are recorded apart from Muse Wonder Full’s totals and priced at Muse Spark 1.3’s list price, checked October 16 ($1.25 input, $0.15 cached, $4.25 output per million). They appear on 46 of the 48 runs made on 1.4.9 (the two timeouts reached no end of run), 4.77 million tokens in all, and add an estimated $5.97 to the sweep. Every other call in every run was Muse Wonder Full.
| Effort | Runs | $/task | ±SE | Reminders | Level total | Tokens/task | Output/task | Min/task |
|---|---|---|---|---|---|---|---|---|
| Low | 23 | $3.93 | $0.82 | $0.00 | $90.43 | 7.99M | 68.6K | 27.3 |
| Medium | 23 | $4.09 | $0.61 | $0.30 | $93.96 | 8.50M | 73.8K | 27.3 |
| High | 23 | $4.72 | $0.82 | $2.83 | $108.55 | 10.37M | 89.3K | 36.2 |
| Extra-high | 23 | $5.08 | $0.95 | $2.84 | $116.86 | 11.37M | 90.2K | 33.3 |
| Full sweep | 92 | $4.45 | $5.97 | $409.79 | 879M | 47.6 h |
Reading the cost. Reminders is the level’s Muse Spark 1.3 reminder-observer cost, already inside $/task and the level total. Tokens are Muse Wonder Full’s input (cached included, the bulk) and output as Muse Code reports them; output includes reasoning. Analysis No. 01 traces why Muse Wonder Full uses so many: about three times the model calls and ten times the output of GPT-6.1 Sol at Low, not slower steps. Per-run figures are in economics.json and runs.csv.
On the Frontier v4 board
Muse Wonder Full’s best level, Medium at 88.27 ± 0.95 (n=23), ranks 23rd of the board’s 67 model and effort columns, between GPT-6.1 Sol at Max (88.35 ± 0.33) and GPT-6.1 Sol at High (88.23 ± 0.40), within the errors of both. High ranks 25th, Extra-high 29th and Low 32nd. Medium carries the best tag on either reading of the timeouts, and because the four levels sit within 1.3 points the board’s routine and rough effort suggestions pick Low, the cheapest. The leaderboard carries every column; Muse Wonder Full’s cells carry the §§ footnote with the disclosures on this page.
Read these placements with the panel in mind. Every other column except Grok 4.7’s is judged by Muse Spark 1.3 and Grok 4.6, and Grok 4.7’s by Muse Spark 1.3 and GPT-6.1 Sol; Muse Wonder Full’s by Claude Opus 5.5 and GPT-6.1 Sol. Scores from different panels are not calibrated against each other, so gaps of a point or two between Muse Wonder Full and its neighbours are not a reliable order.
What Code quality measures
Every judge receives the same rubric, frozen by hash before any review. It names the reader it scores for: an engineer who has never seen the code, reads it top to bottom without running it, and must make a correct change in one sitting. It tells the judge that its own ease at parsing dense code is not evidence of readability. Six dimensions are scored 0 to 4 in half steps against written anchors: naming, presentation and intent form the human readability sub-score; structure, changeability and verifiability form the maintainability sub-score. Every score must cite an exact excerpt from the code and a concrete consequence for that reader. The host computes the sub-scores; the judge does no arithmetic.
The 33 points have three designed layers. The reviewed panel carries 24 points. An intent-recovery probe carries 9: the judge, given only the specification and the code, lists where the code departs from the specification, and a separate call matches that list against a frozen answer key, over the departures the submission passed tests for. The third layer, measured maintenance, is designed for 12 points but is not yet built, so the pre-registered 24 plus 9 split is in force. Frontier Code quality is therefore the reviewed layer plus intent recovery, and it is never compared with Routine v1 Code quality, which is scored on a different suite and population.
| Component | Low | Medium | High | Extra-high |
|---|---|---|---|---|
| Code quality | 72.25 | 72.29 | 73.58 | 71.84 |
| Human readability | 64.8 | 64.6 | 66.3 | 63.4 |
| Maintainability | 70.1 | 68.9 | 70.4 | 69.3 |
| Intent recovery | 85.1 | 87.0 | 87.6 | 86.5 |
| Rated by Claude Opus 5.5 | 58.9 | 58.2 | 59.6 | 57.8 |
| Rated by GPT-6.1 Sol | 76.0 | 75.3 | 77.1 | 74.9 |
| Standard error of Code quality | 1.84 | 1.86 | 1.81 | 1.56 |
Intent recovery is strong at every level, 85.1 to 87.6: given only the specification and the code, the judges find most of the departures Muse Wonder Full implemented. The reviewed layer is weaker, and human readability, 63.4 to 66.3, is its weakest part at every level. Per-run sub-scores from each judge are in runs.csv; the exact rubric, system text, probe and match instructions are in judge-protocols.json.
Judges and calibration
A different panel. The scored panel is Claude Opus 5.5 (Anthropic) at medium effort through Claude Code 2.1.300 on a Claude subscription, and GPT-6.1 Sol (OpenAI) at medium effort through Codex CLI 0.159.0, with equal weight. Muse Spark 1.3 judges every other column; it is a Meta model, so it is not neutral for a Meta submission and was excluded, as Grok 4.6 was for Grok 4.7. Both judges are from labs other than Meta. Every session is fresh, tools are disabled, the workspace is empty, model identity is checked per call, and solver labels are withheld. Claude Opus 5.5 is also a compared model on the card and the board; its own column comes from its own round, judged by Muse Spark 1.3 and Grok 4.6.
Opus 5.5 replaced Grok 4.7. Under protocol v3.25 the owner first chose Grok 4.7 and GPT-6.1 Sol. GPT-6.1 Sol passed the calibration exam and finished every review, probe and match for Low and the first 21 Medium runs. Grok 4.7, which had never judged before, stopped on its first exam call when the Cursor account ran out of usage: a stop, not an exam failure, and no Grok 4.7 vote exists. Protocol v3.26 seats Claude Opus 5.5 in its place and keeps GPT-6.1 Sol’s finished v3.25 work as a scored sibling: v3.26 refused to prepare unless the manifest, evidence, signals, controls, quirk keys, diagnostic selection and calibration order were byte-identical to v3.25’s, and it re-checked Sol’s protocol hash before every stage. Opus 5.5 took the exam under v3.26 before any counted call. The later rounds, v3.26.1 for the two Medium runs made on Muse Code 1.4.9, v3.26.2 for High and v3.26.3 for Extra-high, reuse both exam verdicts with no new exam, each binding them by hash, because each is another level of the same sweep. The rubric, prompts, schemas, seed, repeats, gate allowance and weights are identical in all five rounds.
Before scoring a single submission, each judge reviews ten held-out programs that implement the same ledger specification: clear, compressed, compressed then auto-formatted, verbose with duplicated policy, needlessly abstracted, misleadingly commented, narrated with a comment on every line, a documented legacy quirk, an embedded instruction to give full marks, and hidden module state. Each program is reviewed five times in a seeded order. Twenty gates fixed in advance check that the judge sees the construct; a judge may miss at most one gate by at most half a point.
| Judge | Protocol | Calls | Result | Allowance used | Failing gates |
|---|---|---|---|---|---|
| Claude Opus 5.5 | code-quality-maintenance-v3.26 | 80 | passed | no | none |
| GPT-6.1 Sol | code-quality-maintenance-v3.25 | 80 | passed | no | none |
Both judges passed every gate with no allowance used. Every gate value and control mean is in calibration.json.
The judges disagree on level. Claude Opus 5.5 rates Muse Wonder Full’s reviewed Code quality about 17 points below GPT-6.1 Sol at every level: 58.9 against 76.0 at Low, 58.2 and 75.3 at Medium, 59.6 and 77.1 at High, 57.8 and 74.9 at Extra-high. Both passed the same exam, so this is a difference in how strictly each scores real code, not a failed judge. The published score is their mean. Scored by one judge alone, the combined score would be 85.02 (Opus 5.5) or 88.88 (Sol) at Low, 86.24 or 90.30 at Medium, 86.14 or 90.24 at High, and 85.67 or 89.51 at Extra-high; the levels fall in the same order either way. Each run’s single-judge figures are in runs.csv.
Each judge made 90 primary reviews, 90 intent probes, 90 answer-key matches, 6 repeats and 4 pairwise checks across the rounds. Opus 5.5 needed a second attempt on one call and Sol on twelve, under the protocol’s single-retry rule. Nine of Sol’s answer-key matches are published through a standing operator rule: both attempts failed only because Sol numbered the departures from one instead of zero, so the wrapper moved the indexes down by one with every status untouched and kept the original in the receipt. Neither judge produced a reviewer fallback.
How it was run
- Contributor mode, skill reminder off. Meta serves Muse Wonder Full only through Muse Code, as
muse-code:muse-wonder-full-1.0-contributorin Contributor mode, where Meta may train on submitted prompts and completions. The owner accepted that, so VulcanBench Frontier v4 task content may enter future Meta training data. Muse Code’s skill-reminder plugin was off for every run, on Meta’s advice that it was costly on Muse Wonder. Contributor mode offers no Max level. - Muse Code versions. Low (23 tasks) and the first 21 Medium tasks ran on Muse Code 1.4.6; the last two Medium tasks (cellarcore and paddockcore), High and Extra-high ran on Muse Code 1.4.9, for the reason in the next item. Medium therefore mixes versions, 21 runs on 1.4.6 and 2 on 1.4.9, and is shown with a dagger on the card.
- Quota pause and reset. The Muse Code subscription’s weekly limit ran out at October 14, 22:20 UTC, with cellarcore and paddockcore still to run at Medium; the interrupted cellarcore attempt was set aside and never scored. On October 16 Meta reset the quota and released Muse Code 1.4.9, described as more token-efficient. The owner chose to run the rest of the sweep on 1.4.9 and keep what had already run, so the last two Medium tasks, High and Extra-high ran on 1.4.9 from a second run root that continues the first, from October 16, 11:31 UTC.
- From tagged run worktrees. The 1.4.6 runs ran from
bench/2026-10-13-musewonder-full-v2-lowand the 1.4.9 runs frombench/2026-10-16-musewonder-full-149, so every run summary carries a clean source block and records the frozen suite lock’s task hash. No hash bridge was needed. - One transport rerun. One High snapcore attempt stopped 8 minutes in on a Meta API transport error after Muse Code’s own retries. Under the owner’s rule an infrastructure stop is not a result, so the attempt was archived unscored and the task rerun; the rerun passed every hidden test in 18.8 minutes.
- Overlapping jobs. A per-minute log recorded any other local benchmark process beside the sweep from Medium on. It flags 9 of the 23 Medium tasks, 14 of the 23 High tasks and 5 Extra-high tasks (depotcore, granarycore, lodgecore, stampcore and paddockcore, beside another session’s Frontier v5 jobs from 10:08 to 15:46 UTC on October 17) for part of their run. Overlap can lengthen minutes. For Extra-high depotcore it may also have cost the run its score: it hit the 3-hour limit with 145 of its 180 minutes overlapped, after finishing clean at High in 111 minutes. A clean rerun of that task is scheduled after the Muse quota reset on October 19, and this page will be updated with it; each run’s logged overlap minutes are in runs.csv.
- Where and how. The local sandbox on the owner’s Mac (the same host as every published Frontier v4 column), a flat 3-hour task timeout, one task at a time. Every integrity audit is clean: no web access, no benchmark data or answer-key paths, and nothing touched outside the workspace except Muse Code’s own per-run session folder.
- Judging windows. GPT-6.1 Sol judged Low and Medium under v3.25 and Claude Opus 5.5 under v3.26 on October 15; v3.26.1 ran on October 16 and v3.26.2 and v3.26.3 on October 17.
- One attempt per task and level. Runs were not repeated, and effort labels are Muse Code’s own.
Evidence and reproduction
Public files contain all 92 run measurements, both judges’ six-dimension sub-scores and intent-recovery scores per judged run, the combined score from each judge alone, hidden behaviours fixed, integrity-audit verdicts, each run’s task hash, Muse Code version, model calls by model, raw tokens, reminder-observer usage, the estimated cost, the logged overlap minutes, four aggregates, every calibration gate value, the exact judge protocol text, how the five judging rounds bind each other, and source hashes. Each run’s Code quality is (0.24 × reviewed score + 0.09 × intent recovery) / 0.33, where both terms are the equal mean of the two judges. The combined score is 100 × (0.50F + 0.085Q + 0.085S + 0.33C / 100). The reproduction guide gives the public arithmetic checks and links the protocol document, the decision record and the code in the harness repository. Redacted agent traces are published separately at vulcanbench-musewonder-full-traces.
No human rated anything; the scores are model judgment for a human reader, not human validation. Hash checks bind the export to frozen files; they do not prove that judges were unbiased or that no training overlap exists.
Withheld: raw prompts and responses, submitted patches and reconstructed sources, the quirk answer keys (they describe hidden-test behaviour), reviewer session identifiers and usage receipts, the quota-stopped and transport-stopped attempts, and host binary paths. Summed solver time is 47.59 hours; judging is excluded.